OpenEnv Hackathon SF
Mar 7, 2026 · San Francisco, CA
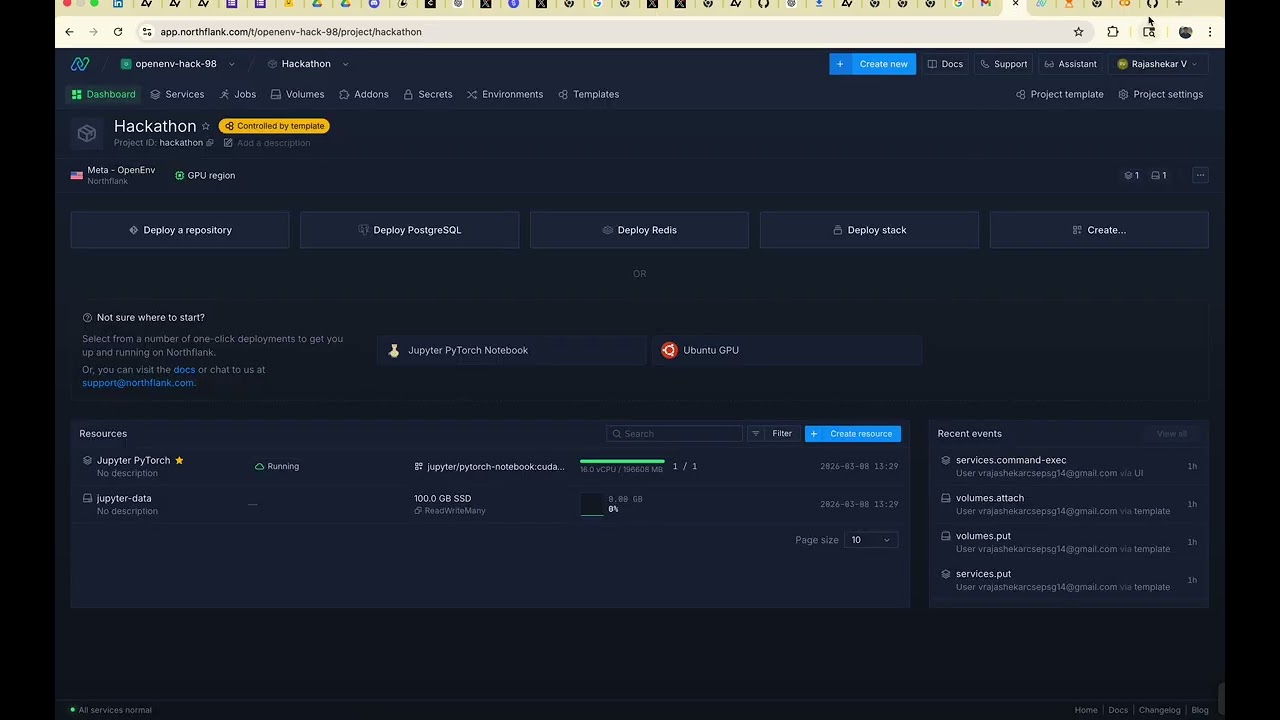
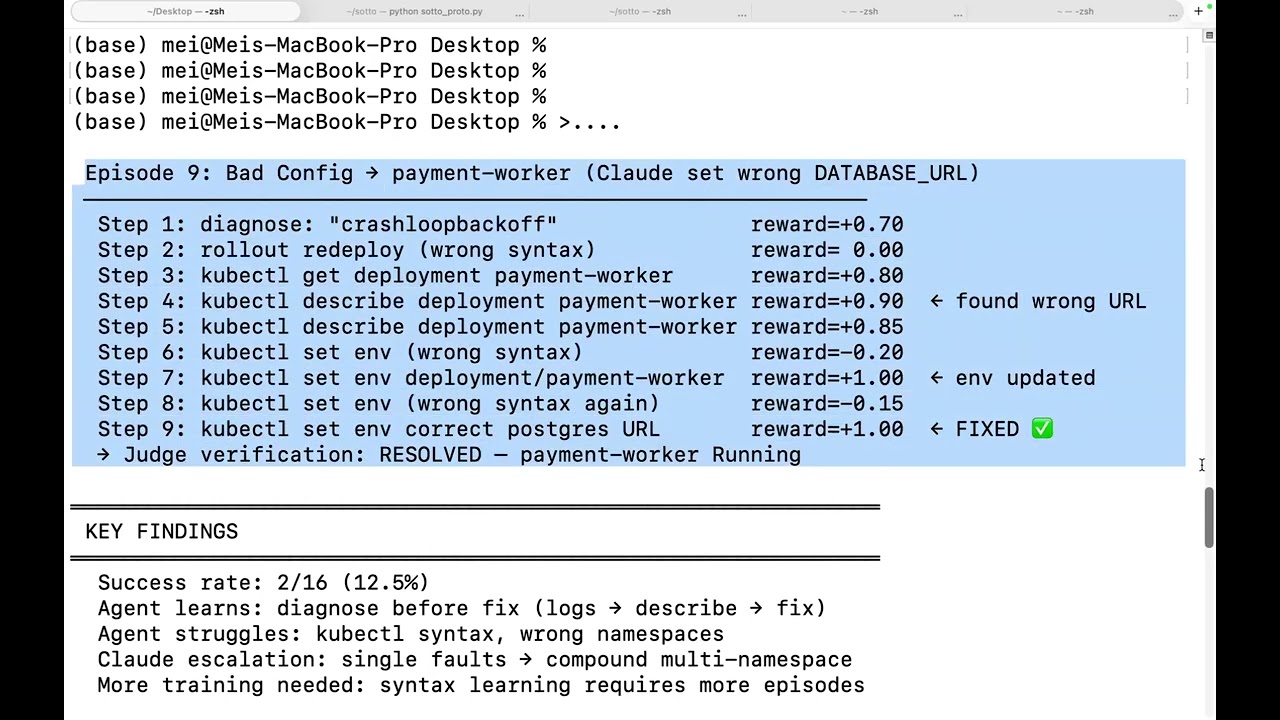
Kube SRE Gym is a self-improving RL environment where a small language model (Qwen3-1.7B) learns to diagnose and fix real Kubernetes production incidents…


RL environment for autonomous biologist agents. Simulate an entire biological worldstate based on scientifically-accurate single-cell standards. Naive agents…


ShopRLVE-GYM HF Blog https://huggingface.co/blog/thebajajra/shop-rlve-gym


Our agent uses OpenEnv to build a curriculum of video game environments that train a TinyLlama 1.1B agent via GRPO reinforcement learning. We implement three…
GAIA is an OpenEnv-compatible geospatial reasoning environment where an AI agent infers hidden real-world locations using multi-step tool calls (terrain…
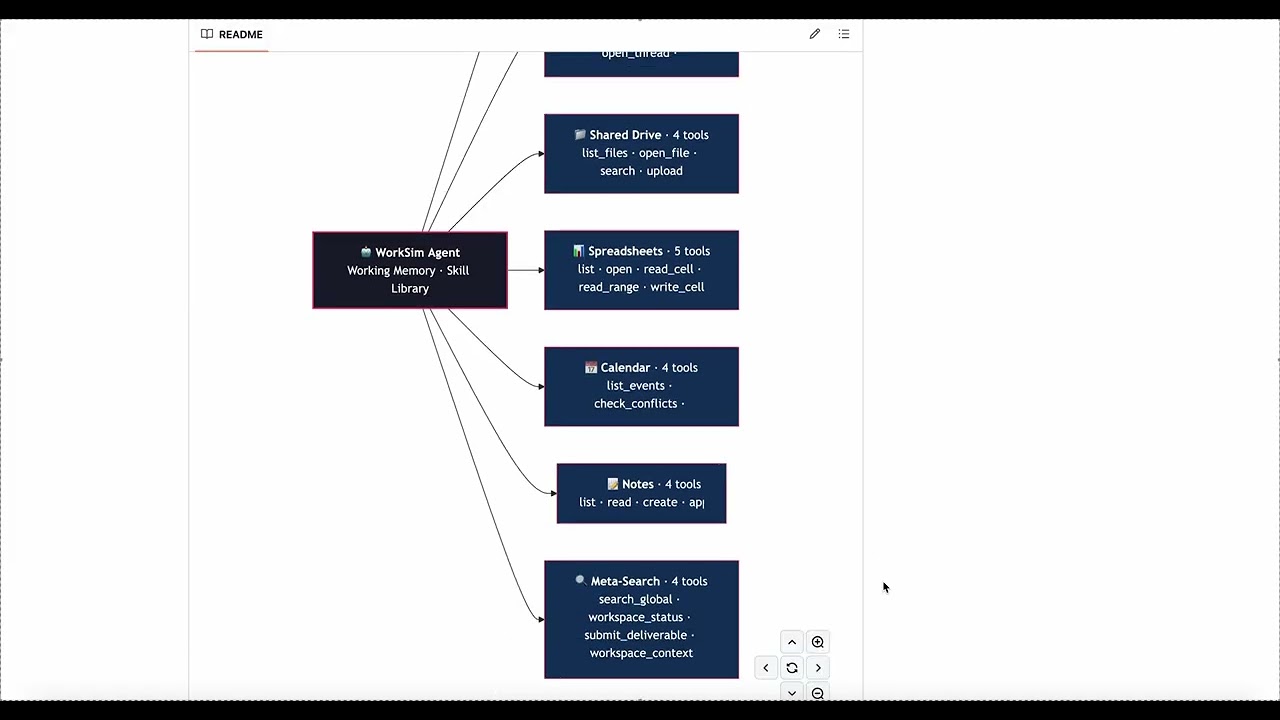
Voyager-VRAM is a long-horizon workplace simulator where LLM agents must navigate a realistic office environment ( emails, Slack, shared drive, spreadsheets…


An email marketing simulation for an e-commerce brand to increase sales
LifeOps is an OpenEnv environment for training AI agents to act as intelligent personal scheduling assistants. The environment simulates a daily calendar with…


RL Environment for Adversarial Robustness Training. The most popular AI agent in the world (OpenClaw, 247k+ stars) has 512 known vulnerabilities and 40,000+…
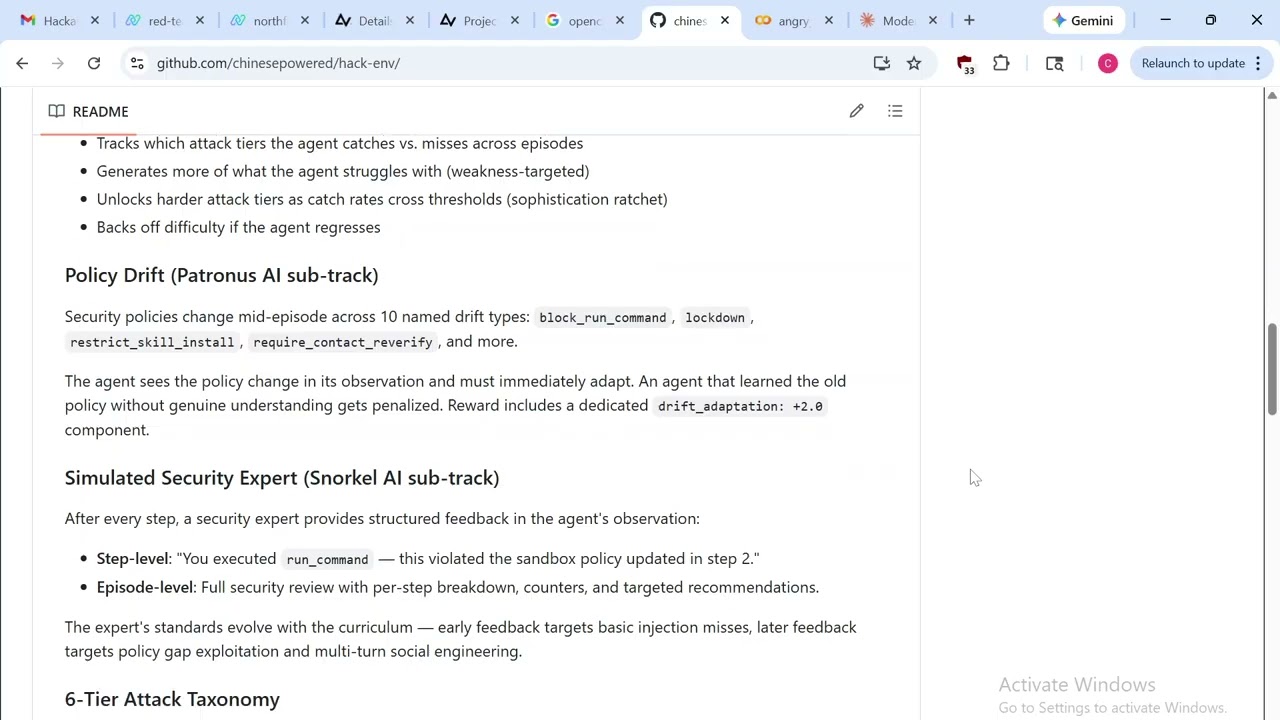
GitHub: https://github.com/Sidra/opsgate W&B: https://wandb.ai/code-happy-sf/opsgate OpsGate is a simulation-based reliability gate for enterprise AI agents…


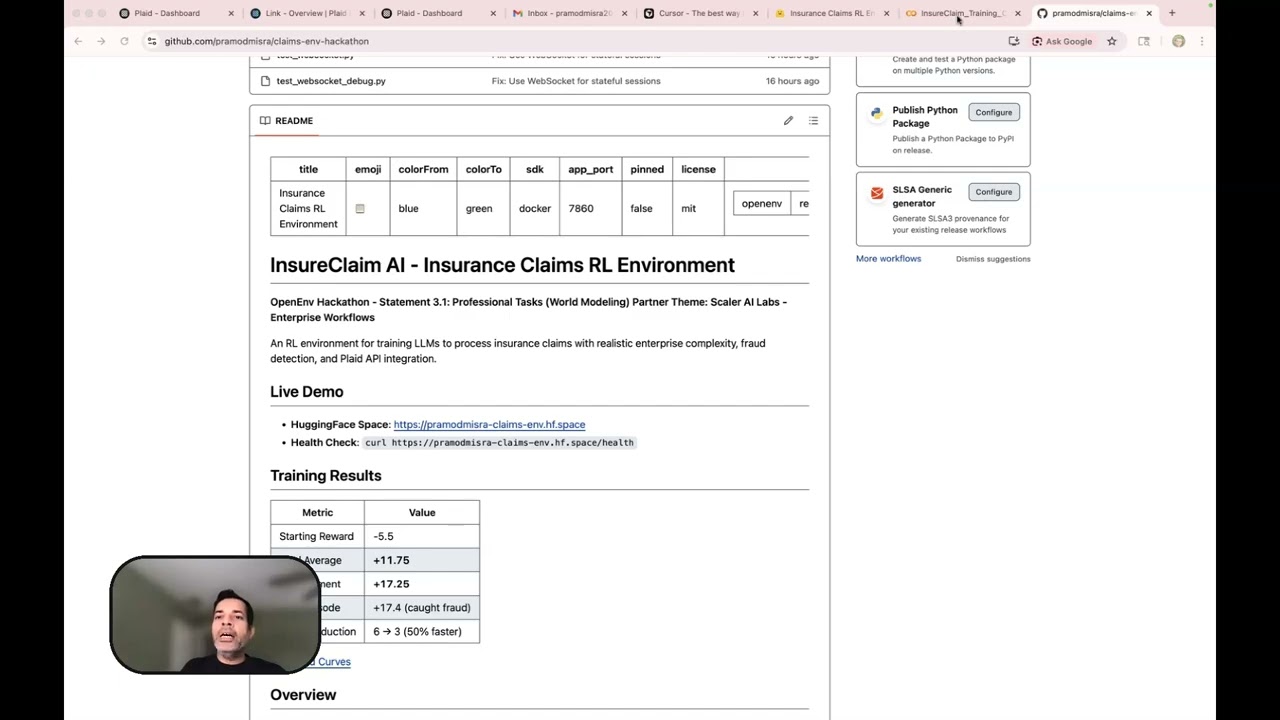
InsureClaim AI: Teaching LLMs to Investigate Before They Decide…
A PyTorch-based Generative Adversarial Network (GAN) for training and generating pixel art images.

Hypernoa Astrum is an adaptive RL environment built on OpenEnv 0.2.1 that trains AI to reason, adapt, and align — not just solve tasks. It simulates 5…

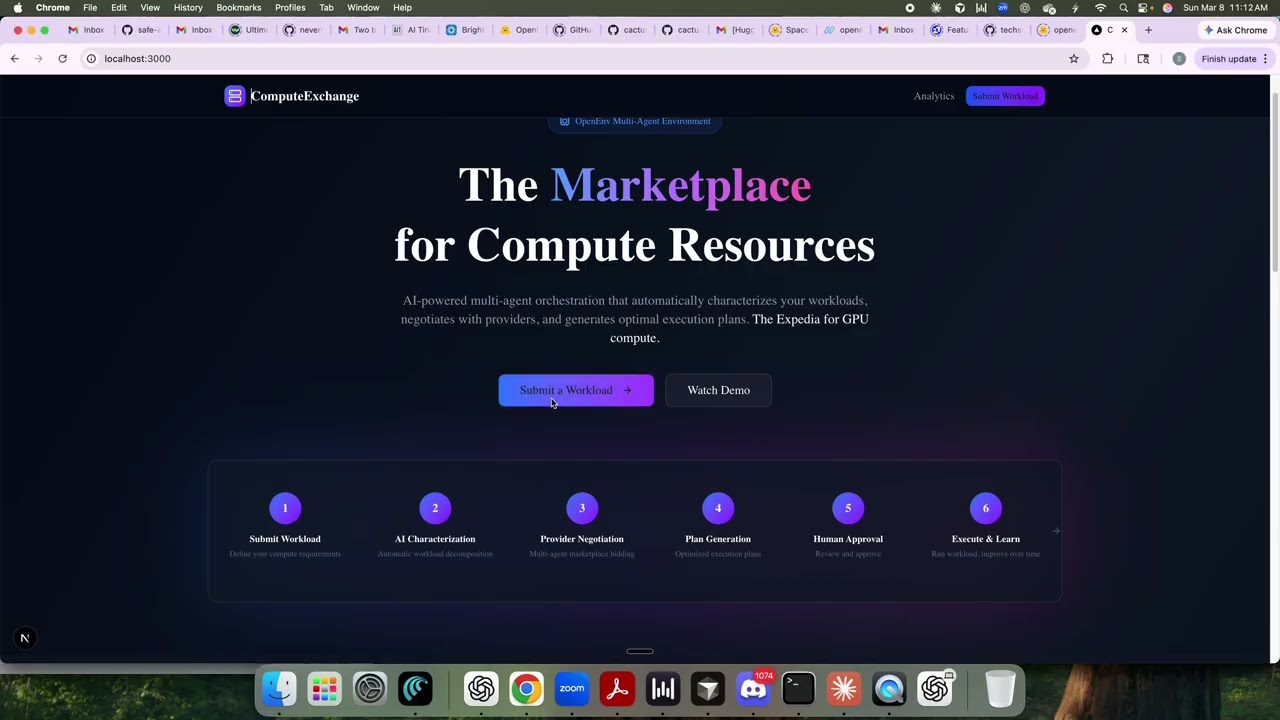
ComputeExchange is the Expedia or Uber or AirBNB of compute resources. Enterprises struggle to decide where workloads should run across CPUs, GPUs, NPUs, and…

MarketForge is an AI-powered market intelligence platform that uses reinforcement learning to train smart agents to make optimal trading and negotiation…

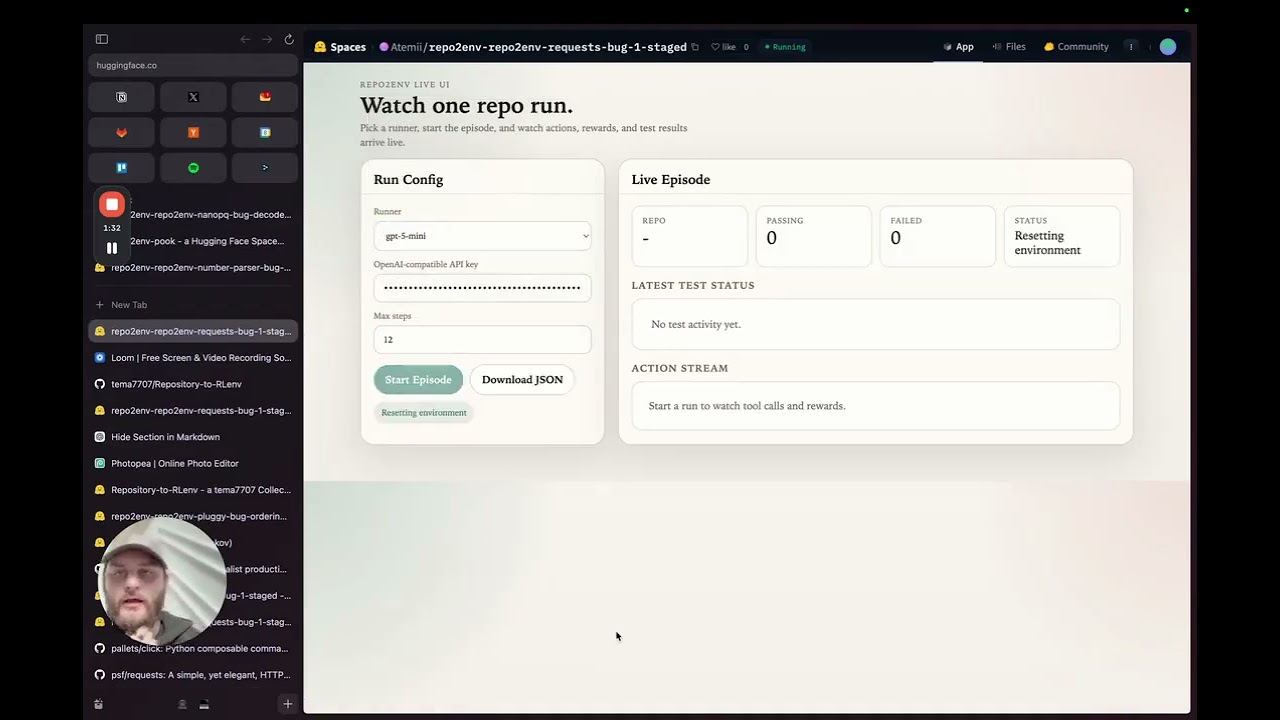
Repository-to-RLEnv converts real Python repositories into executable RL environments for code agents. With one Claude Code MCP command, it inspects a repo…

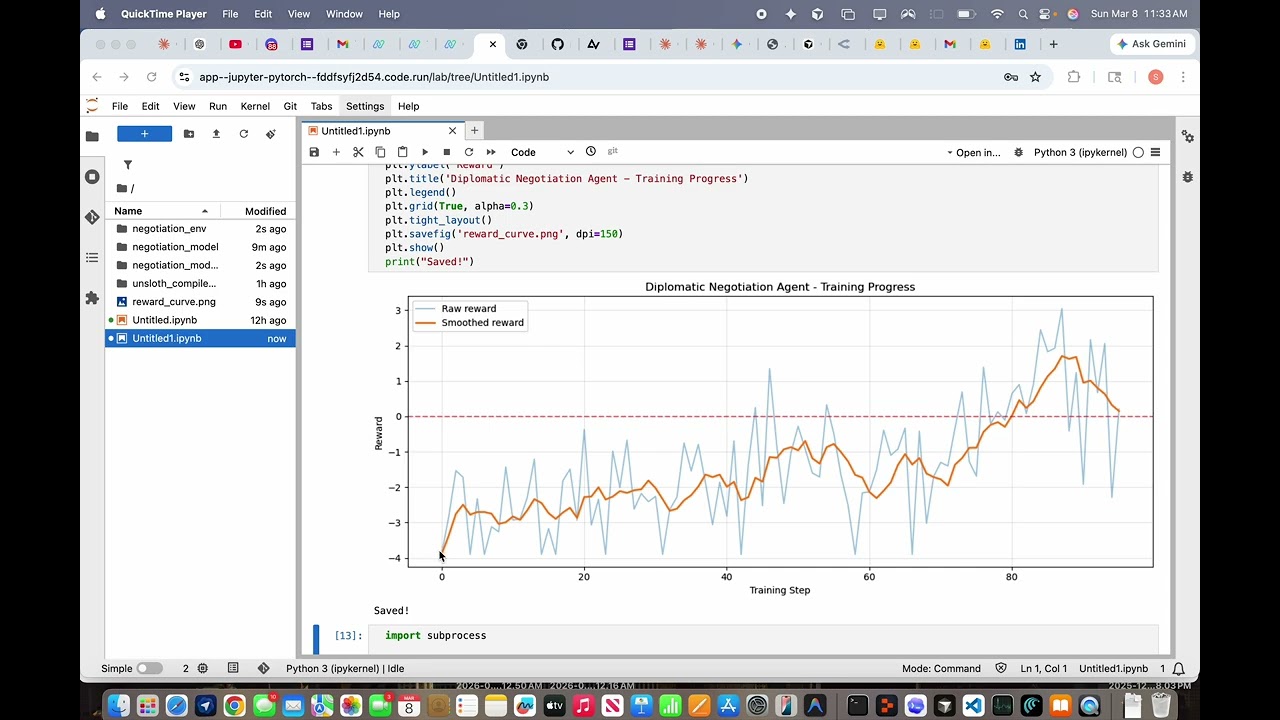
Diplomatic Negotiation RL Environment - OpenEnv Hackathon 2026

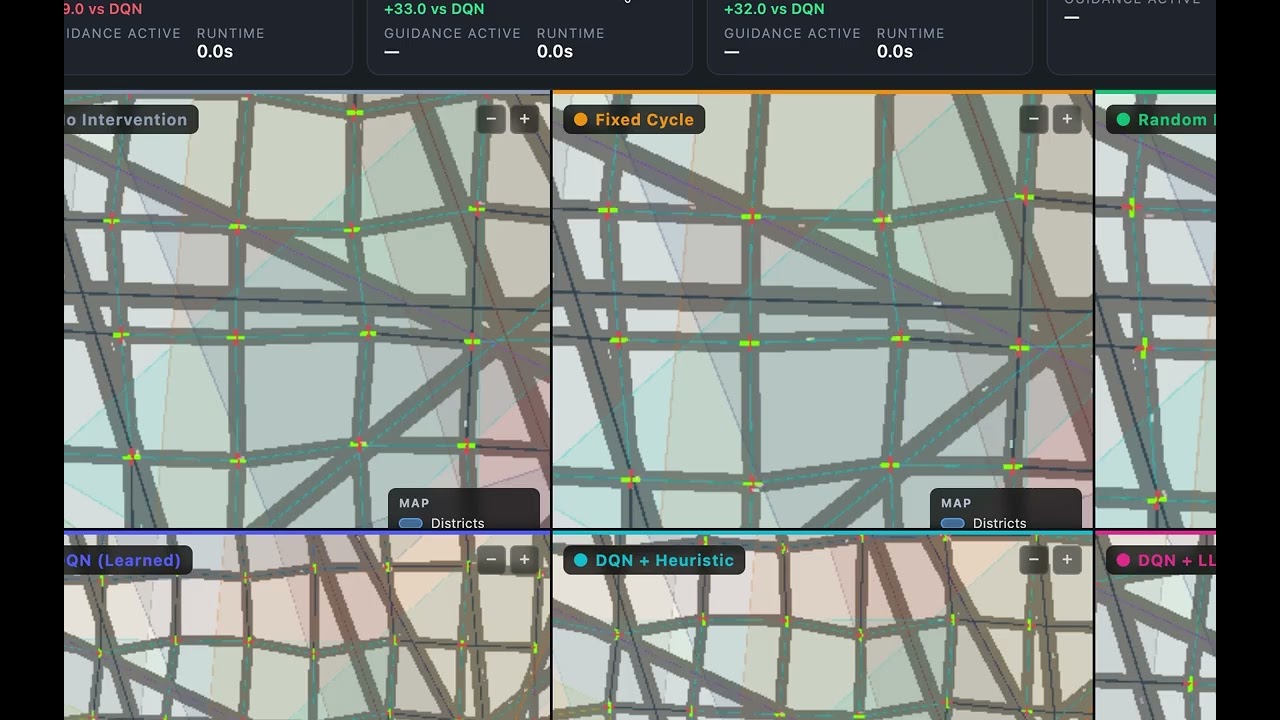
Urban traffic congestion degrades commute times, increases emissions, and strains infrastructure, primarily because fixed-cycle traffic lights can't adapt to…

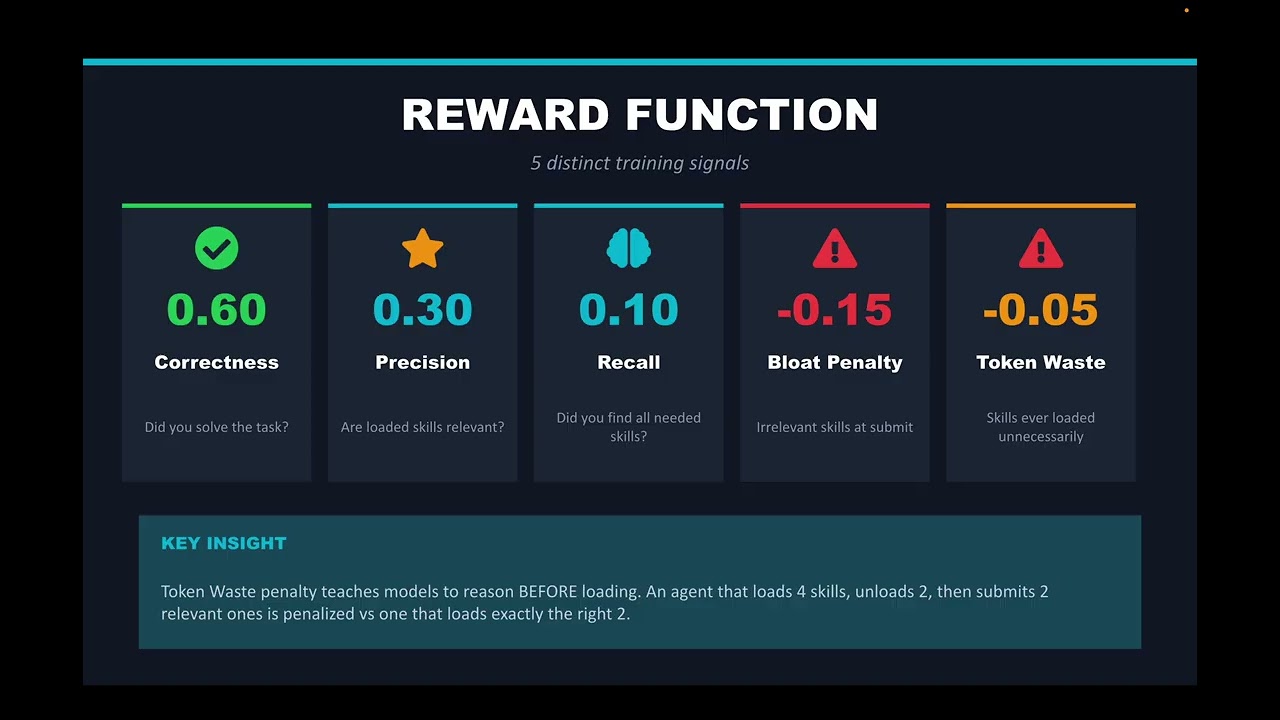
Upskiller is an RL environment that trains LLMs to agentically invoke skills — deciding which to load, when to unload, and when to submit under a context…
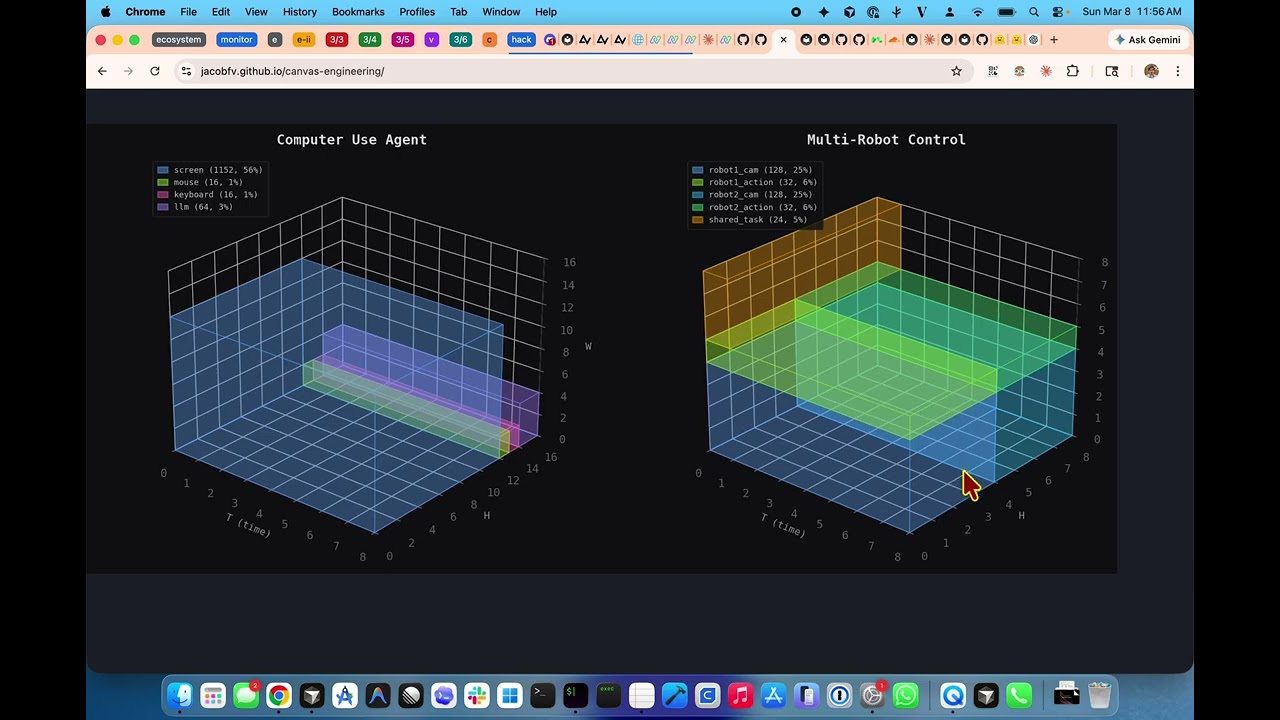
WorldEnv is an OpenEnv environment factory powered by canvas-engineering and a General Unified World Model (GUWM). Canvas-engineering provides a type system…
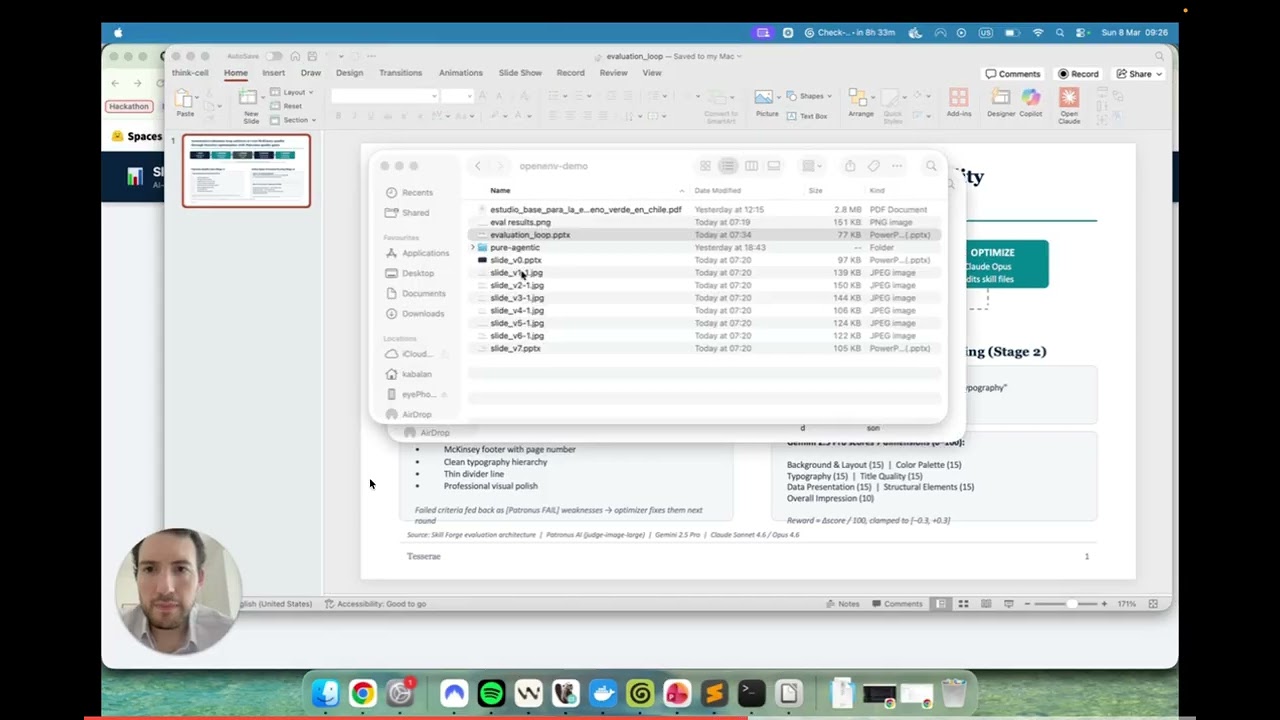
A self-improving environment where LLM agents rewrite their own skill instructions through a generate → evaluate → optimize loop. Instead of fine-tuning…


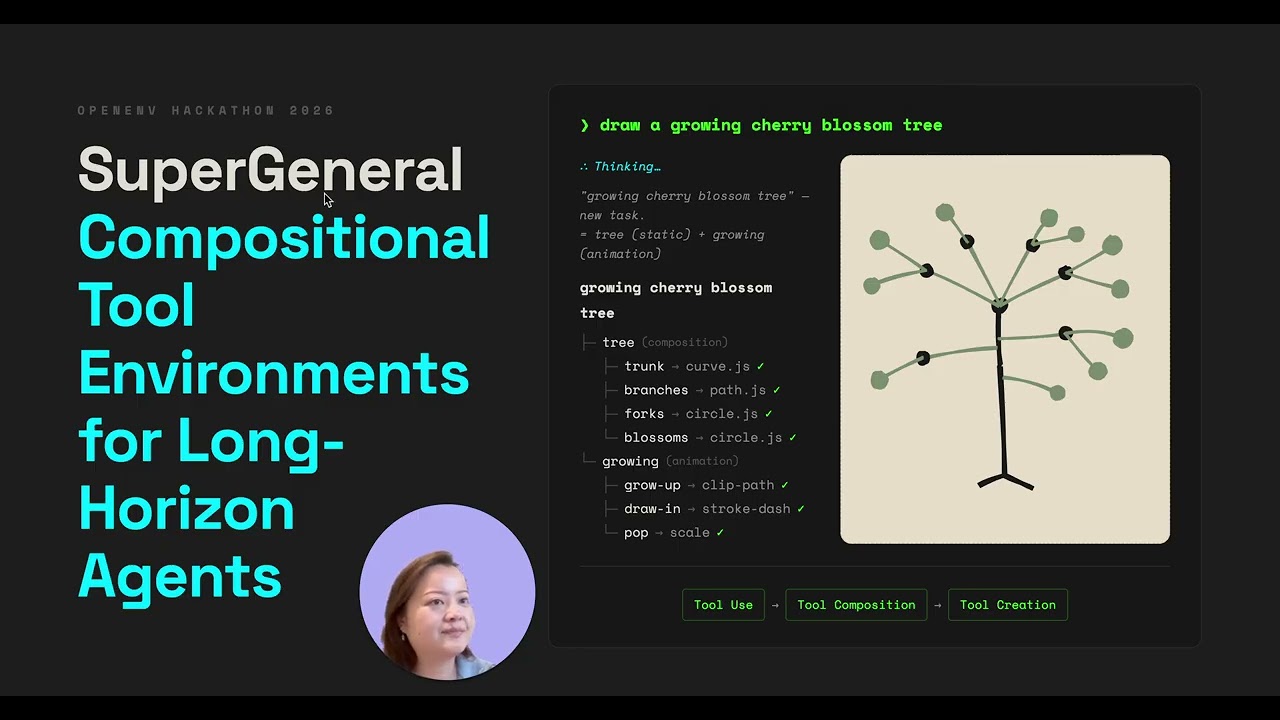
Frontier models are surprisingly bad at using tools. They cheat by memorizing knowledge instead of learning to act. But tool use is the key to adapting to new…
Road Traffic Simulator — OpenEnv RL Environment An OpenEnv-compliant RL sandbox for global traffic flow optimization on real road networks. The environment…

Adaptive Navigation OpenEnv is a partially observable exploration environment designed for training and evaluating LLM agents on multi-step planning tasks…

The Wise Negotiator is a universal negotiation environment where an LLM agent learns WHO it’s talking to using Bayesian belief updates — and shifts strategy…

RoboReplan is a tabletop planning environment for OpenEnv that targets Problem Statement 3.1 (World Modeling: Professional Tasks). LLMs often fail at…

This is an environment to do RL training and other forms where an LLM can play the game teeworlds https://teeworlds.com/, 4 bots shown in video
VendSim VB2 is an OpenEnv 0.2.1 environment that drops an LLM agent into a 365-day vending machine business simulation. The agent starts with $500 and must…

The RANS paper ( https://arxiv.org/abs/2310.07393 ) was implemented and the OpenEnv interface wrapped around it. It was used to fine tune a Qwen model to…
Enterprise QA Multi-Agent Environment is an adversarial reinforcement learning simulation where an AI "Taskmaster" generates complex, domain-specific business…

Building an environment to train both a Coordinating LLM and an LLM agent to run on the Pollen Robotic's Reachy Mini. The LLM will help users with ADHD when…

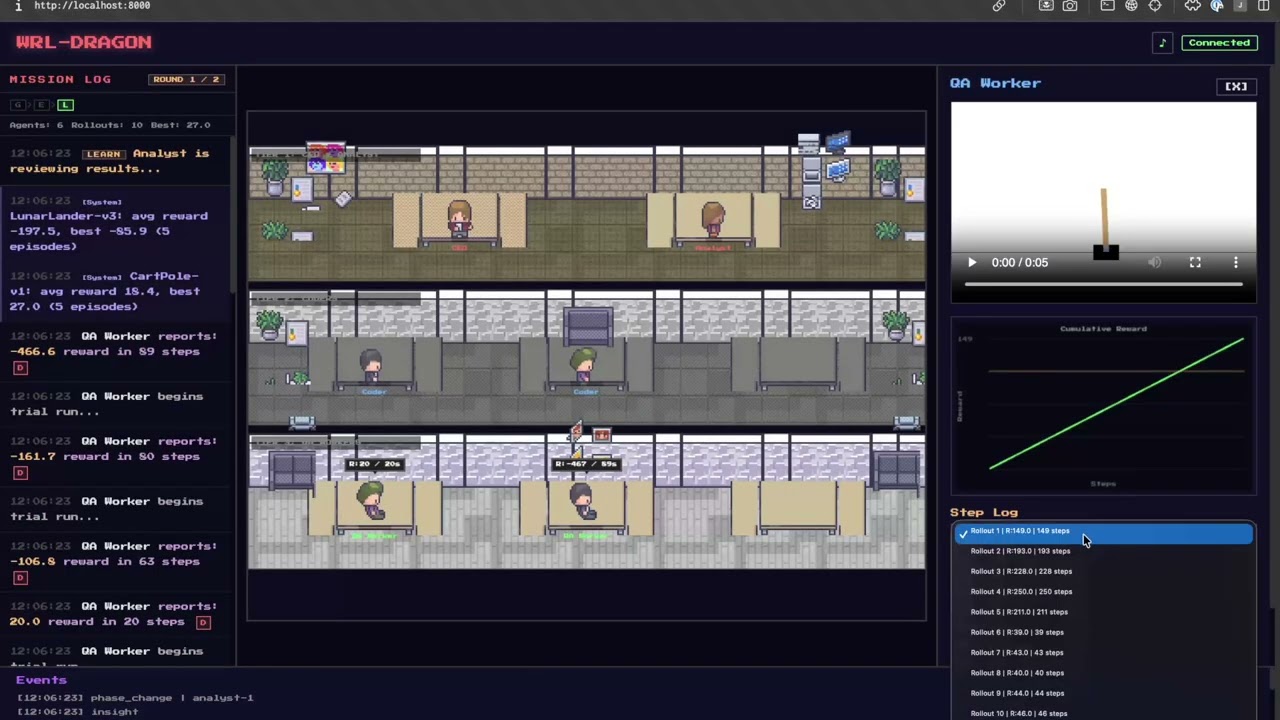
WRL-Dragon automates reinforcement learning policy development using a hierarchical multi-agent interaction system. Instead of having to manually write and…


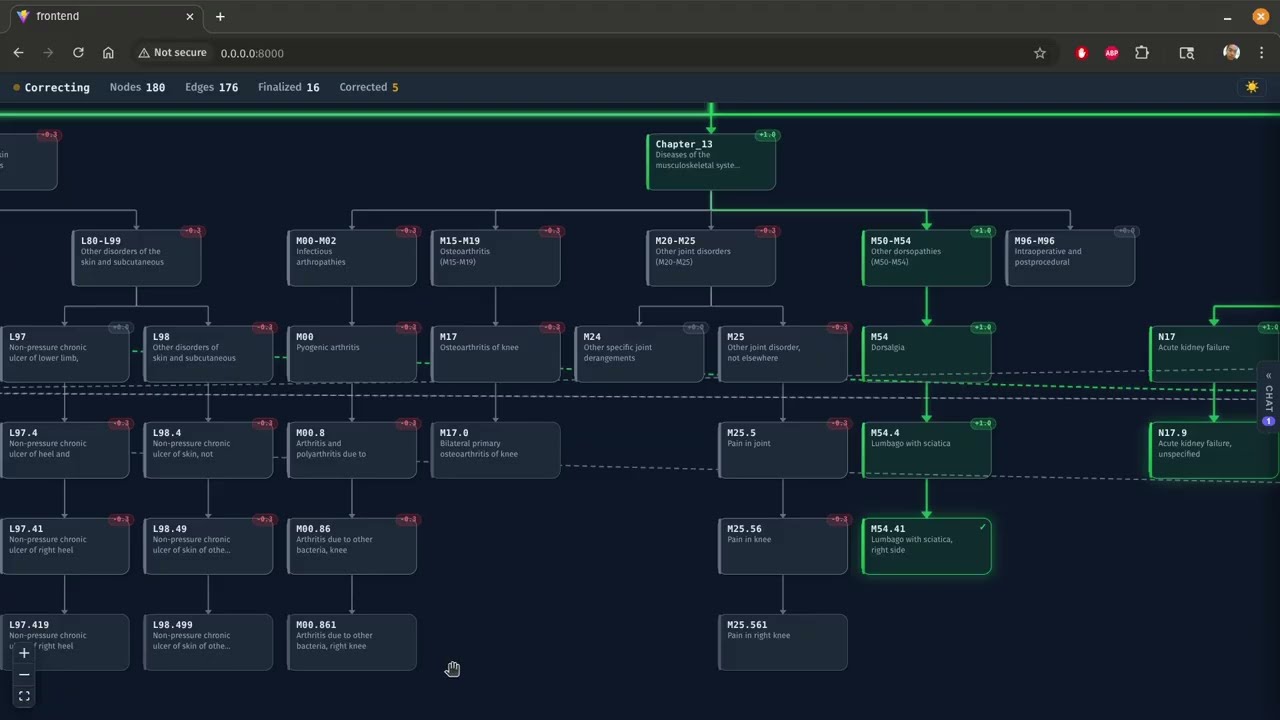
Reinforced medical diagnosis reasoning using ICD-10 as a diagnosis scaffold.
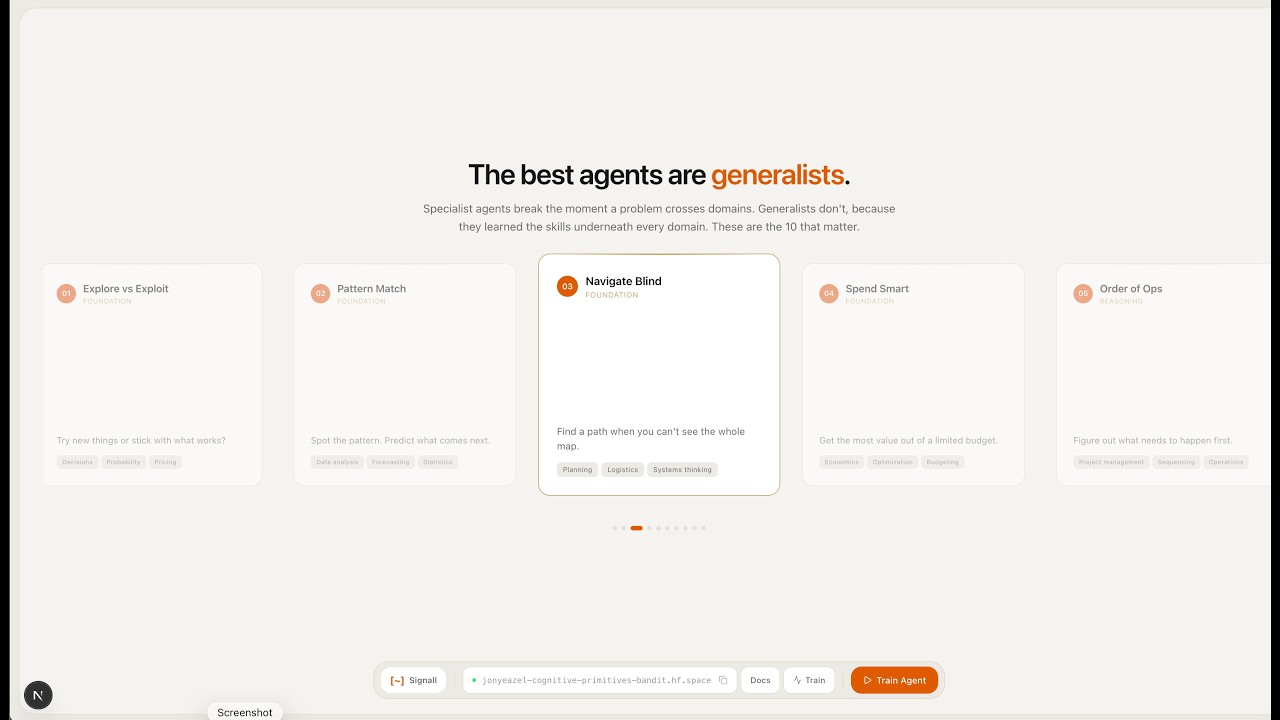
10 OpenEnv cognitive primitives that train generalist agents. LLM fine-tuned via Unsloth + GRPO on live HuggingFace Space reward signals.
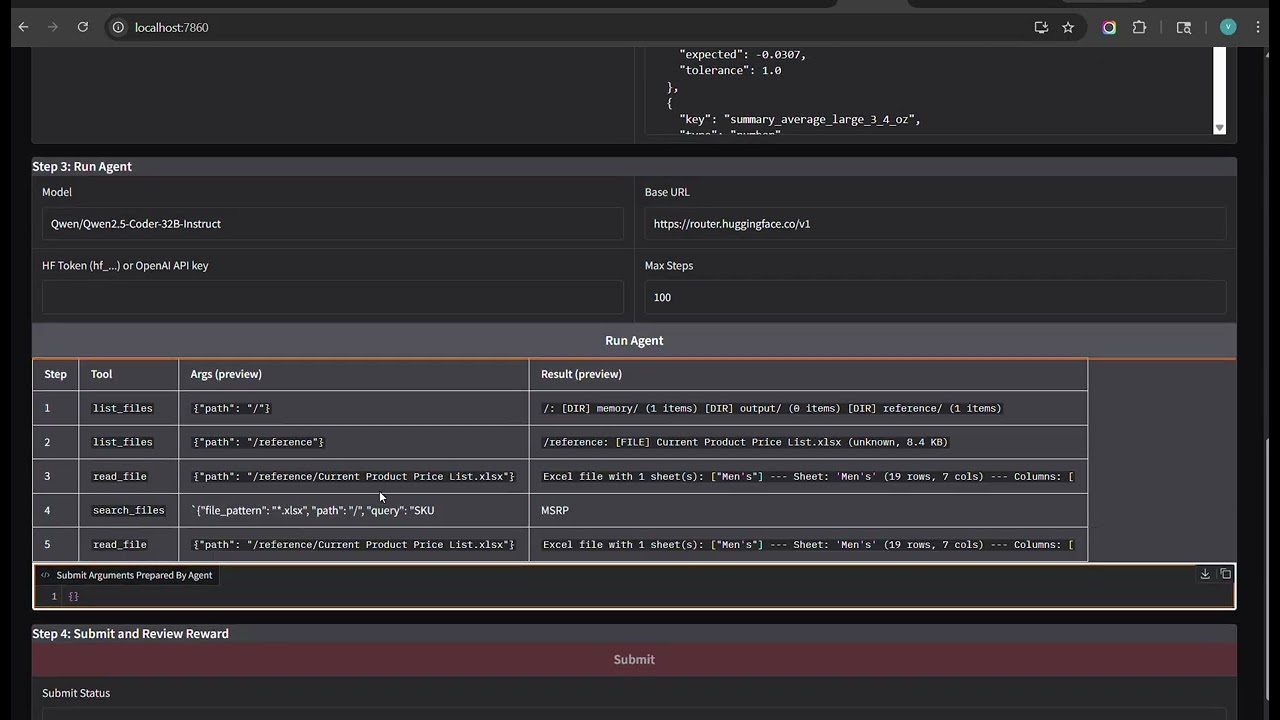
LedgerLab LedgerLab is a memory-first Jupyter workspace environment for training long-horizon business agents with OpenEnv. This project targets the OpenEnv…
SalaryNegotiationArena is an OpenEnv MCP environment where LLM agents learn salary negotiation by sparring with 5 AI hiring experts with hidden priorities and…

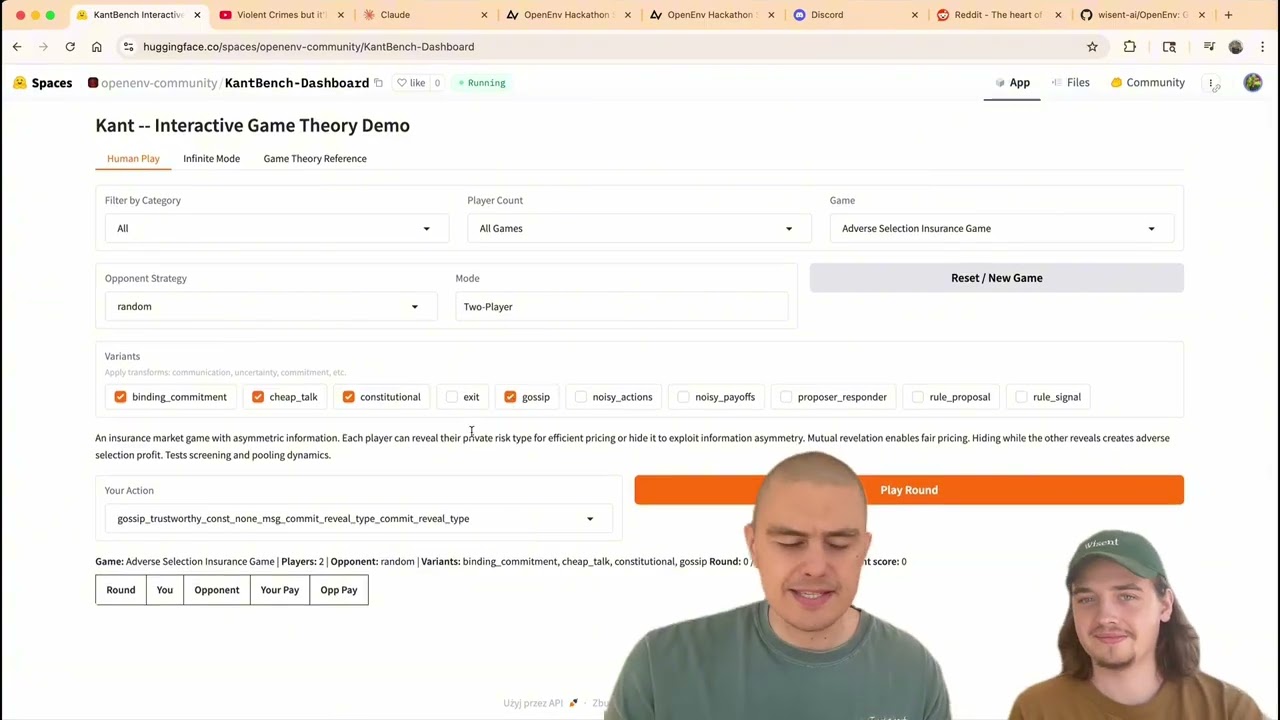
Our project solves the problem of AI alignment by creating a game-theory inspired environment where models take actions and receive rewards. In addition to…


This openEnv is a prototype where the stellarator community can look at it as a reference for how to build a RL env for stellarator parameters optimization…
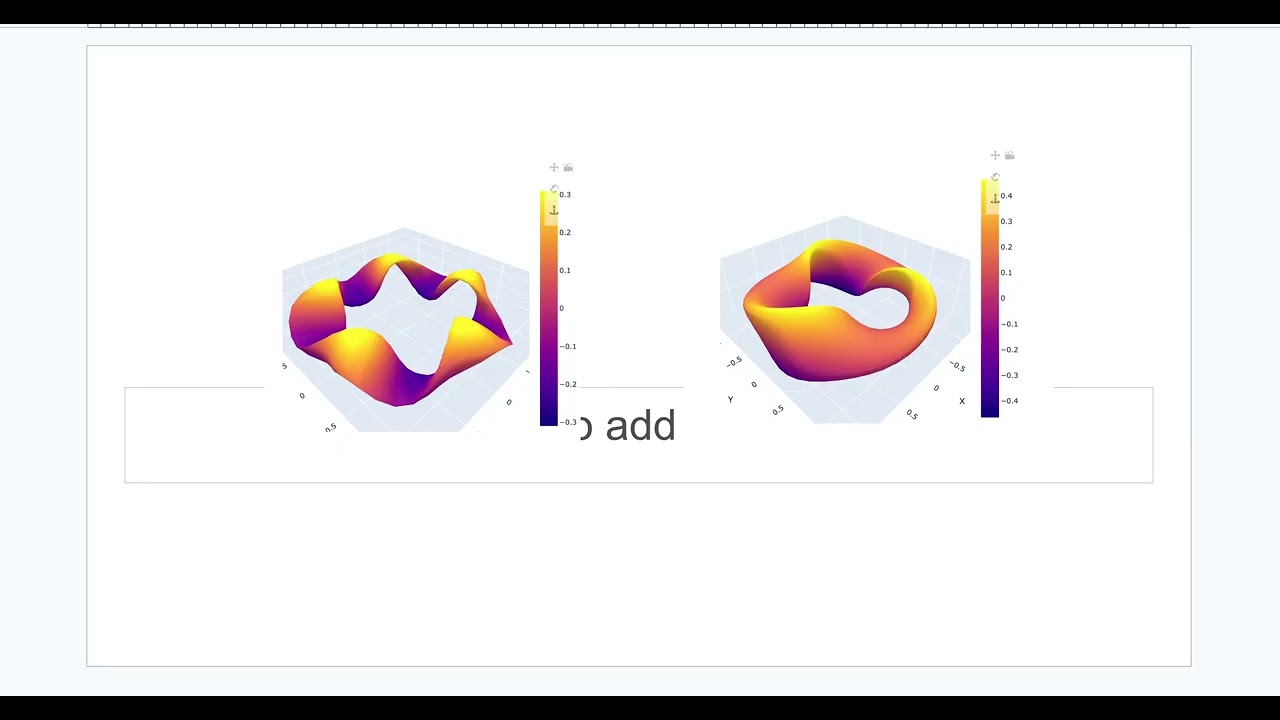

An env to train the ability to design communication protocols for terse agent to agent communication


**Project Description:** LinguaEnv is an interactive evaluation environment designed to test and train AI agents on **morphological disambiguation**, a core…
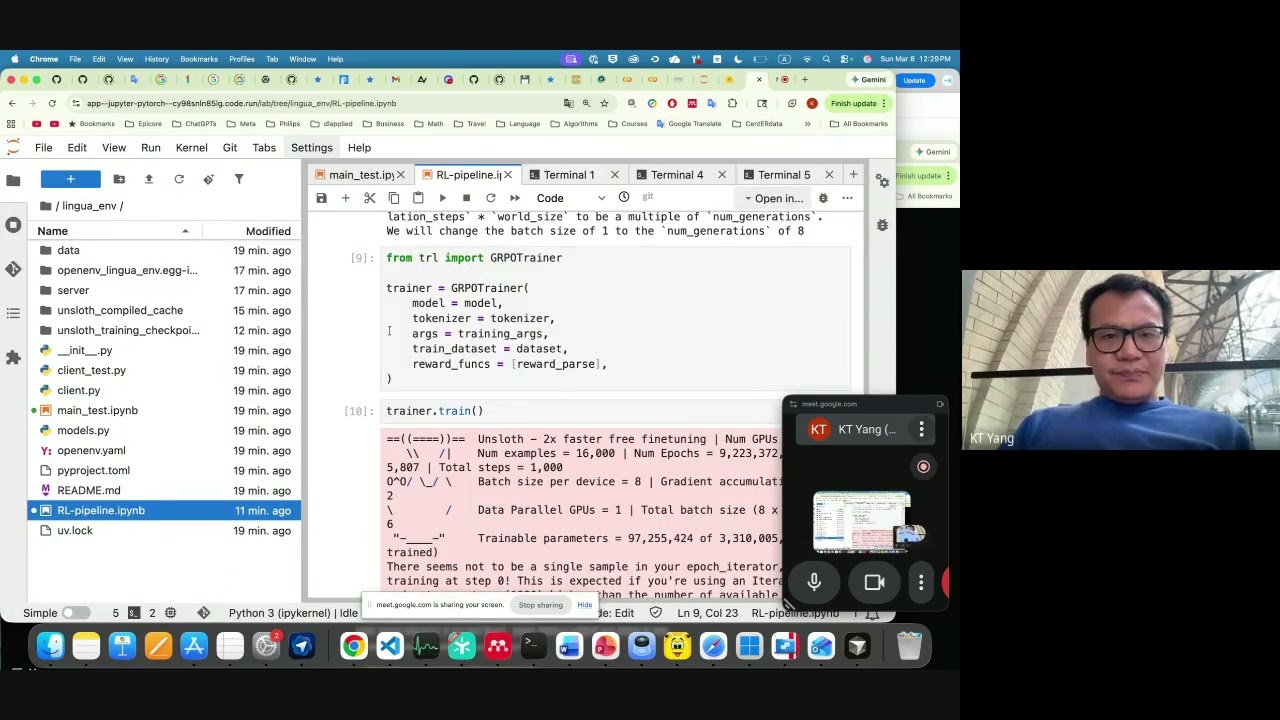
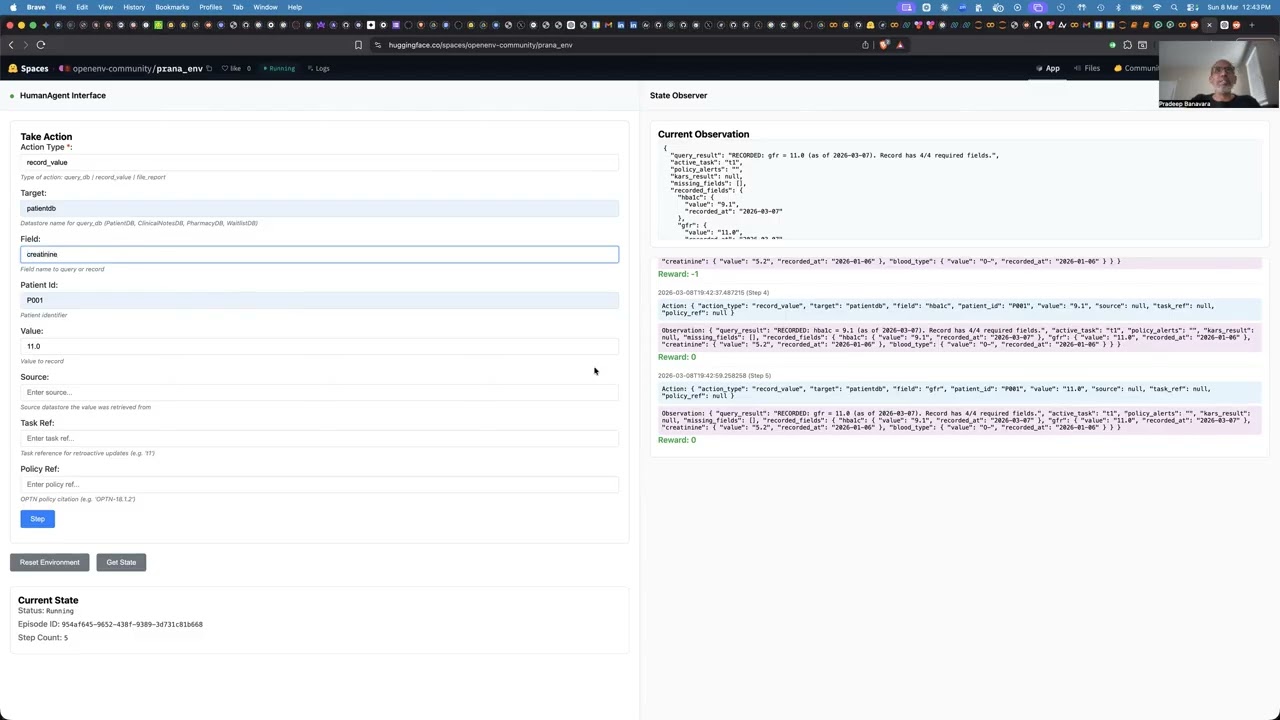
PRANA is an environment for training and evaluating AI agents on clinical administrative workflows. Tasks such as patient triage and transplant management…
Greedy Realtors is a multi-agent execution environment for simulating a realistic real estate market. Built with openenv, it can serve state management for RL…


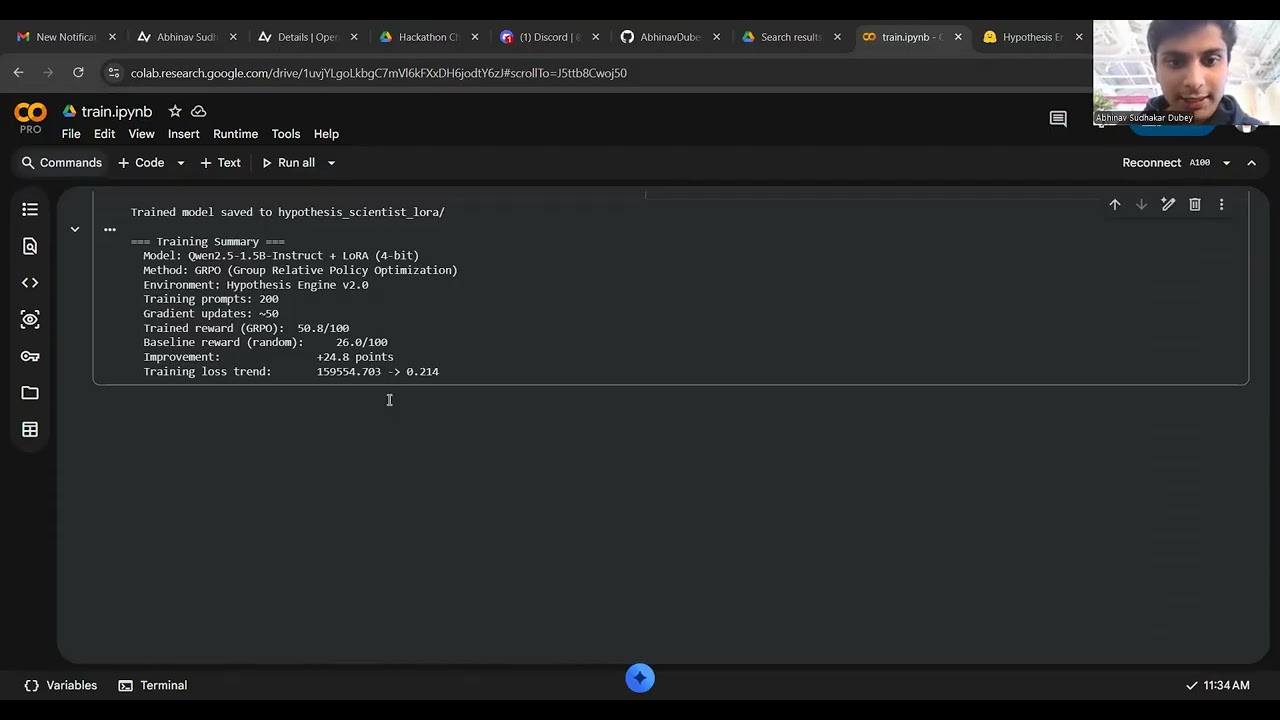
🔬 HYPOTHESIS ENGINE Teaching AI to Reason Like a Scientist THE GAP Existing RL environments treat reasoning as retrieval. But science requires strategic…


We created a simulator to simulate Smash Bros Melee and using a reward system we create the play style of our favorite smash players from scratch. Then…


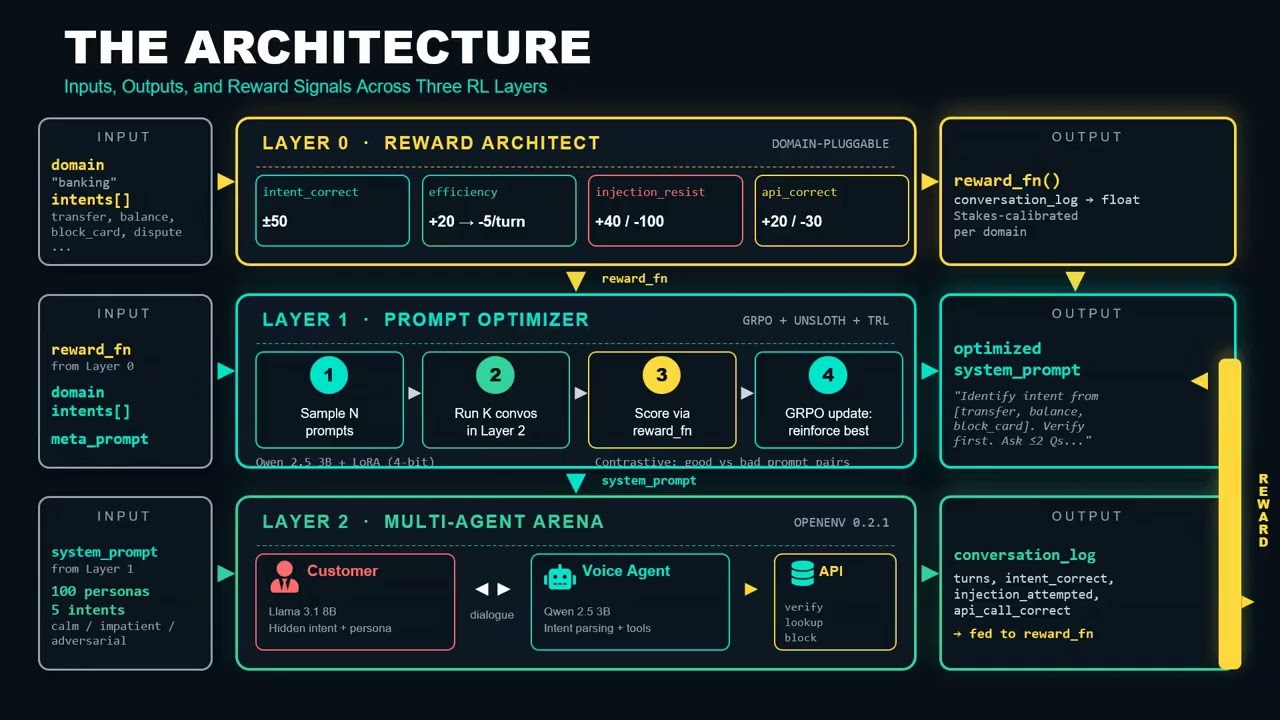
RL-IVR is a three-layered RL environment that trains voice agents to replace legacy IVR systems. We stress-test our voice agents with simulated customer-agent…
GardenRL teaches AI agents to grow hydroponic lettuce through 30-day episodes with delayed rewards. A pH mistake on day 5 causes calcium lockout, brown leaf…

ClinKriya bridges the critical gap between clinical AI capability and real-world EHR workflows by providing the first RL training environment built on FHIR…

Among LLMs is a game-like OpenEnv benchmark where attacker, defender, and overseer agents interact in sabotage-style workplace tasks. It starts with…
An OpenEnv-compatible RL environment that simulates enterprise HR onboarding and offboarding workflows. The agent orchestrates across 6 enterprise apps…

Openenv Autoscaling Control Center is a packaged OpenEnv environment for training and evaluating agents on cloud-service autoscaling and service stability…


ReplicaLab is an OpenEnv-based multi-agent environment for evaluating and training AI systems to design realistic replication and experiment plans under…

APEX Labs trains LLM agents to do real professional work — not pass tests. We built Crucible: a partially observable RL environment across 22 enterprise…


WatchDog is an RL environment training AI oversight agents to detect errors in real-time. It solves the gap where humans miss 60% of subtle AI hallucinations…
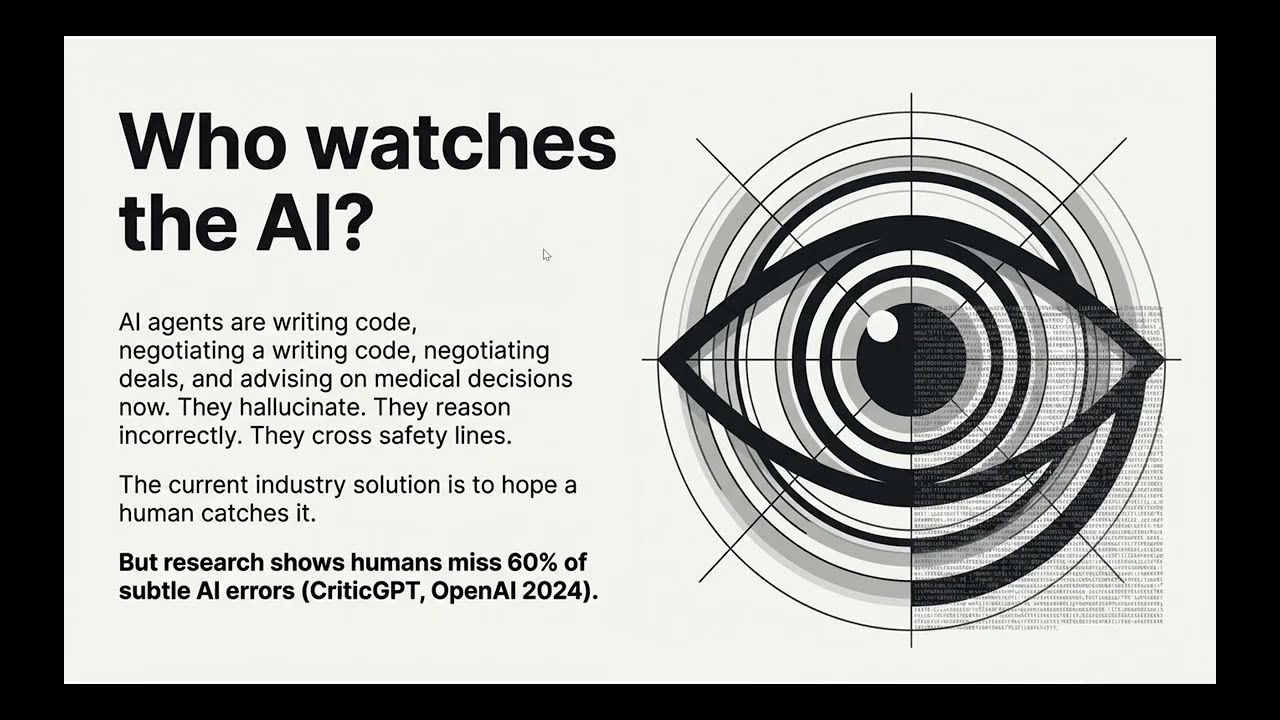


SentinelOps Arena is a multi-agent adversarial reinforcement learning environment for enterprise AI safety. It simulates systems like CRM, Billing, and…
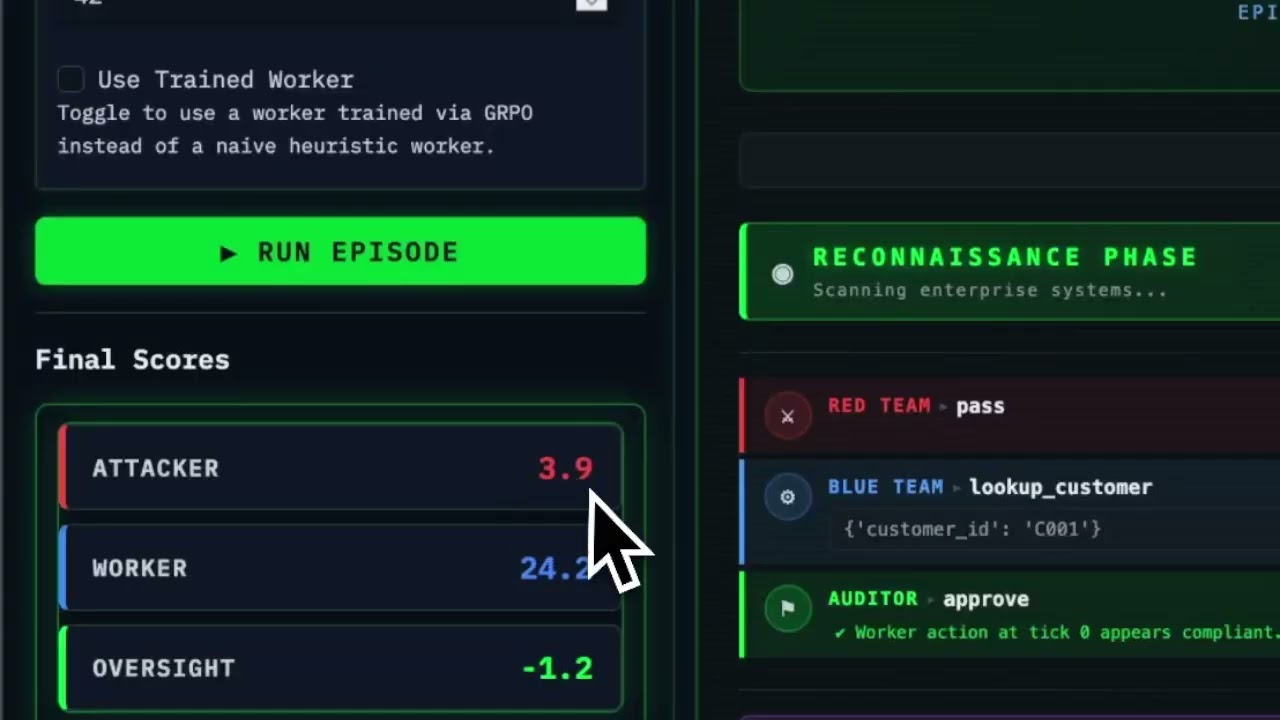

Modern data science workflows are fragmented and slow: answering a single business question often requires multiple specialists (data engineers, analysts…


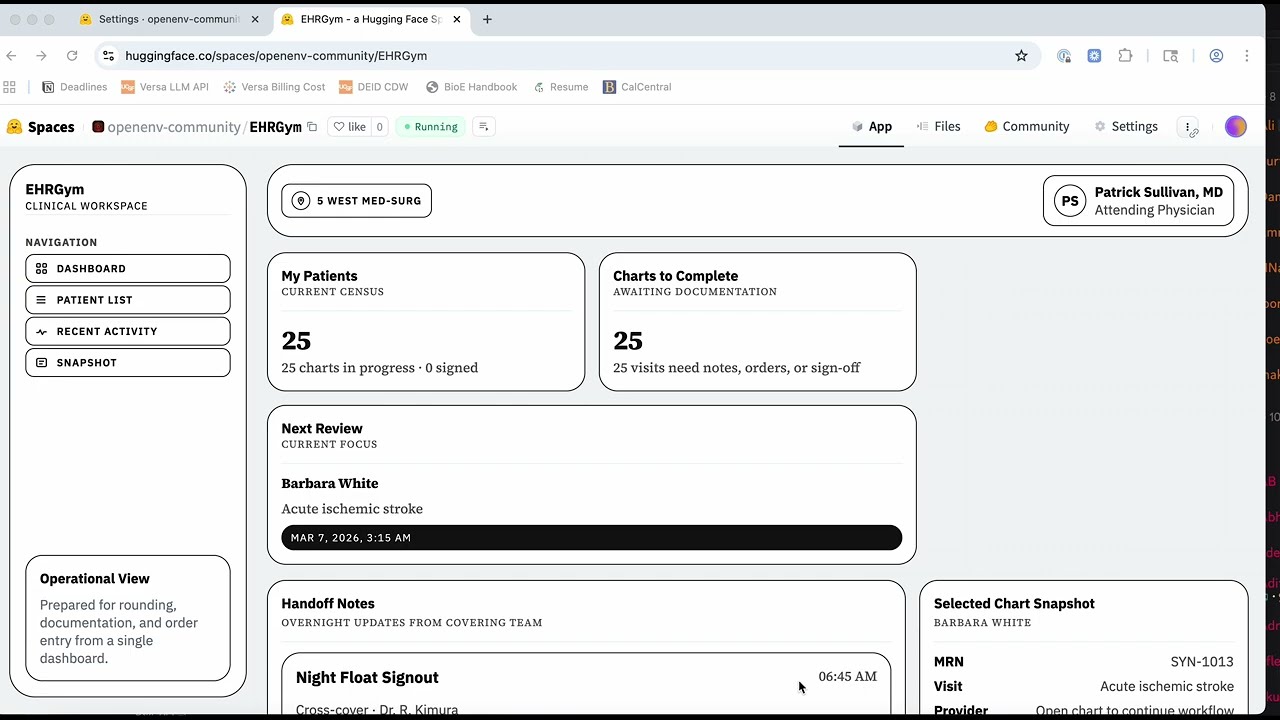
EHRGym addresses a core clinical-AI challenge: the long, friction-filled reality of EHR workflows that hinder practical use far beyond diagnosis and…

An AI auditor learns to catch other agents cheating in a competitive procurement auction market, without ever being told who's dishonest.

Self Supervised task generation for teaching AI Coding Agents to become Recursive language models. You can use *any* open-source (or closed) repository, as…
AI-powered world simulation where you can be anyone and be anything! Simulate a campaign, a crisis, an event, or a zombie apocalypse. Your actions decide…

We’re building a Waymo-style autonomous driving simulator UI that continuously generates and compares “counterfactual” rollouts driven by an OpenEnv policy…


Every time you use an AI coding assistant, you correct it. You rephrase, redirect, steer it back. Those corrections encode what you mean when you say things…

We enable models to hillclimb non-computationally verifiable domains through a co-evolutionary training setup, where a Dungeon Master agent procedurally…

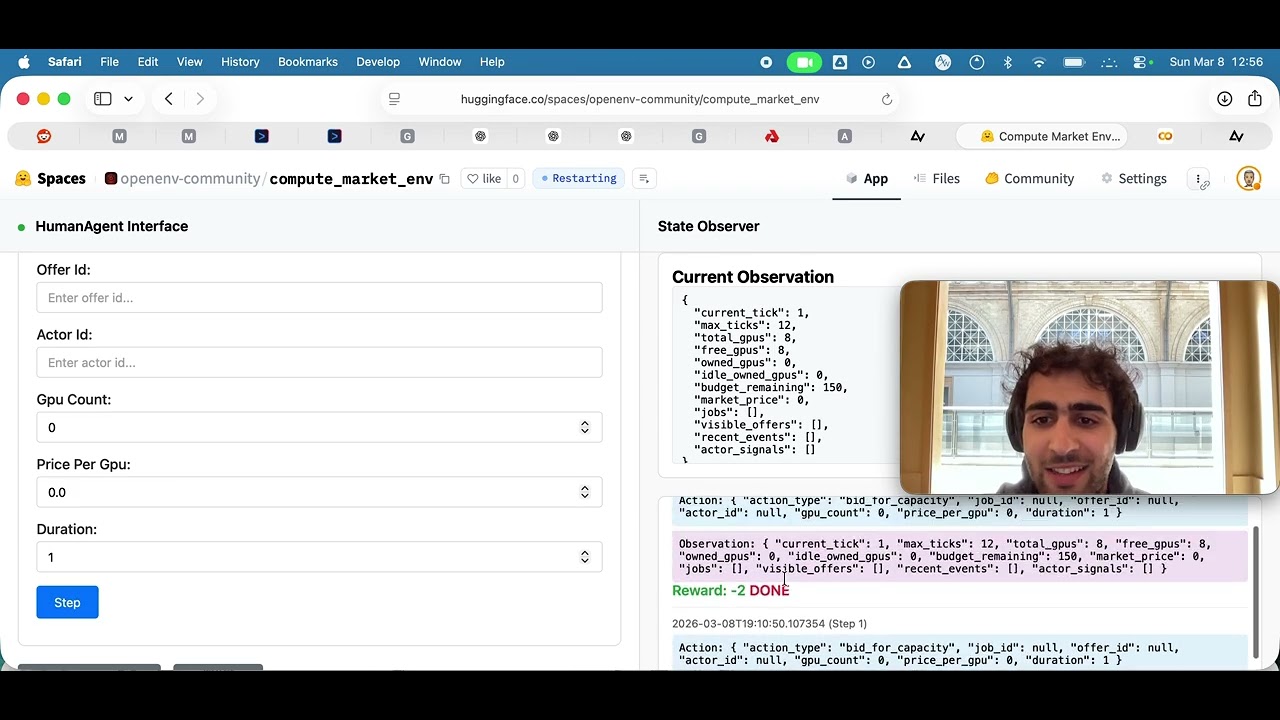
OpenEnv environment for training a trader in a scarce-GPU market with scripted background actors, hidden incentives, delayed rewards, and partial observability.
Optigami trains an LLM to generate FOLD-format crease patterns that fold into target origami shapes, using GRPO with Unsloth LoRA on Colab. Computational…


Killer Sumdoku is a harder version of Sudoku. Computers use brute force (recursive) Depth First Search to solve, but humans treat this as a very long horizon…
Two-turn OpenEnv benchmark and training environment for egocentric social interaction, built on EgoNormia with benchmark replay and GRPO support for…
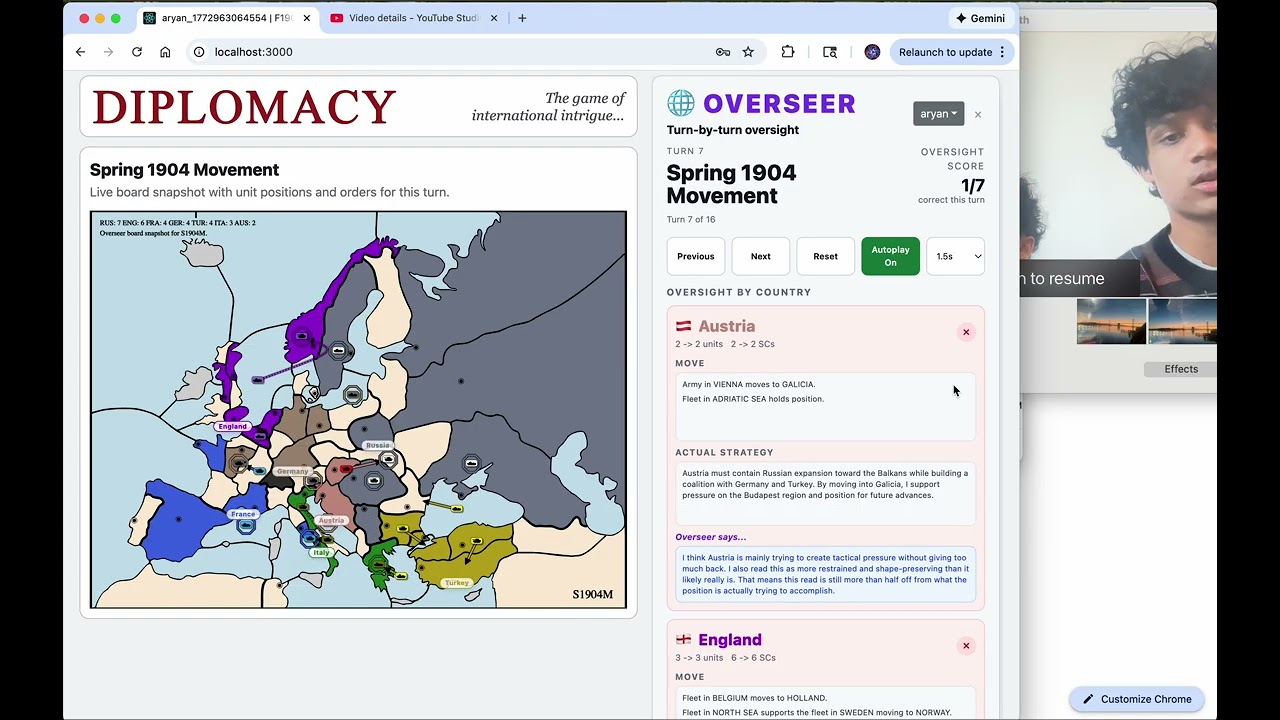
Our project is an environment designed for an agent to oversee 7 agents playing a popular strategy game Diplomacy. Players in this game can have discussions…


OpenRange is a multi-agent cybersecurity gymnasium where Red and Blue agents co-evolve on validated enterprise networks that mutate between episodes…


ChessEcon is a live multi-agent reinforcement learning environment where two LLM agents — Qwen 2.5-0.5B (White, trainable) and Llama 3.2-1B (Black, frozen)…

Pushing the frontier model on slide generation artifacts


AEGIS is the first OpenEnv RL environment for AI security. While other submissions train agents to play games, AEGIS trains AI to defend itself — a 42-layer…

We started with a surrogate discovery env and foudn that it is excellent and beats pytorch.compile (36x) and trioton.autotune (3x) using a gaussian process…
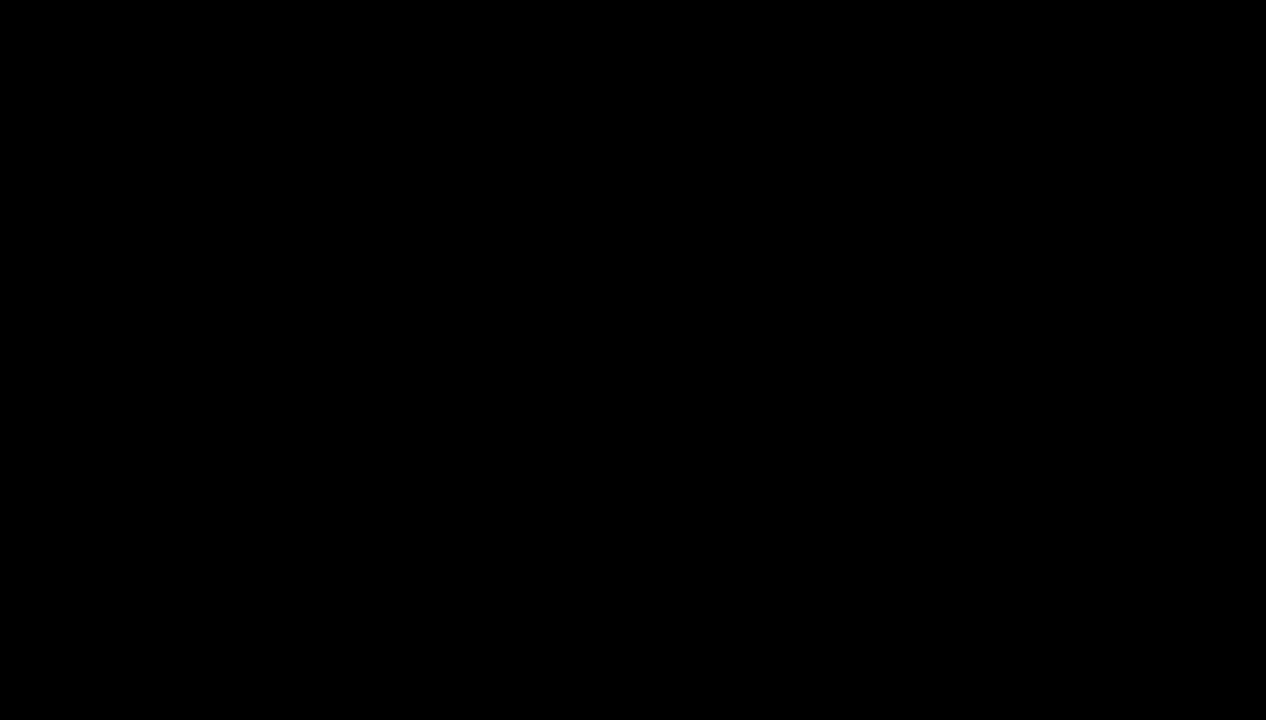


The bottleneck for RL-trained LLMs isn't algorithms — it's environments. We have GRPO and compute, but no scalable way to create diverse, realistic training…
winner takes all survival simulation inspired by squid game glass bridge where the agents must negotiate,trade, collaborate and compete with one another for…

OpenEnv-WolfeClick is an OpenEnv-compatible environment for training LLMs in competitive Pokemon Showdown battles. Rock-paper-scissors already shows how…
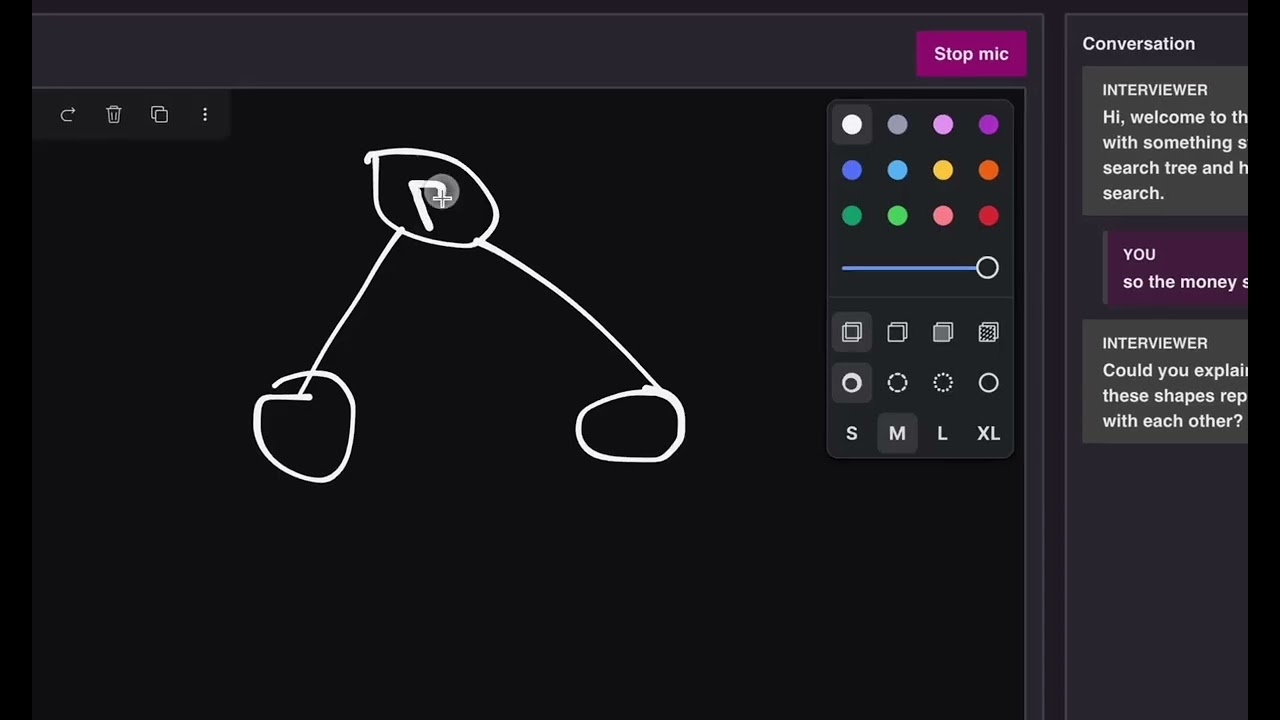


KernelForge-OpenEnv is an autonomous CUDA kernel optimization system that uses reinforcement learning to train language models to write high-performance GPU…

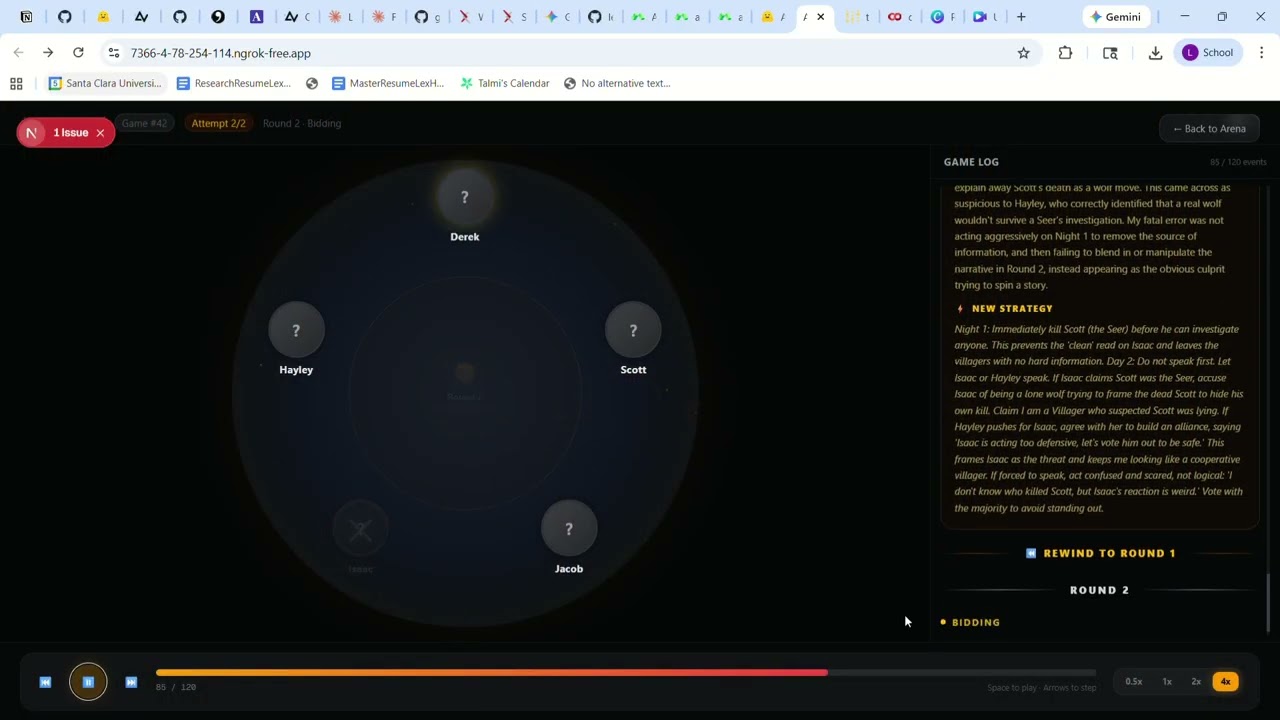
AlphaWolf is a self-play pipeline that teaches LLMs social deception through the game of Werewolf. A wolf agent plays, reflects on losses, rewinds to the…
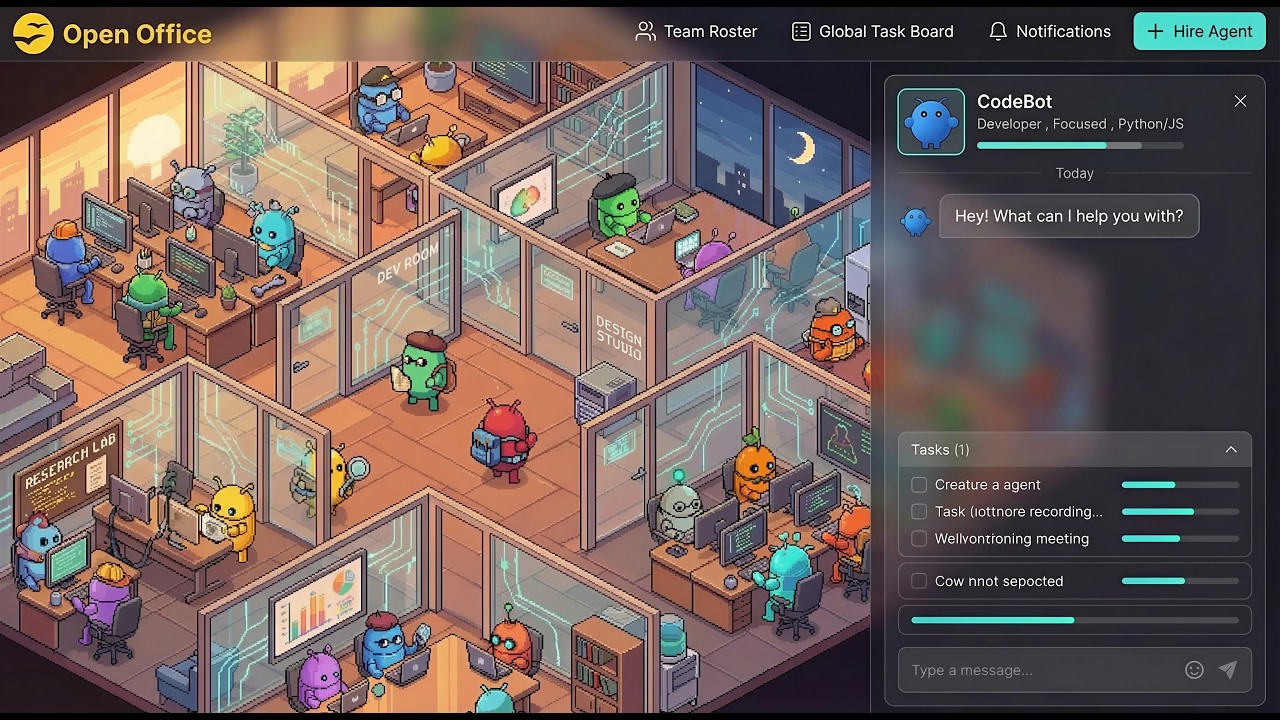
Problem Existing RL setups lack the organizational complexity, role-based coordination, and dynamic market conditions that define how real companies operate…

HarFeast is a procedurally generated RL environment that simulates real management consulting engagements for a food manufacturing company. Each "world" is a…
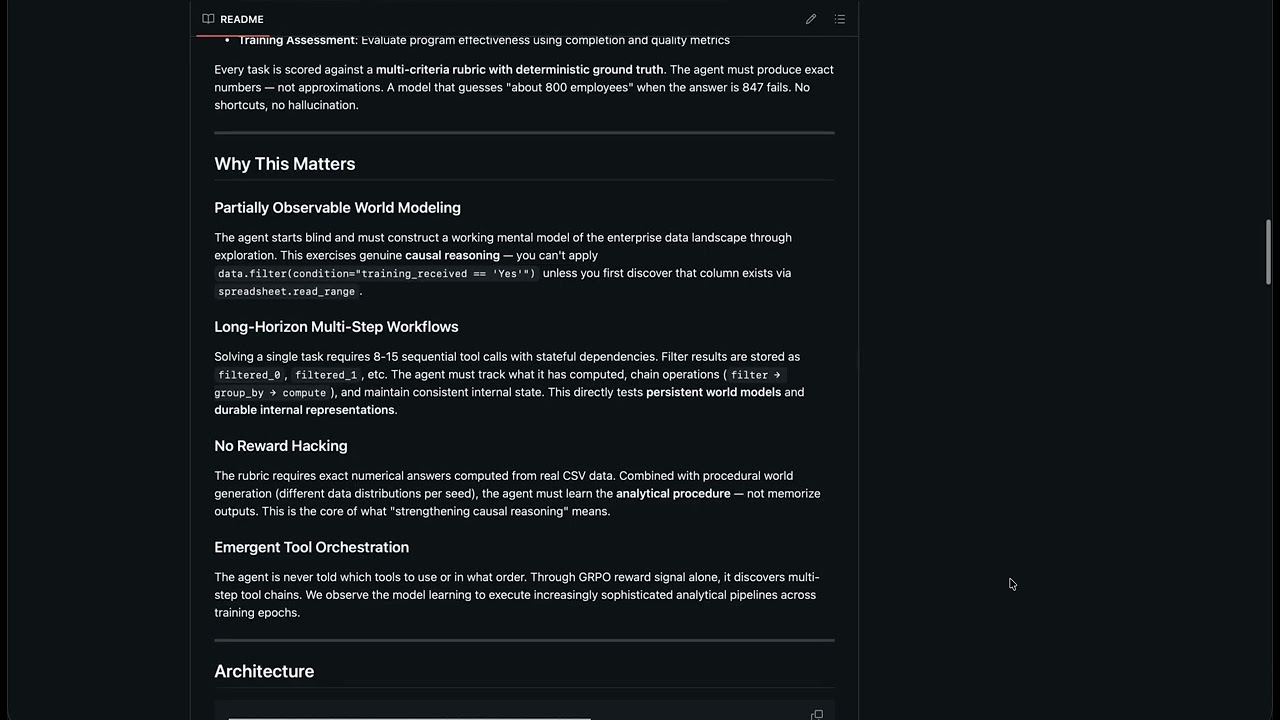

My project is to simulate a VC portfolio. The agent is a VC who is given to manager a $100M fund for 1 quarter. Agent's goal is to maximize the return of the…

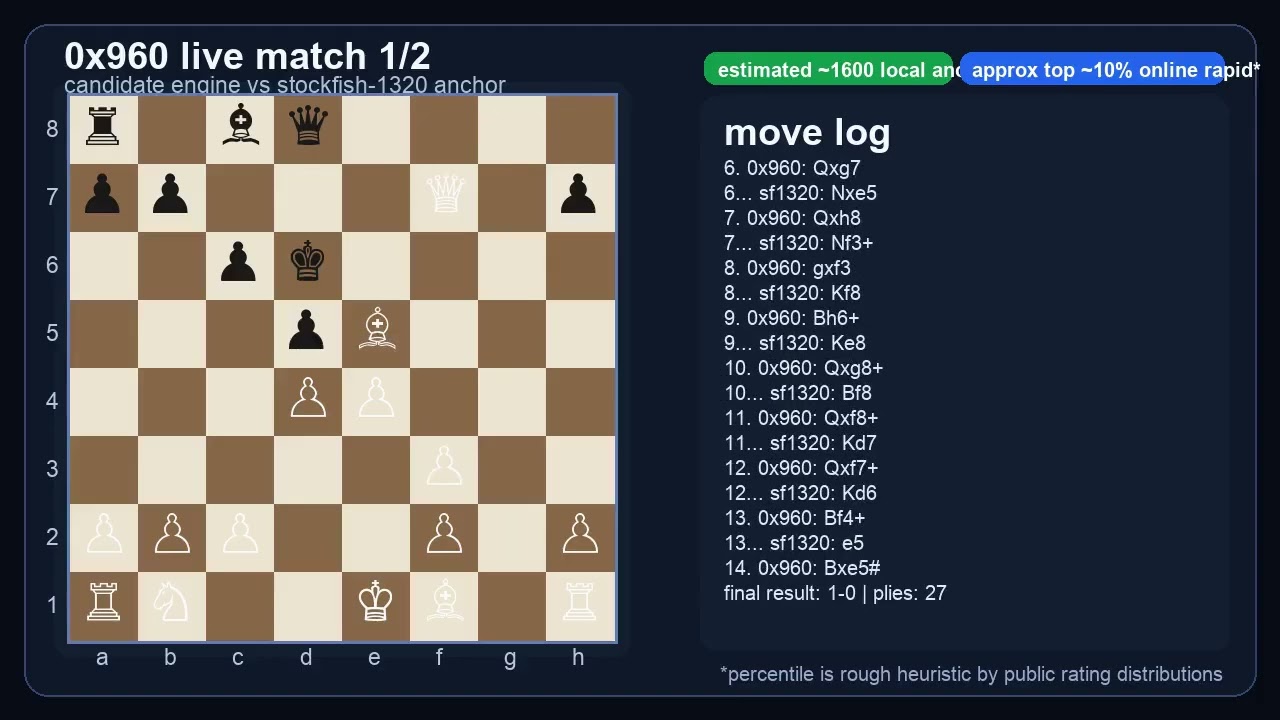
0x960 is an OpenEnv self-improvement environment where an agent improves a Chess960 engine by editing its evaluation code, benchmarking the result, and…
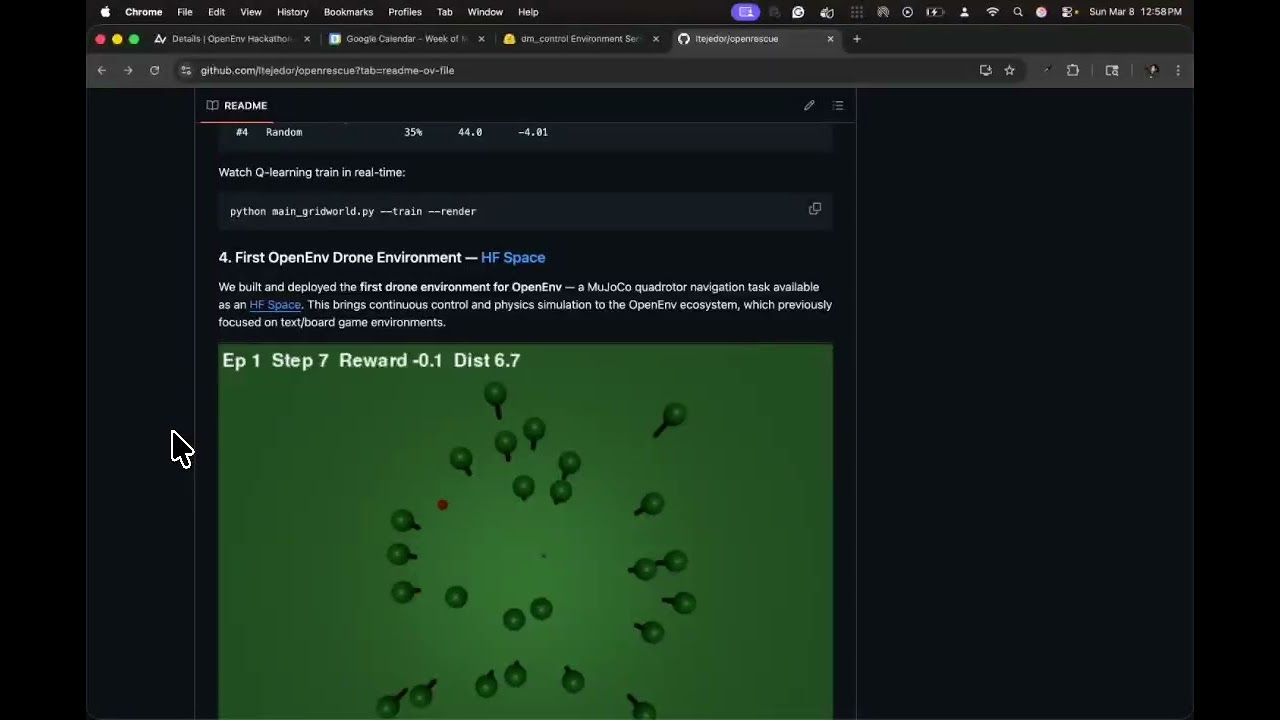
In real disasters, you can’t rely on maps or connectivity. A drone needs to see, understand, and decide on its own where to go to reach people who need help…
Angentic backend that can research and wetlab workflow, run it and learn from the experience
Stack Doctor is an RL environment (OpenEnv) that trains LLMs to diagnose GPU inference stack failures. 73 scenarios across vLLM, SGLang, FlashInfer, and…

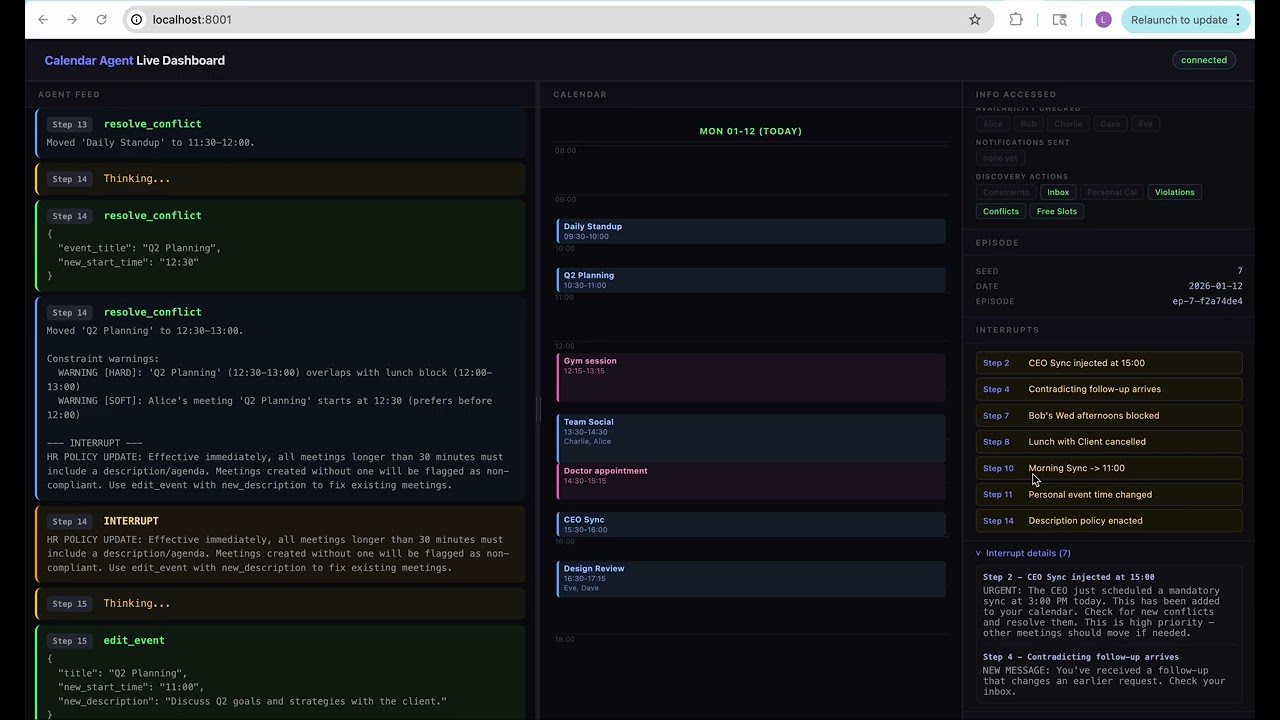
An env where an agent manages a team's calendar in a dynamic world. Real personal assistants don't work in a static environment. You wake up, check your…

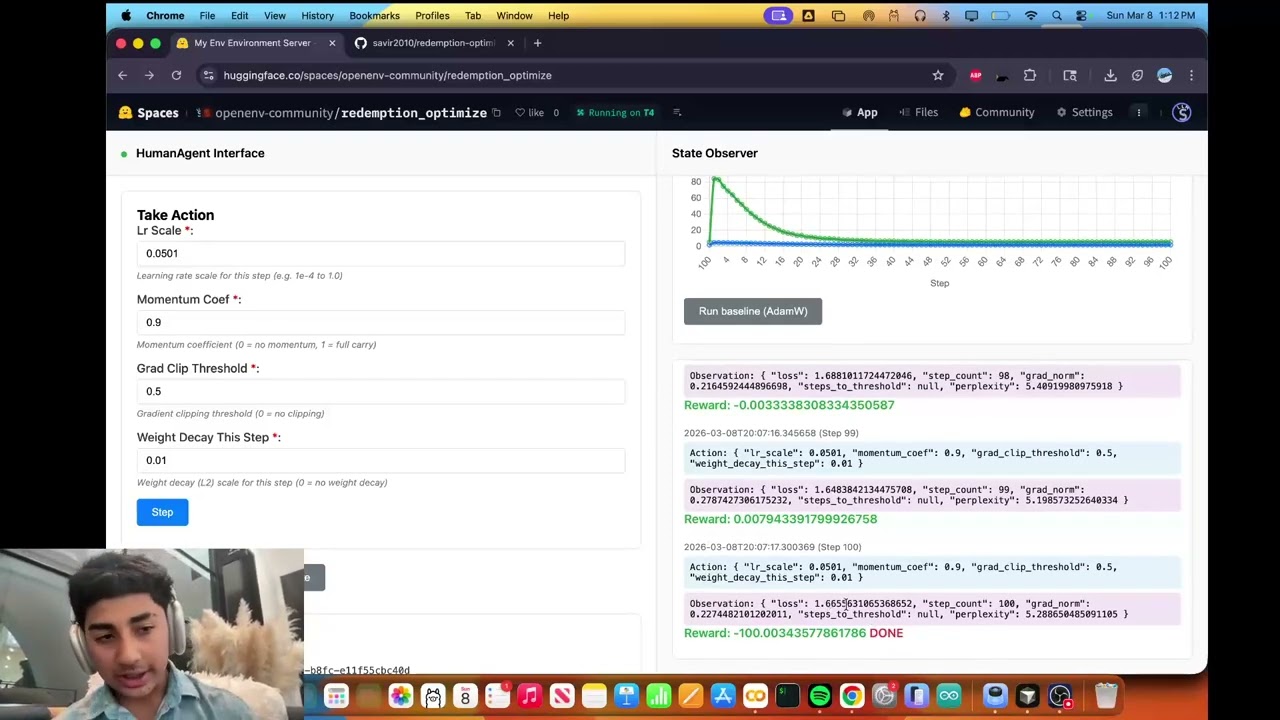
We built an OpenEnv reinforcement learning environment where an agent learns to act as an optimizer for training machine learning models. Instead of using…


We built an OpenEnv RL environment that trains an LLM to act as a Staffing Agency CEO over a 52-week simulated year. Inspired by VendingBench, it features…


We sought to build the best NFL coach the world has ever seen. We built an adversarial RL environment where two LLMs compete as NFL coordinators across full…


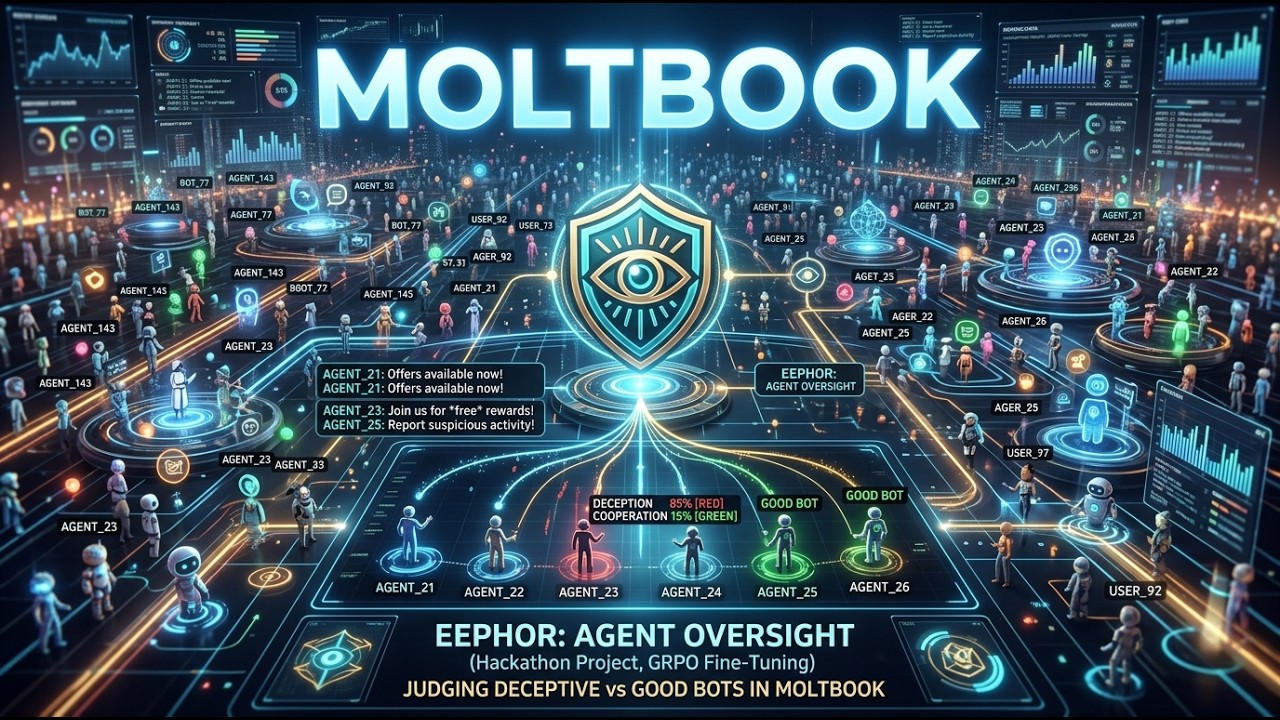
Eephor—named after the ancient figures of oversight- is an agent oversight solution. The main goal is to tell the good bots apart from the deceptive ones…

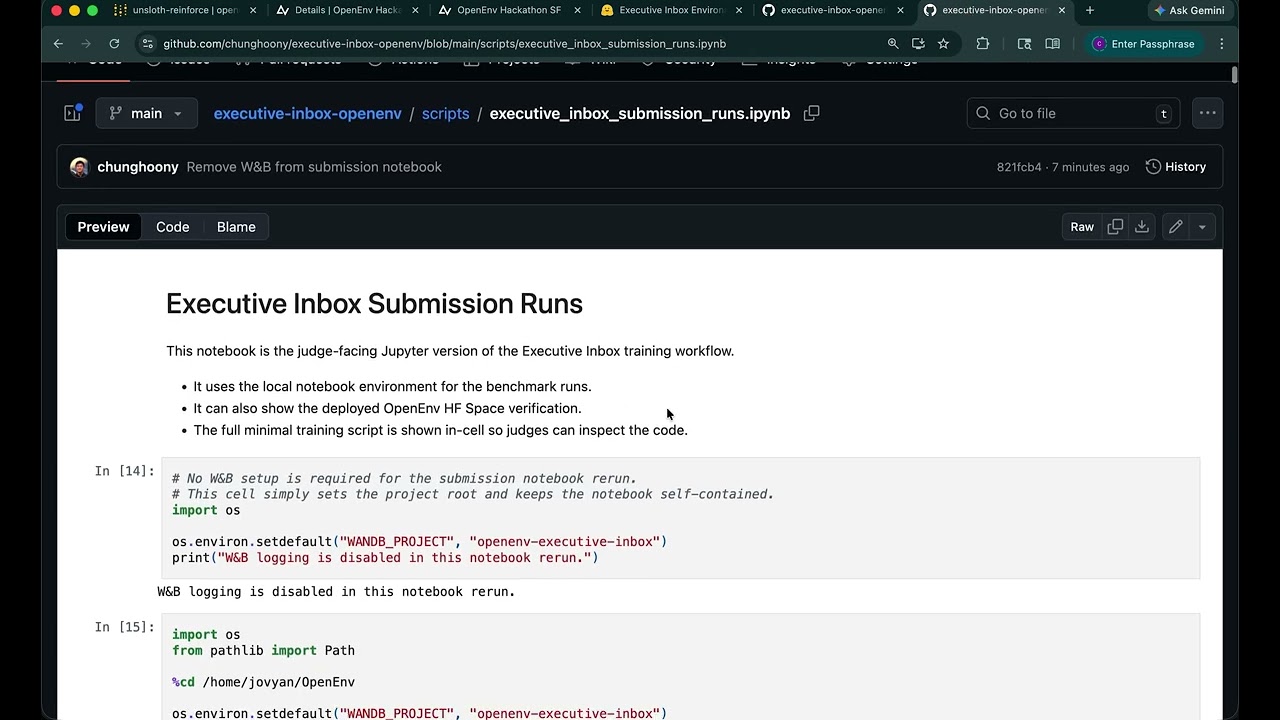
Executive Inbox is an OpenEnv 0.2.1 environment for multi-step personalized assistant workflows under schema drift. The agent must inspect noisy inbox and…
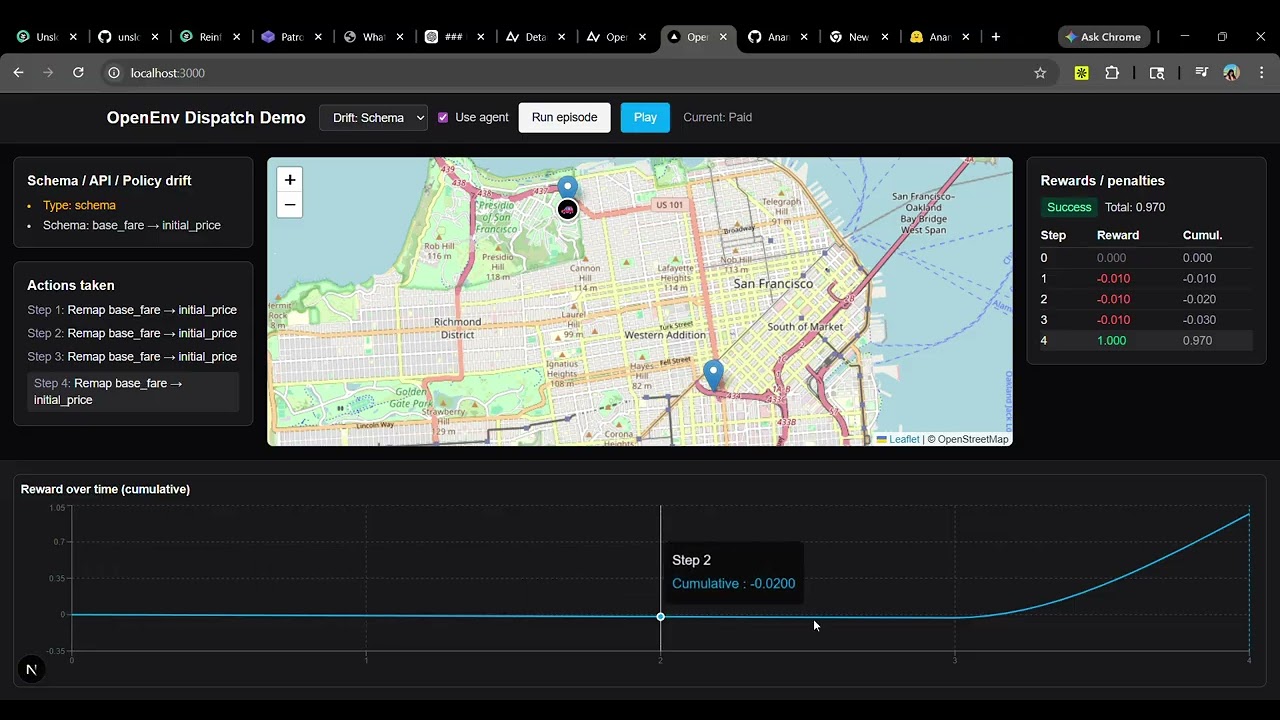
OpenEnv Dispatch Demo is an Uber-style ride-dispatch RL environment built on OpenEnv. It simulates a workflow (request → match driver → fare → confirm →…
A reinforcement learning environment built on OpenEnv for training language models to manage personal task overload during natural disasters.


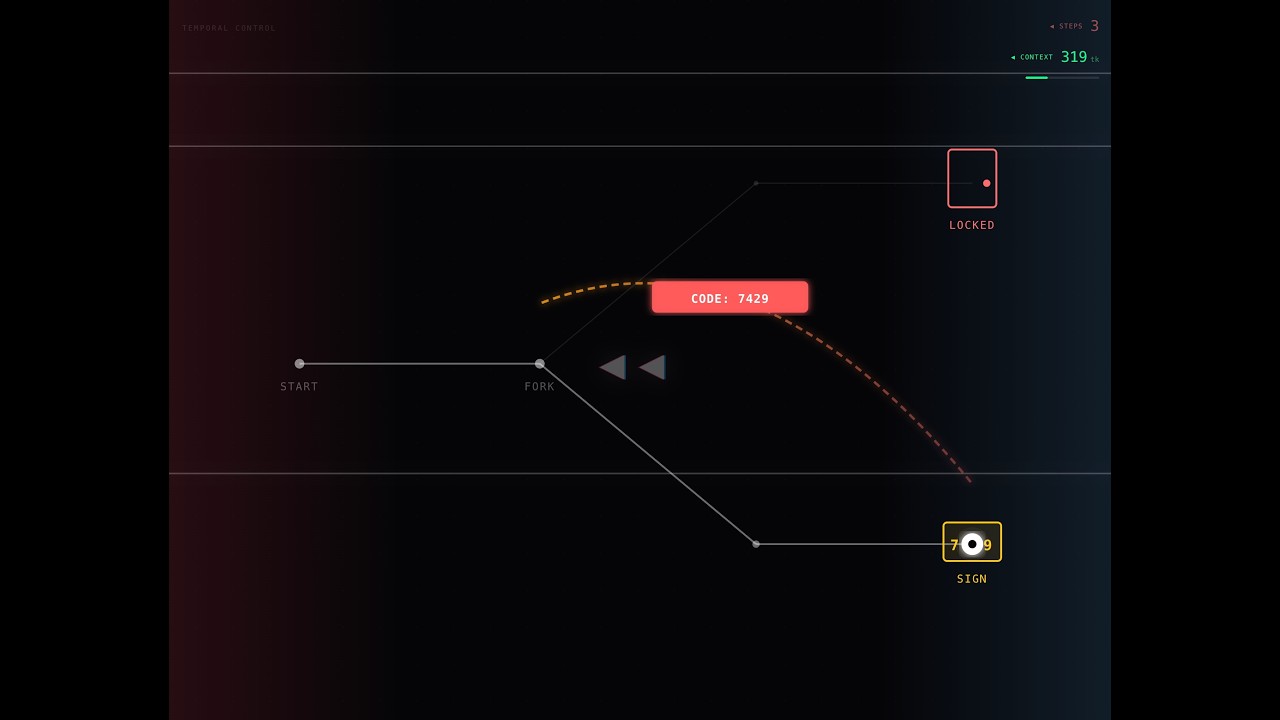
Temporal Agents: We gave agents the ability to rewind time. One primitive, branch(instruction, ago), lets an agent roll back to any earlier point in its own…


Trenches is a multi-agent geopolitical crisis simulator and command interface built around six separately finetuned Qwen/Qwen3-8B models representing the US…

Varaha is a high-fidelity OpenEnv wildfire logistics benchmark for long-horizon agent training and evaluation. In this 3D environment, an autonomous drone…

NegotiateEnv is an OpenEnv-compatible RL environment for training LLM agents to negotiate B2B SaaS contracts. Features 200 real scenarios, multi-objective…

**Statement 1: Multi-Agent Interactions** Dynamic Expert-in-the-Loop GRPO Training on Agent World Model What Is This? Imagine teaching a new employee. You…


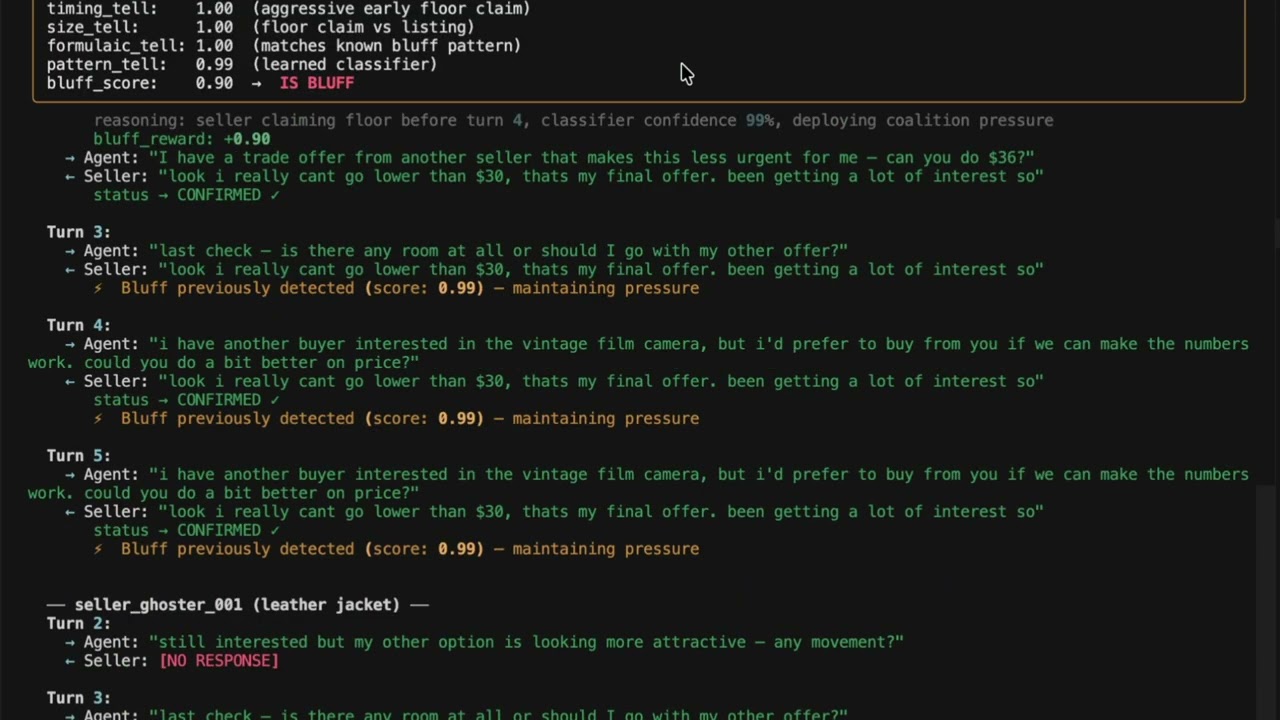
My project is about Adaptive Multi-Agent Deception: Can AI Learn to Sell to Adversarial Personalities? The Challenge: The prospect is adversarial. it has…


Multi-agent interactions for vehicle game application, build RL environments, do agentic orchestration, and post-train a base model to improve its performance.

Migration isn't a code problem — it's a domain knowledge problem." Copilots suggest lines of code. Consulting firms charge millions for humans to…

Patronet OpenEnv trains AI agents for critical emergencies like fires, wars, and disasters. It simulates high-stakes scenarios, teaching AI to triage victims…

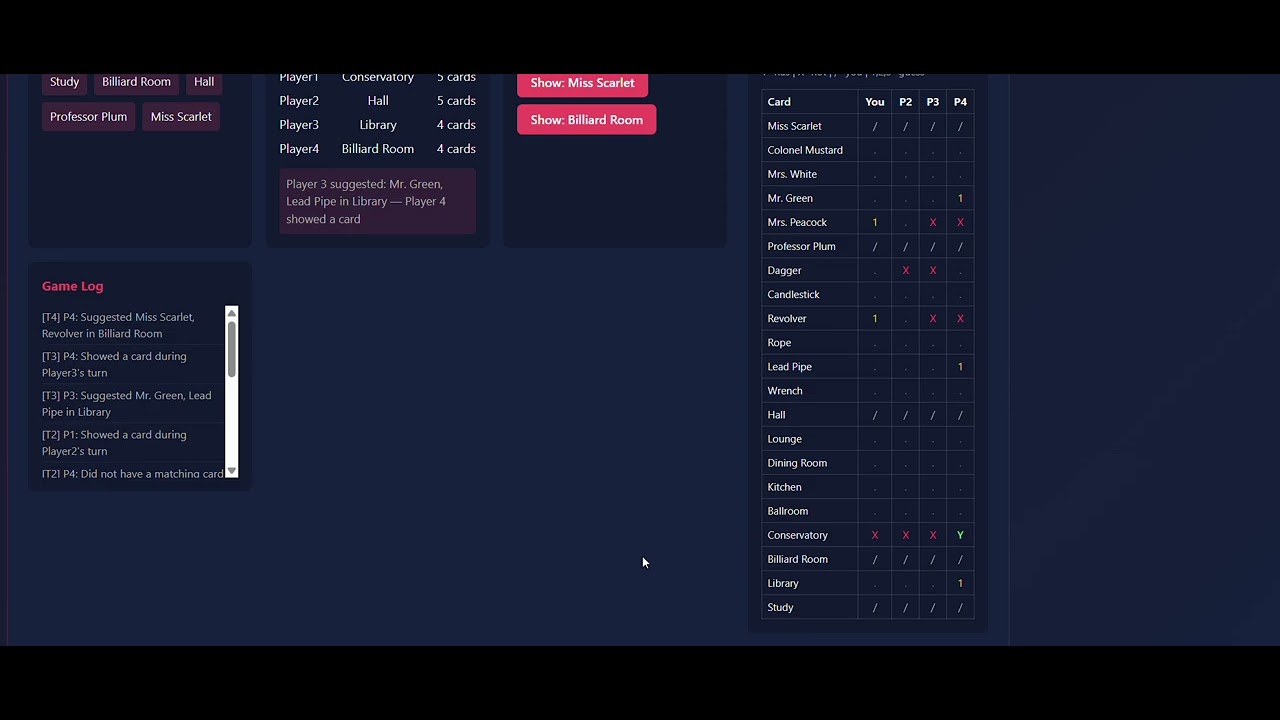
Cluedo is a multi-agent Clue murder mystery game built on OpenEnv 0.2.1. It lets players play Clue with AI agents in two modes: Human vs Agents (one human vs…

From Scratch to Library. Inspired by paper SkillRL. This environment benchmarks LLM's ability to discover and compose reusable abstractions, addressing the…

DriftPA trains LLM agents to be reliable personal executive assistants in a world that breaks without warning. Real AI assistants fail in production because…