Skip to Main Content

WRL-Dragon automates reinforcement learning policy development using a hierarchical multi-agent interaction system. Instead of having to manually write and tune RL policies, a CEO agent analyzes environments, Coder agents generate policy code using LLMs, and QA agents run rollouts to evaluate performance. Results feed back into subsequent round, creating an autonomous improve loop across multiple Gym environments simultaneously. The system solves the tedious cycle of write-test-iterate in RL research by letting AI agents handle the entire pipeline from strategy to code generation to evaluation, all while a real-time dashboard lets you watch the process unfold. Beyond this orchestration loop, the system meta-trains smaller child agents directly on RL tasks, combining LLM-driven code generation with traditional RL training to produce increasingly capable policies!

Team

warrenfarhan-navas

Placement

Participant

More from OpenEnv Hackathon SF

Kube SRE Gym is a self-improving RL environment where a small language model (Qwen3-1.7B) learns to diagnose and fix real Kubernetes production incidents…

Noclue project preview

RL environment for autonomous biologist agents. Simulate an entire biological worldstate based on scientifically-accurate single-cell standards. Naive agents…

Zero Shot Cancer project preview

ShopRLVE-GYM HF Blog https://huggingface.co/blog/thebajajra/shop-rlve-gym

Lambda project preview

Our agent uses OpenEnv to build a curriculum of video game environments that train a TinyLlama 1.1B agent via GRPO reinforcement learning. We implement three…

Play-gent project preview

GAIA is an OpenEnv-compatible geospatial reasoning environment where an AI agent infers hidden real-world locations using multi-step tool calls (terrain…

drive.google.com/…

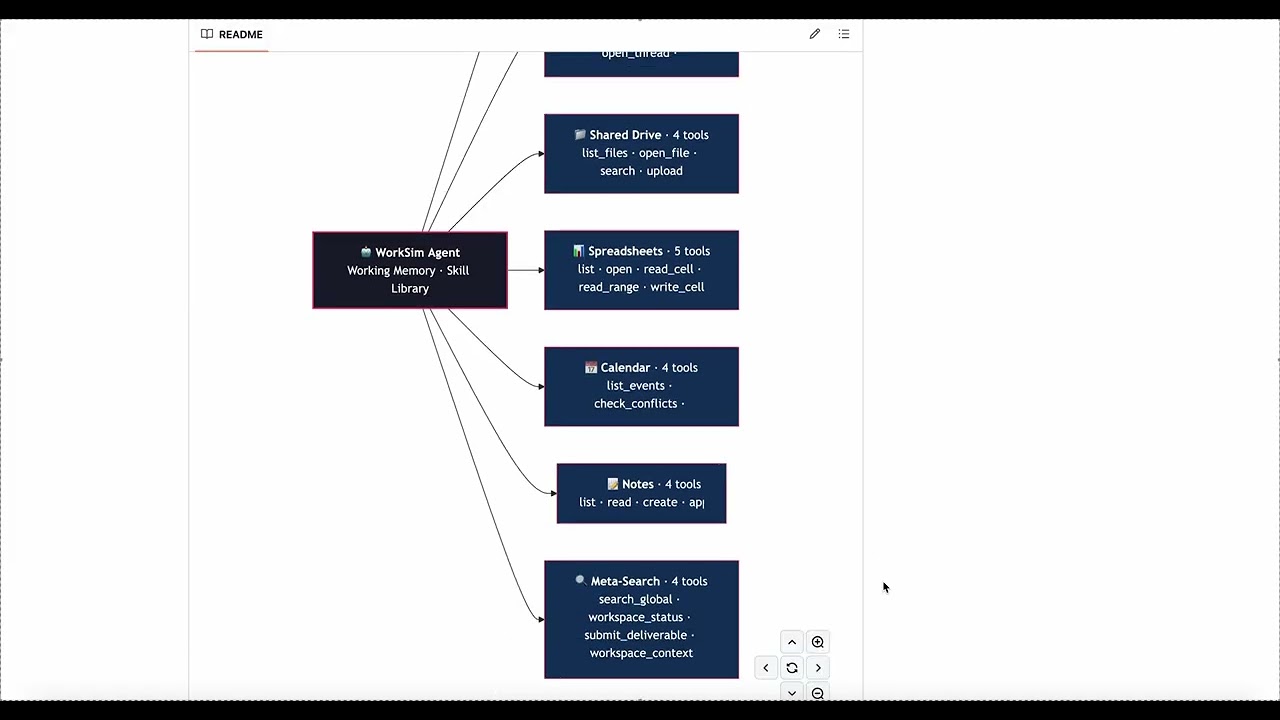
Voyager-VRAM is a long-horizon workplace simulator where LLM agents must navigate a realistic office environment ( emails, Slack, shared drive, spreadsheets…

Deepmind Ace project preview