Skip to Main Content

Upskiller is an RL environment that trains LLMs to agentically invoke skills — deciding which to load, when to unload, and when to submit under a context budget. SkillsBench shows skill invocation fails over half the time; we built Upskiller to close that gap. The environment uses synthetic, fictional skills that can't exist in training data, forcing generalization. Tasks are dynamically generated to prevent memorization. Rewards are deterministic and rules-based — code execution, structural verification, multi-part checks, no LLM judge. Our 5-signal reward trains correctness, precision, recall, context hygiene, and token efficiency. Trained with GRPO + LoRA (r=128) across Qwen 3 1.7B, 4B, and 8B using HF TRL. Built on OpenEnv 0.2.1, deployed on HF Spaces.
Team

Placement

Participant

More from OpenEnv Hackathon SF

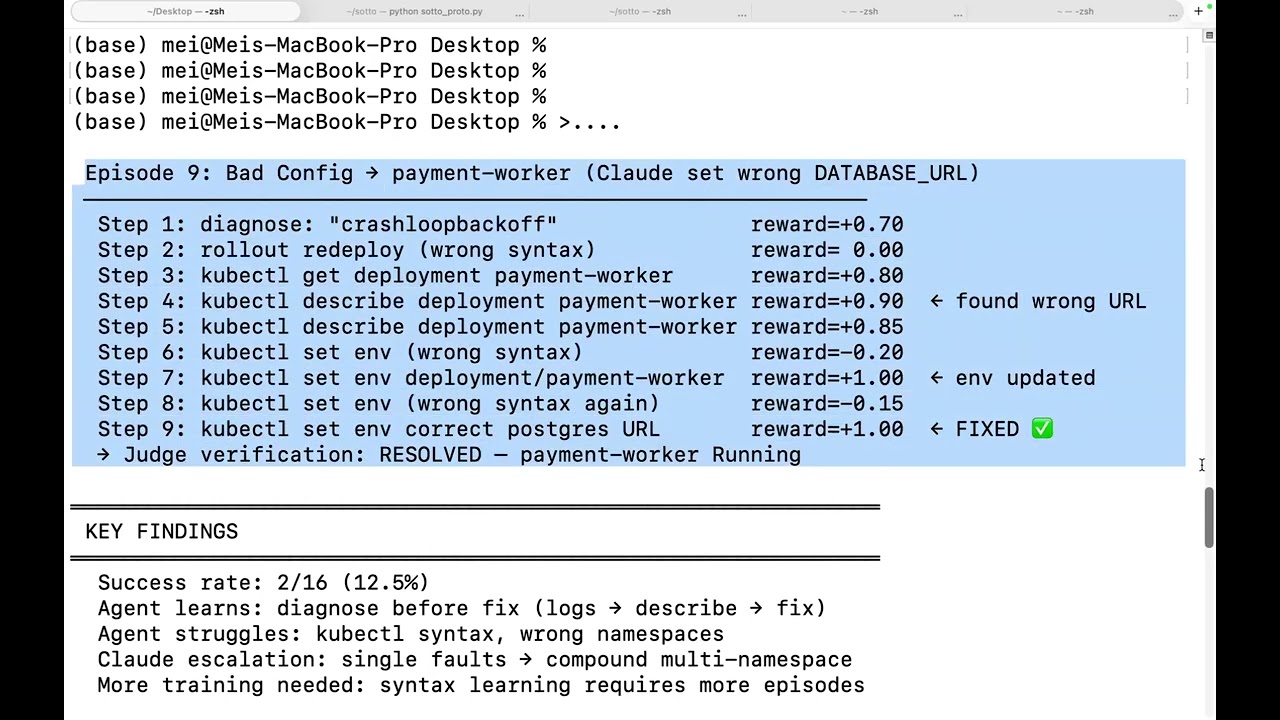
Kube SRE Gym is a self-improving RL environment where a small language model (Qwen3-1.7B) learns to diagnose and fix real Kubernetes production incidents…

Noclue project preview

RL environment for autonomous biologist agents. Simulate an entire biological worldstate based on scientifically-accurate single-cell standards. Naive agents…

Zero Shot Cancer project preview

ShopRLVE-GYM HF Blog https://huggingface.co/blog/thebajajra/shop-rlve-gym

Lambda project preview

Our agent uses OpenEnv to build a curriculum of video game environments that train a TinyLlama 1.1B agent via GRPO reinforcement learning. We implement three…

Play-gent project preview

GAIA is an OpenEnv-compatible geospatial reasoning environment where an AI agent infers hidden real-world locations using multi-step tool calls (terrain…

drive.google.com/…

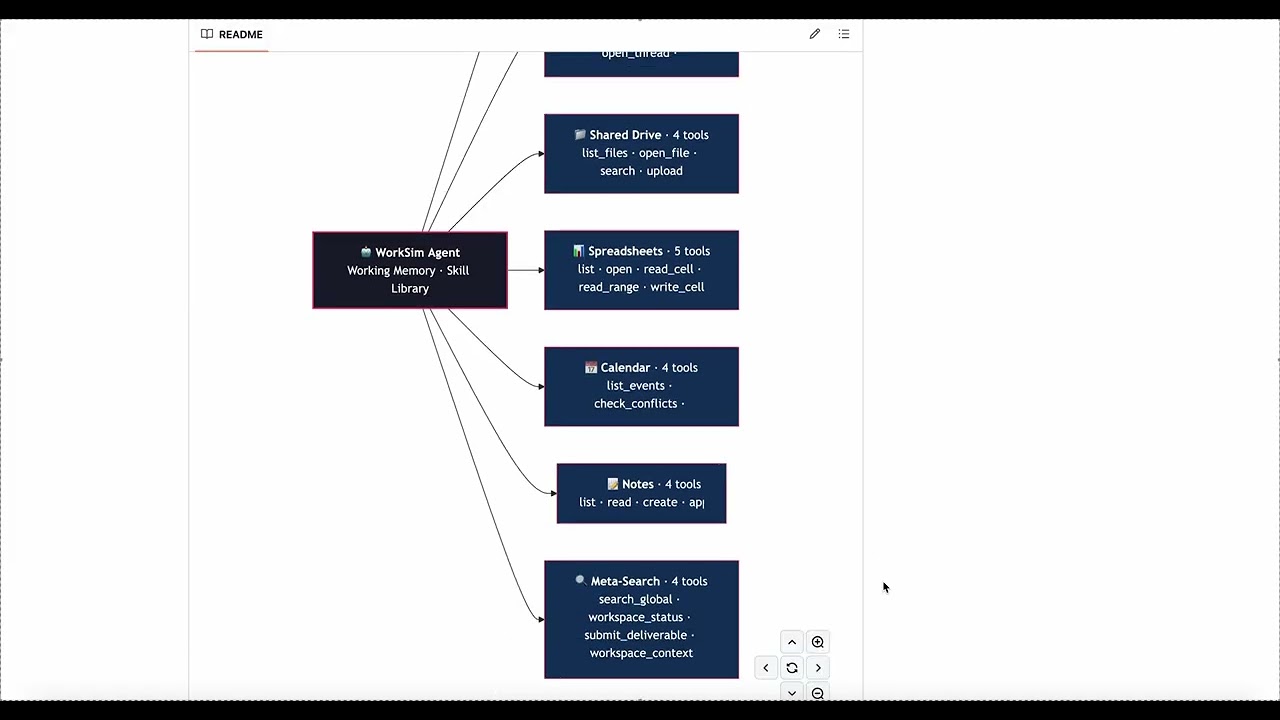
Voyager-VRAM is a long-horizon workplace simulator where LLM agents must navigate a realistic office environment ( emails, Slack, shared drive, spreadsheets…

Deepmind Ace project preview