Skip to Main Content

Hypernoa Astrum is an adaptive RL environment built on OpenEnv 0.2.1 that trains AI to reason, adapt, and align — not just solve tasks. It simulates 5 competing stakeholder groups (Workers, Management, Regulators, Customers, AI Systems), 3 dynamic phases (stable, value shift, crisis), and deliberately designed alignment traps that test whether AI agents cheat their reward function. The multi-objective reward measures effectiveness, fairness, alignment, and adaptability. Our trained agent reaches 24.7 reward starting from scratch, nearly matching the expert baseline at 25.1, while random scores only 14.6. All 3 alignment traps are resisted. Trained with HF TRL GRPO on Qwen2.5-0.5B using CoreWeave H100 via Northflank. Addresses Problem Statement 3.1 (World Modeling) and Statement 5 (Wild Card).

Team

Naidu

Placement

Participant

More from OpenEnv Hackathon SF

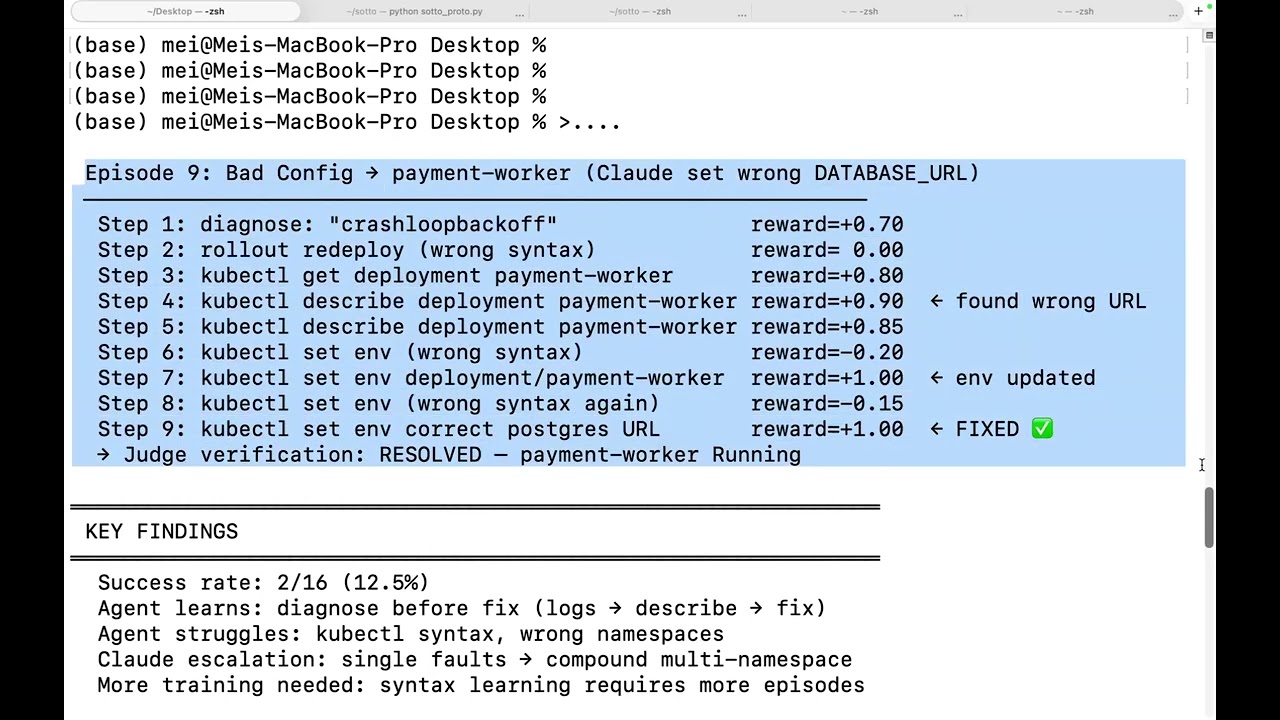
Kube SRE Gym is a self-improving RL environment where a small language model (Qwen3-1.7B) learns to diagnose and fix real Kubernetes production incidents…

Noclue project preview

RL environment for autonomous biologist agents. Simulate an entire biological worldstate based on scientifically-accurate single-cell standards. Naive agents…

Zero Shot Cancer project preview

ShopRLVE-GYM HF Blog https://huggingface.co/blog/thebajajra/shop-rlve-gym

Lambda project preview

Our agent uses OpenEnv to build a curriculum of video game environments that train a TinyLlama 1.1B agent via GRPO reinforcement learning. We implement three…

Play-gent project preview

GAIA is an OpenEnv-compatible geospatial reasoning environment where an AI agent infers hidden real-world locations using multi-step tool calls (terrain…

drive.google.com/…

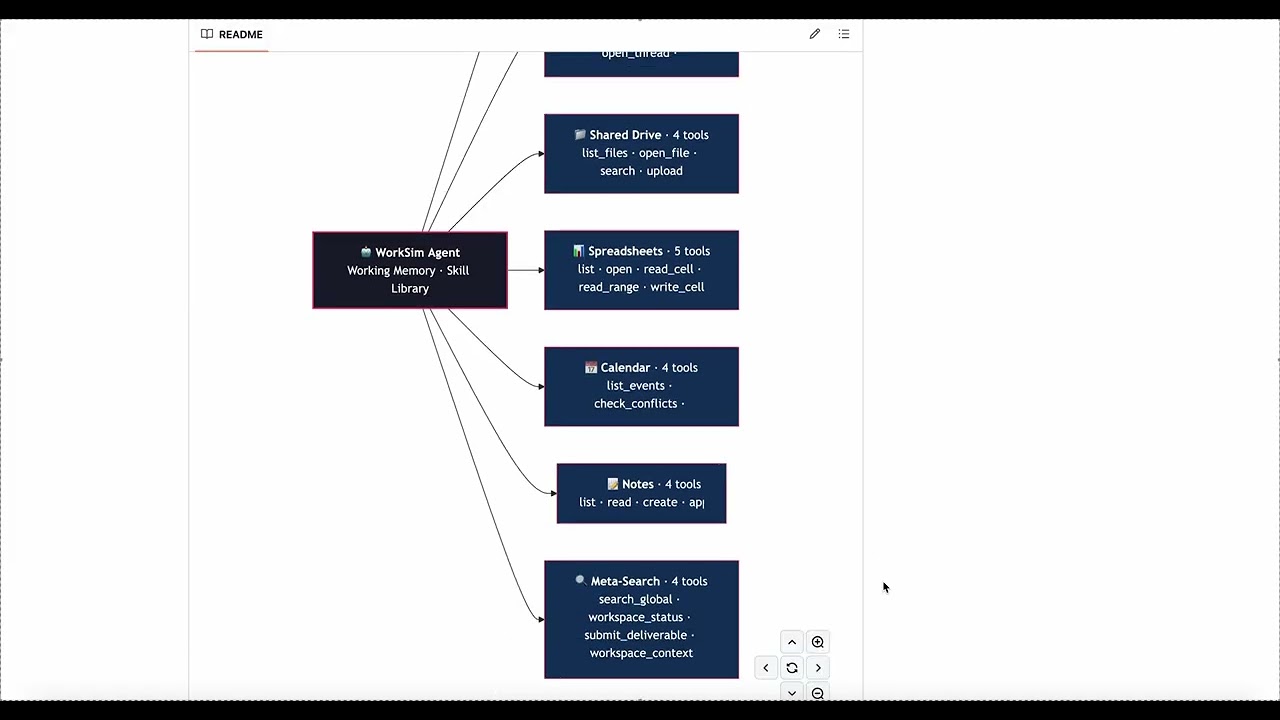
Voyager-VRAM is a long-horizon workplace simulator where LLM agents must navigate a realistic office environment ( emails, Slack, shared drive, spreadsheets…

Deepmind Ace project preview