Skip to Main Content

WatchDog is an RL environment training AI oversight agents to detect errors in real-time. It solves the gap where humans miss 60% of subtle AI hallucinations and logic flaws. This gym enables agents to make sequential decisions like passing or flagging turn-by-turn. The project uses the GRPO algorithm and LoRA adapters to remain fast and efficient. An adversarial arms race trains a detector and mutator via a minimax game for robustness. The system allows adding new domains like medical triage in just ten lines of code. Its reward structure penalizes false positives heavily to prevent hallucinated bugs. Training achieved a 15.4× accuracy jump and 5.7× recall increase in eighty minutes. The model shifted from indecision to making clear judgments on 77% of dialogue turns. Deployed on Hugging Face, WatchDog provides a production-grade gym for AI oversight.

Team

ziomPikkapikachurhemadri

Placement

Participant

More from OpenEnv Hackathon SF

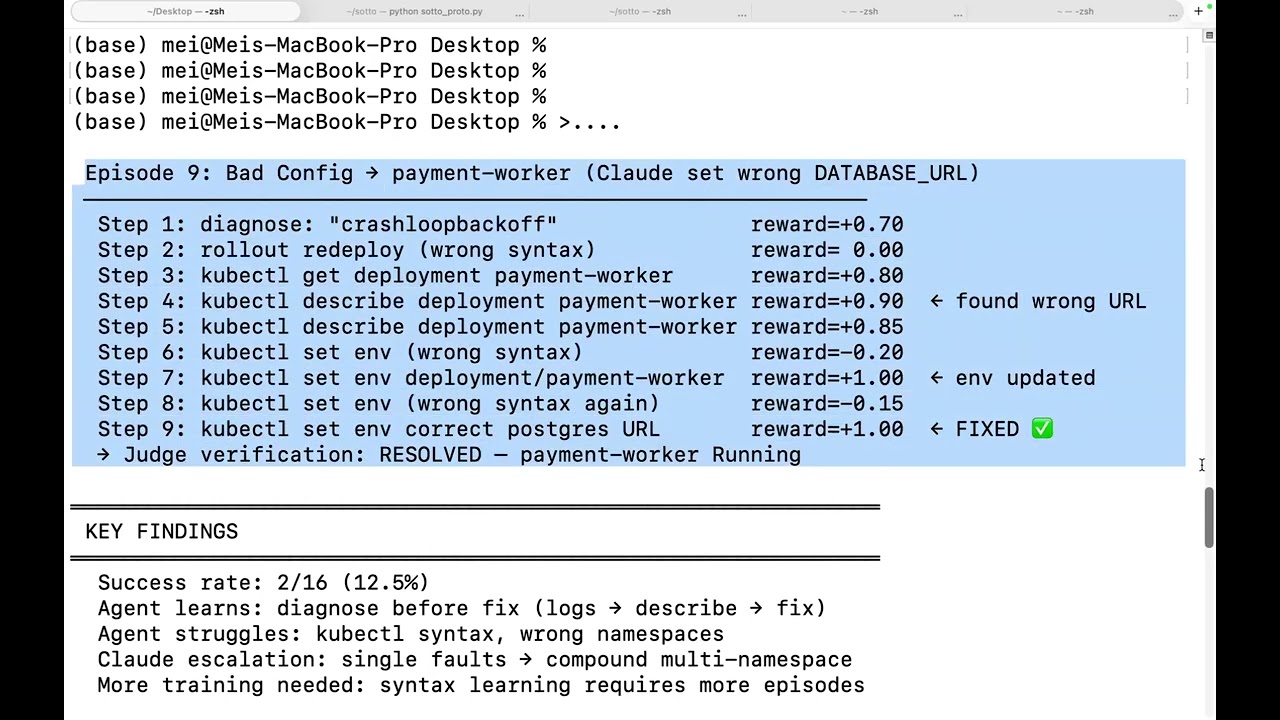
Kube SRE Gym is a self-improving RL environment where a small language model (Qwen3-1.7B) learns to diagnose and fix real Kubernetes production incidents…

Noclue project preview

RL environment for autonomous biologist agents. Simulate an entire biological worldstate based on scientifically-accurate single-cell standards. Naive agents…

Zero Shot Cancer project preview

ShopRLVE-GYM HF Blog https://huggingface.co/blog/thebajajra/shop-rlve-gym

Lambda project preview

Our agent uses OpenEnv to build a curriculum of video game environments that train a TinyLlama 1.1B agent via GRPO reinforcement learning. We implement three…

Play-gent project preview

GAIA is an OpenEnv-compatible geospatial reasoning environment where an AI agent infers hidden real-world locations using multi-step tool calls (terrain…

drive.google.com/…

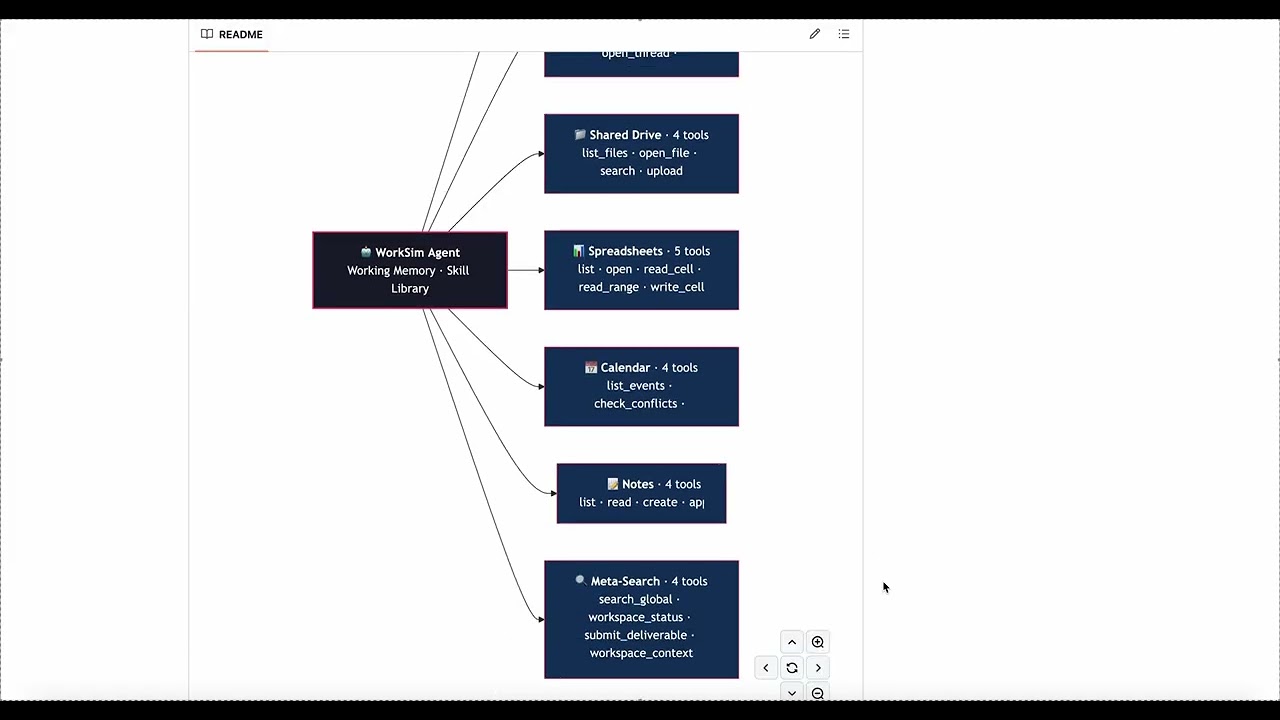
Voyager-VRAM is a long-horizon workplace simulator where LLM agents must navigate a realistic office environment ( emails, Slack, shared drive, spreadsheets…

Deepmind Ace project preview