Bug Catchers
Built at RAISE Summit Hackathon · Jul 4, 2026 · Paris, France
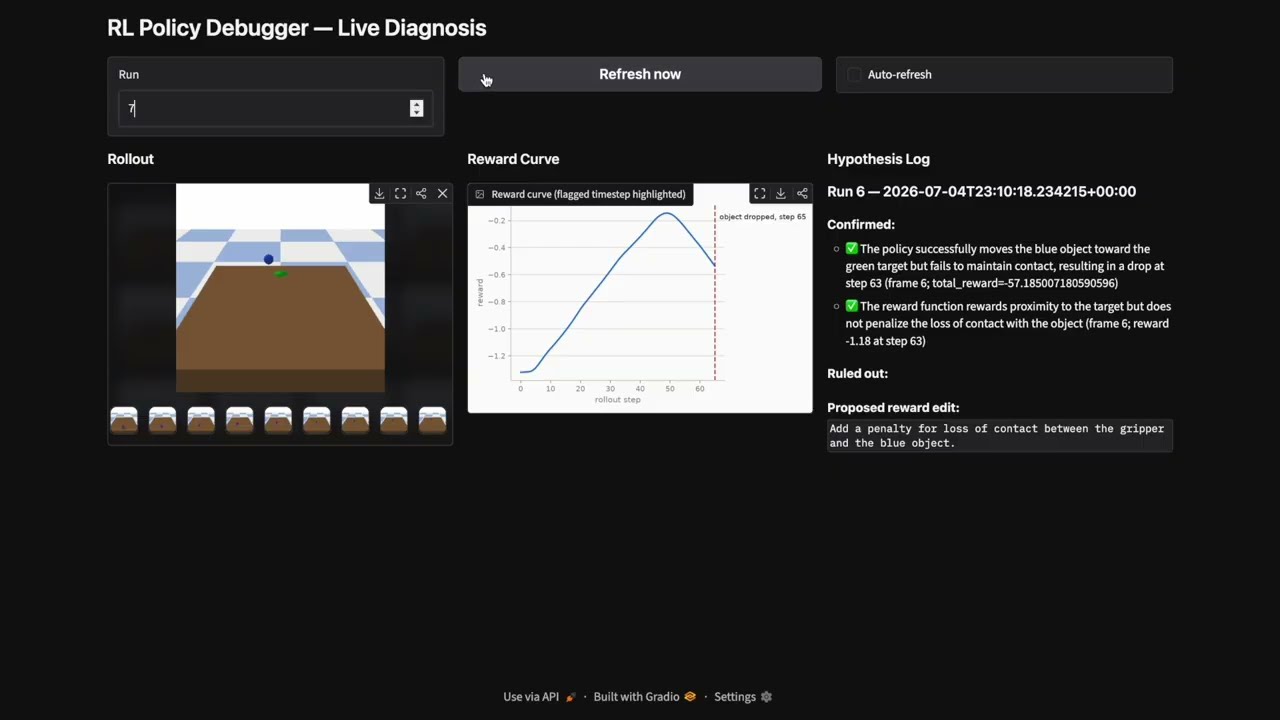
RL Policy Debugger is an agent that watches a robot's failed training runs — rollout video, reward curve, and structured logs together — and diagnoses why the policy is failing, entirely offline. It runs on Gemma 4 12B locally, with no cloud calls and no uploaded training data, making it usable in air-gapped robotics labs. Across ten independent training runs, including multiple distinct reward bugs, it builds and refines failure hypotheses persistently — confirming or ruling out ideas as new evidence arrives — the same way a human RL researcher builds understanding over time, and lands on a concrete proposed reward fix. Built for the Google DeepMind Track, Statement Five (Remote): "Best mobile, web, or edge application running Gemma locally for offline, privacy-first inference." Everything in this project — the simulation, the local Gemma inference pipeline, the agent loop, and the demo UI — was built during this 24-hour hackathon.