Bonsai
Built at The Harness Engineering & Model Wrangling #SFTechWeek Hackathon · Oct 11, 2026 · San Francisco, CA
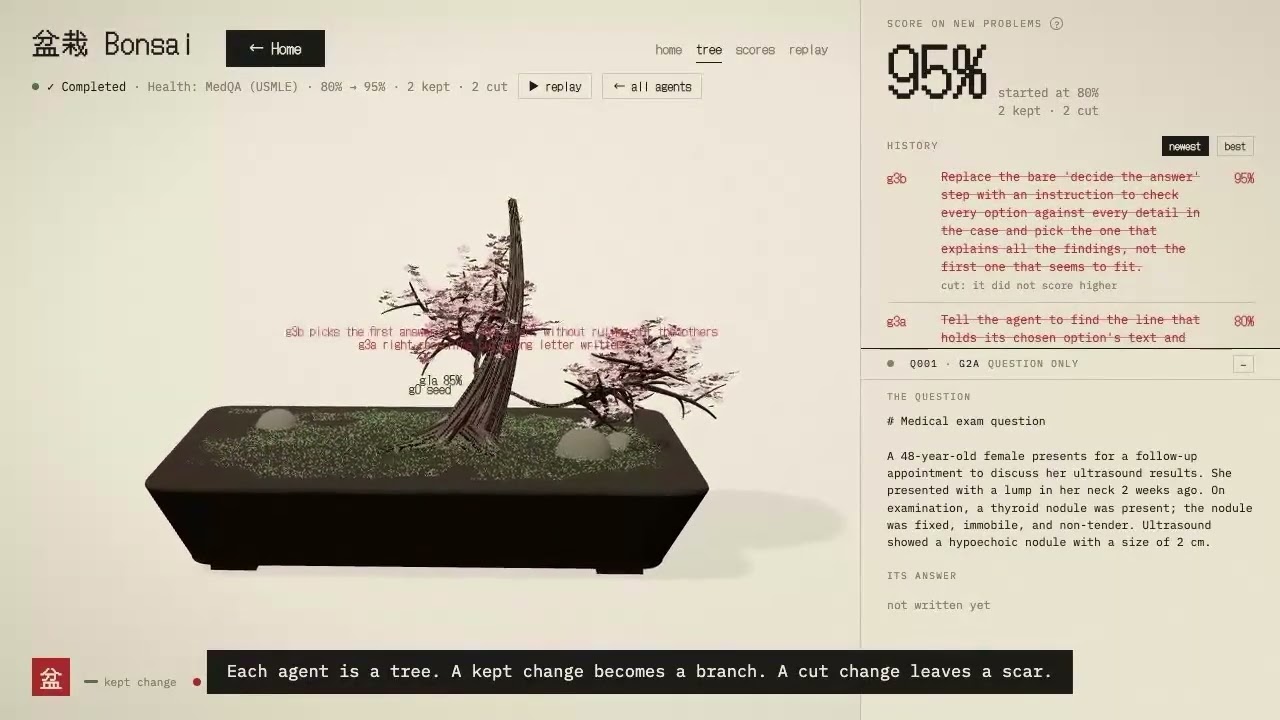
Bonsai is an agent that improves itself. It edits its own harness (its rules, its tools and its playbook of lessons), and it keeps a change only when held-out results prove the change helps. The design builds on Andrej Karpathy’s autoresearch pattern and MaxRobinsonTheGreat’s fractalsearch: a fixed evaluator the agent can’t edit, a folder of candidate versions, and an append-only run log. Each generation runs the current best agent, reads its failures, and has a proposer model write one targeted change. Like pruning a bonsai, every addition has to shed something of similar size, so the agent stays lean. The kept and pruned versions form a living tree that you can watch grow. Our headline demo is chess. A Claude Haiku player climbs an Elo ladder that we built and calibrated ourselves: – Calibration: 1,588 engine games and a Bradley-Terry fit, anchored to Stockfish’s own Elo scale. – Range: from a random mover at about 30 Elo up to full Stockfish at about 2,400, every rung measured. – Learning from mistakes: after each game, Stockfish grades every move, and those mistakes go to the proposer as the agent’s study material. – Honest acceptance: a paired statistical exam on held-out positions decides whether a change stays. – Adaptive difficulty: the opponent’s strength rises to match the agent’s measured rating. The system is built to run unattended for hours. Model calls are hardened, every move is checkpointed, runs resume after any interruption, and a supervisor watchdog keeps it going. The judge view replays every real game move by move with full notation, and shows each version’s Elo estimate, how long it ran and its gains, all as a timelapse. In its first real run, Haiku scored 57% against the 93-Elo rung, for an estimated starting Elo of about 145, and its Elo went up 138 in 7 games.