Frontier models can work for hours, but one hallucination can snowball into bad plans, tool calls, and wasted spend. Existing validation often catches this too late, while a live reviewer subagent adds major latency and cost. We built the middle ground: a harness with a live grounding score that triggers deeper RAC-style verification against ground truth data such as documentation only when needed. In our first benchmark, Jev was ~22× faster and ~20× cheaper than the control while maintaining same level of accuracy compared to ground truth.
More from The Harness Engineering & Model Wrangling Hackathon
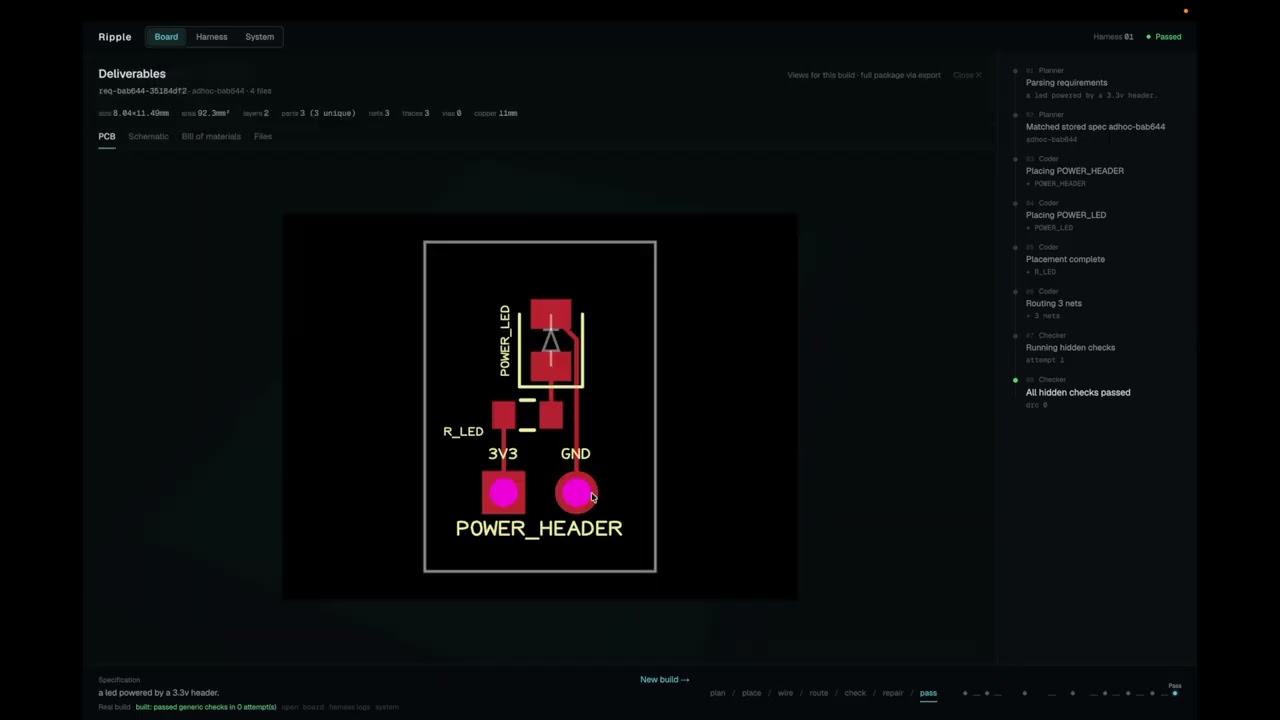
Ripple designs circuit boards from plain English, grades them against hidden checks, and evolves its own harness from the failures, going from 0/4 to 3/4 on…

 +1
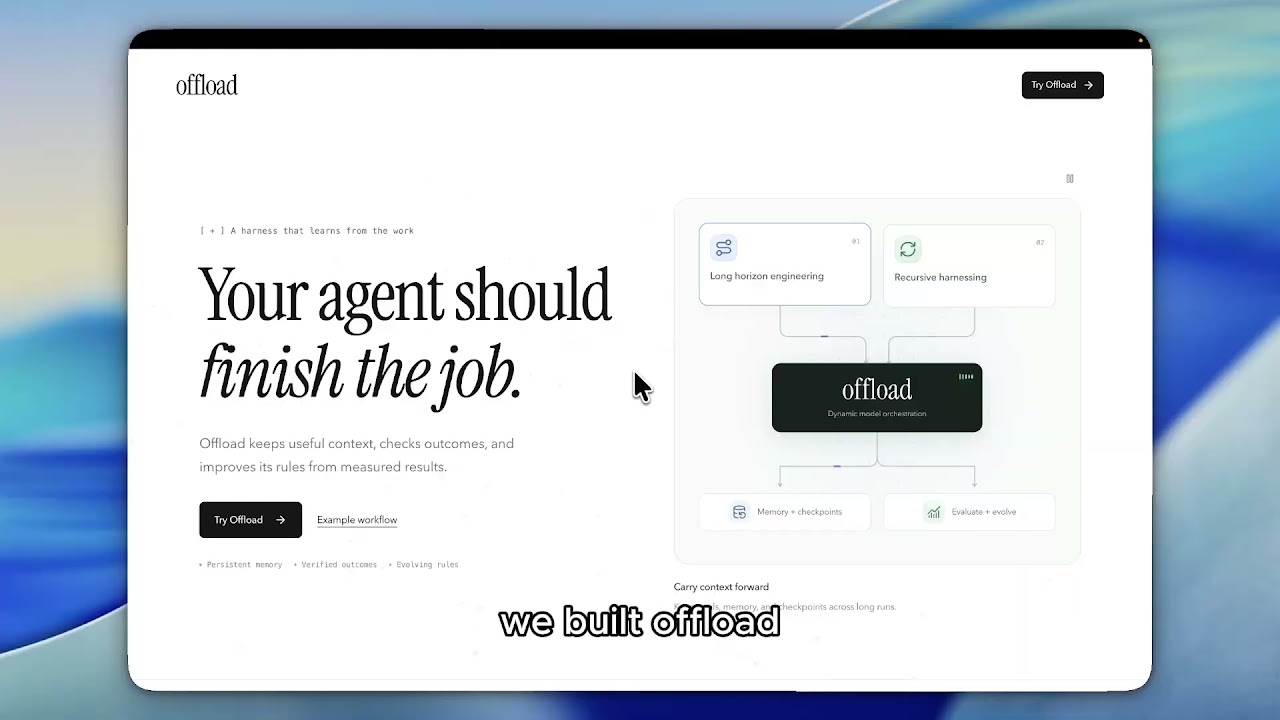
Offload learns the work you repeat, so next time you can hand it over. Its engine, REM (Replay · Evolve · Merge), is an agent harness with a day/night cycle…
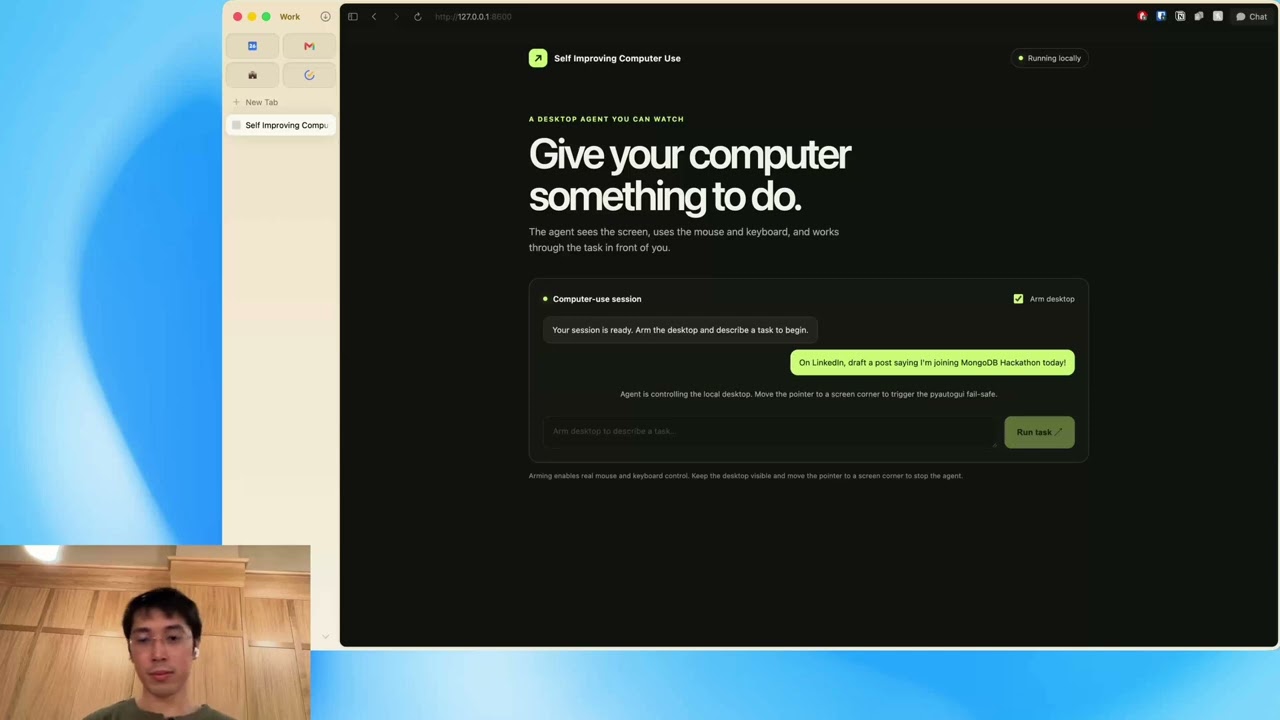
Recursive Computer Use is a local-first desktop automation harness that enables AI agents to execute tasks on your computer, verify outcomes locally, and…
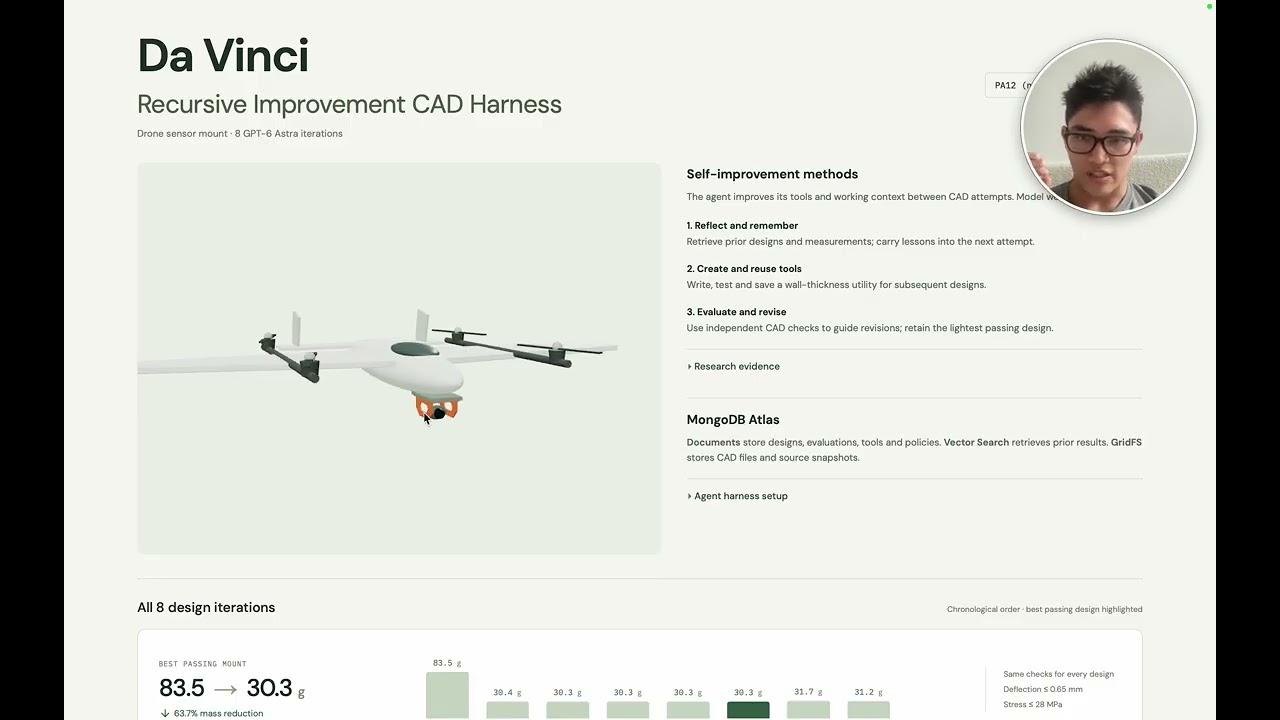
Da Vinci is a recursive improvement CAD harness designed to support physical engineering tasks through specialized AI agents, programmatic CAD and automated…
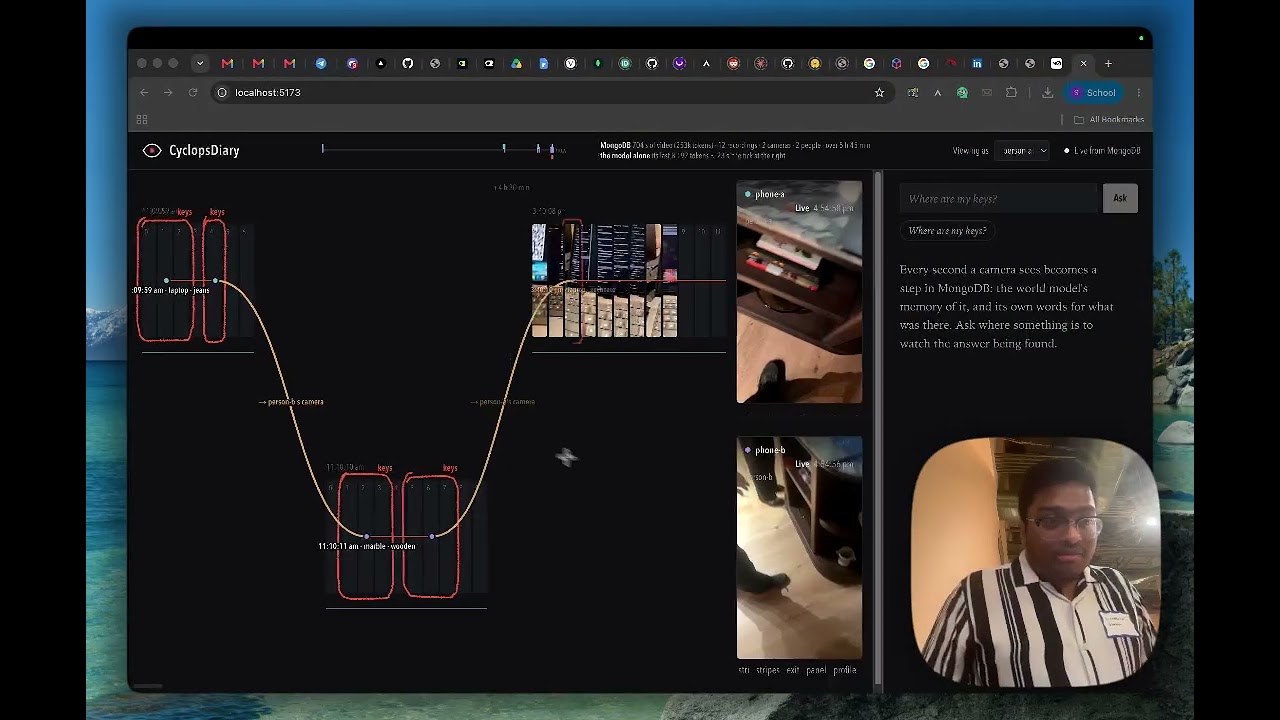
CyclopsDiary gives factory workers wearing Meta AI glasses a shared memory of the floor. Every worker's glasses feed one MongoDB memory that keeps what was…

A harness that teaches itself what context to show Jev, TypeSafe's fast decision model, proves the result on a storm it never saw, and can't cheat because…
www.loom.com/…