Red vs Blue: an agent that teaches itself to attack A self-improving agent harness, shown as a game. On a simulated office network, an AI attacker plays thousands of games against fixed defenses. After each game it writes short lessons to MongoDB Atlas, then recalls the relevant ones by meaning with Vector Search before its next move, so it stops repeating mistakes and climbs from clumsy to clever. You watch it learn in real time. The attack path lights up across the network, a recalled lesson card is pulled from memory mid move, and its win rate keeps rising game after game. Turn memory off and it forgets every game, which proves the learning is real. MongoDB isn't storage here. It's the memory that makes the agent adapt. Everything is a simulation: colored game pieces on a map, no real systems. Built with MongoDB Atlas, Vector Search, OpenRouter, and Next.js on Vercel.
More from The Harness Engineering & Model Wrangling Hackathon
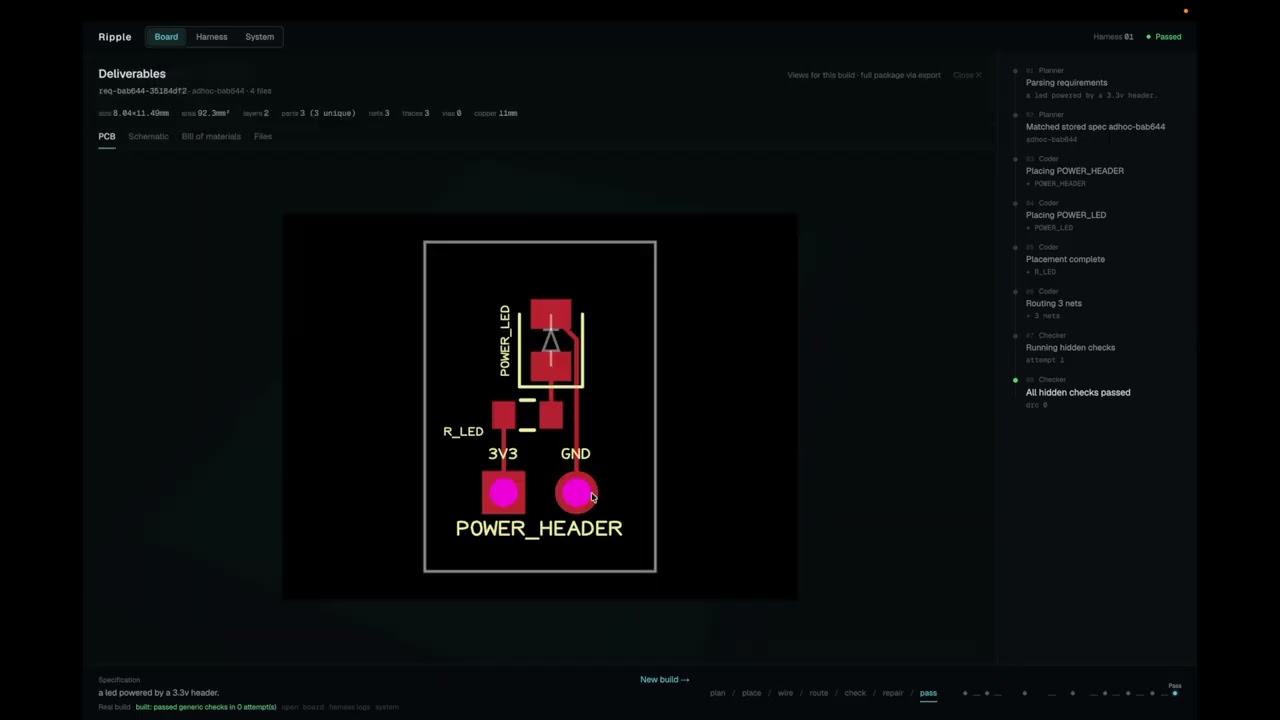
Ripple designs circuit boards from plain English, grades them against hidden checks, and evolves its own harness from the failures, going from 0/4 to 3/4 on…

 +1
Offload learns the work you repeat, so next time you can hand it over. Its engine, REM (Replay · Evolve · Merge), is an agent harness with a day/night cycle…
Recursive Computer Use is a local-first desktop automation harness that enables AI agents to execute tasks on your computer, verify outcomes locally, and…
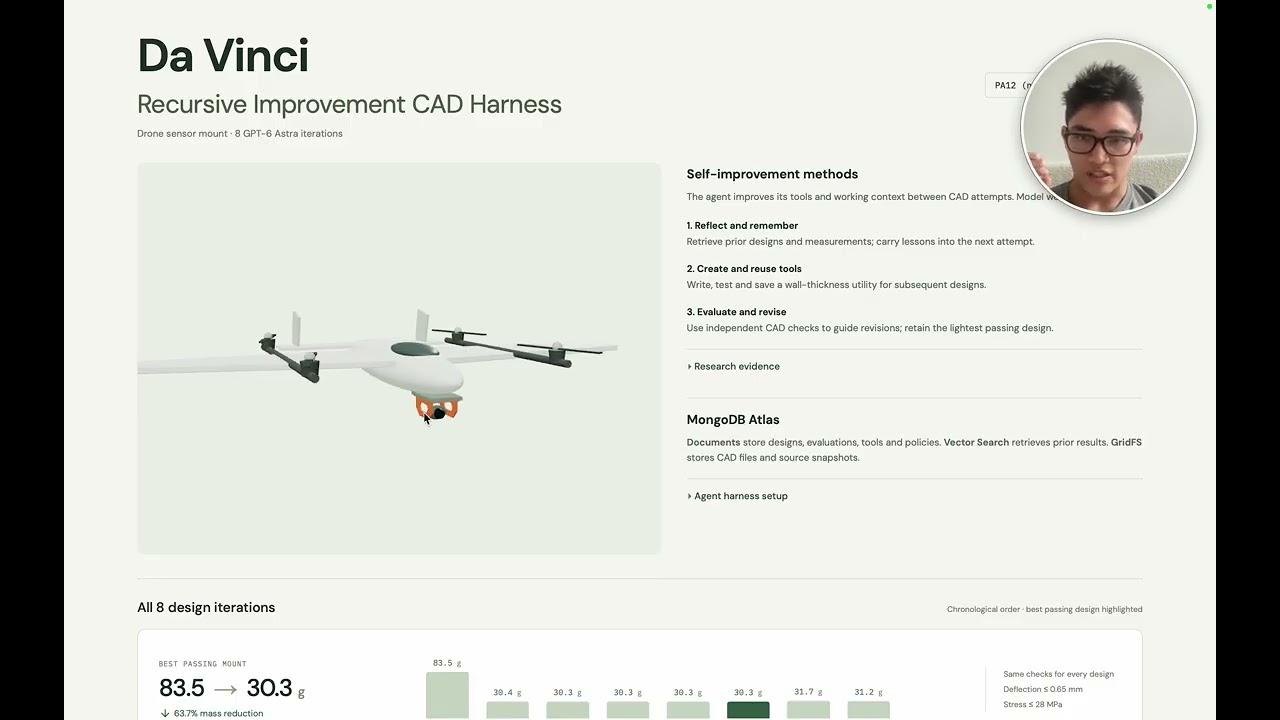
Da Vinci is a recursive improvement CAD harness designed to support physical engineering tasks through specialized AI agents, programmatic CAD and automated…
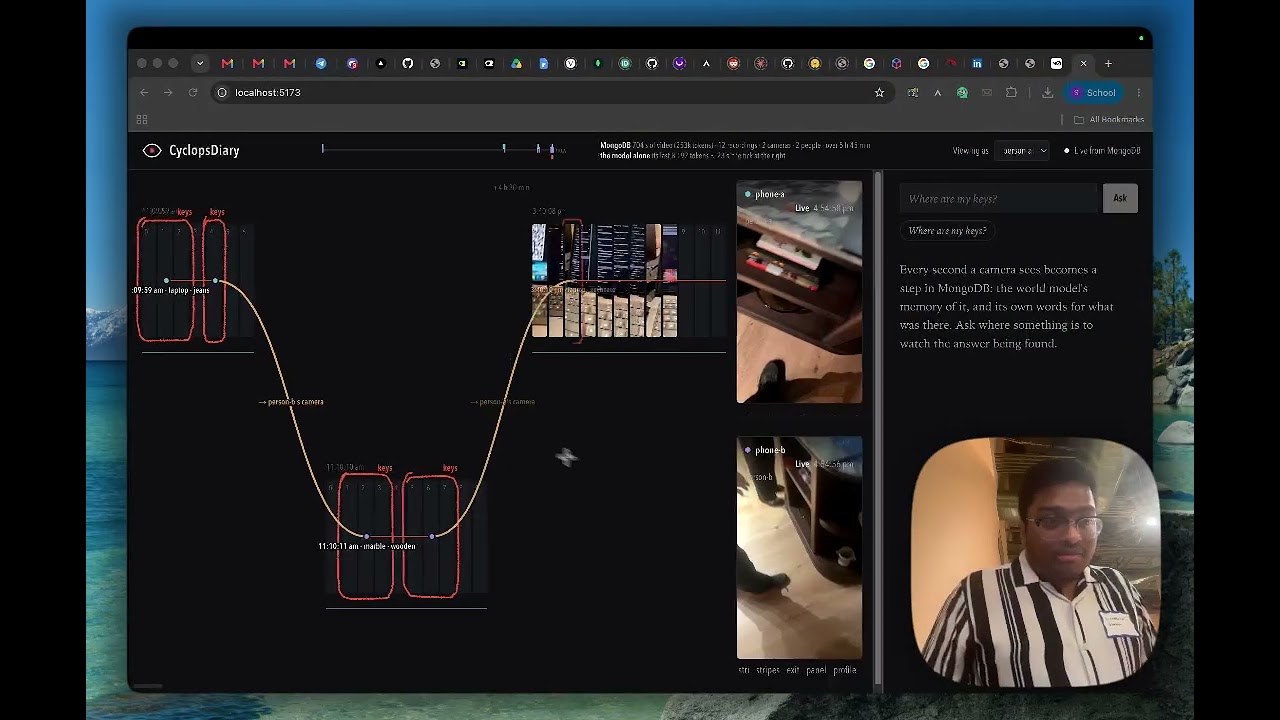
CyclopsDiary gives factory workers wearing Meta AI glasses a shared memory of the floor. Every worker's glasses feed one MongoDB memory that keeps what was…

A harness that teaches itself what context to show Jev, TypeSafe's fast decision model, proves the result on a storm it never saw, and can't cheat because…