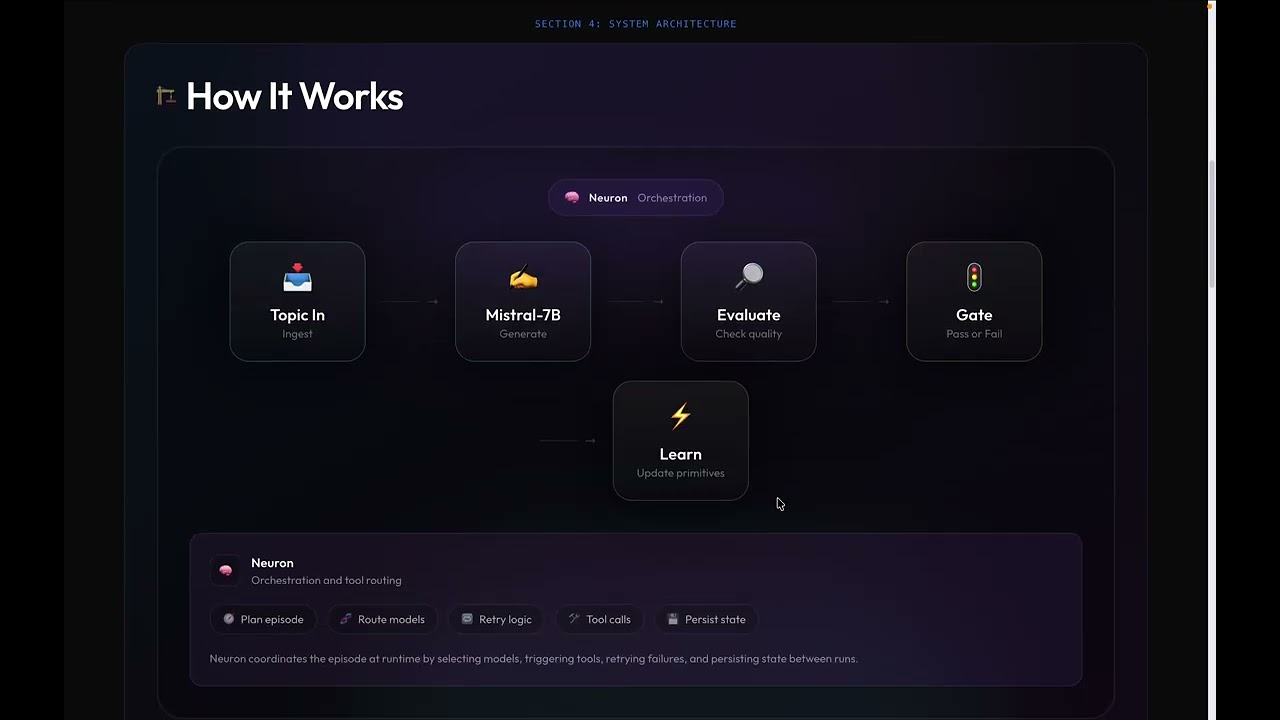
Frontier LLMs are generalists trying to squeeze every benchmark. We showcase a deployed application of "Learning to Discover at Test Time" (Yuksekgonul et al. 2026) which uses RL to overfit an LLM to maximise a metric for a particular task. We demonstrate that GPT-oss-120B using our TTT harness can outperform Claude Code and even the best humans when it comes to cuda kernel wrtiing.
More from WeaveHacks 3: Self-Improving Agents Hackathon with Weights & Biases
Cloud platforms like AWS and GCP are powerful, but their interfaces can be complex and unintuitive - especially for new users. Our project makes navigating…

Turn image into GLSL fragment shader code through self-improving agentic loops. https://shader-38ceag7cg-jessies-projects-a62a485b.vercel.app

Chameleon of the Dungeons is an intelligent login security suite designed primarily for ethical hackers and penetration testers to simulate, analyze, and test…

n live sports and real-time media, AI agents often fail because they are stateless, relying on static prompts that cannot be adjusted mid-broadcast when…

- Self-learning AI email agent that evolves with you over time - Discord-connected, Gmail-powered workflow - Builds a living relationship map from your…

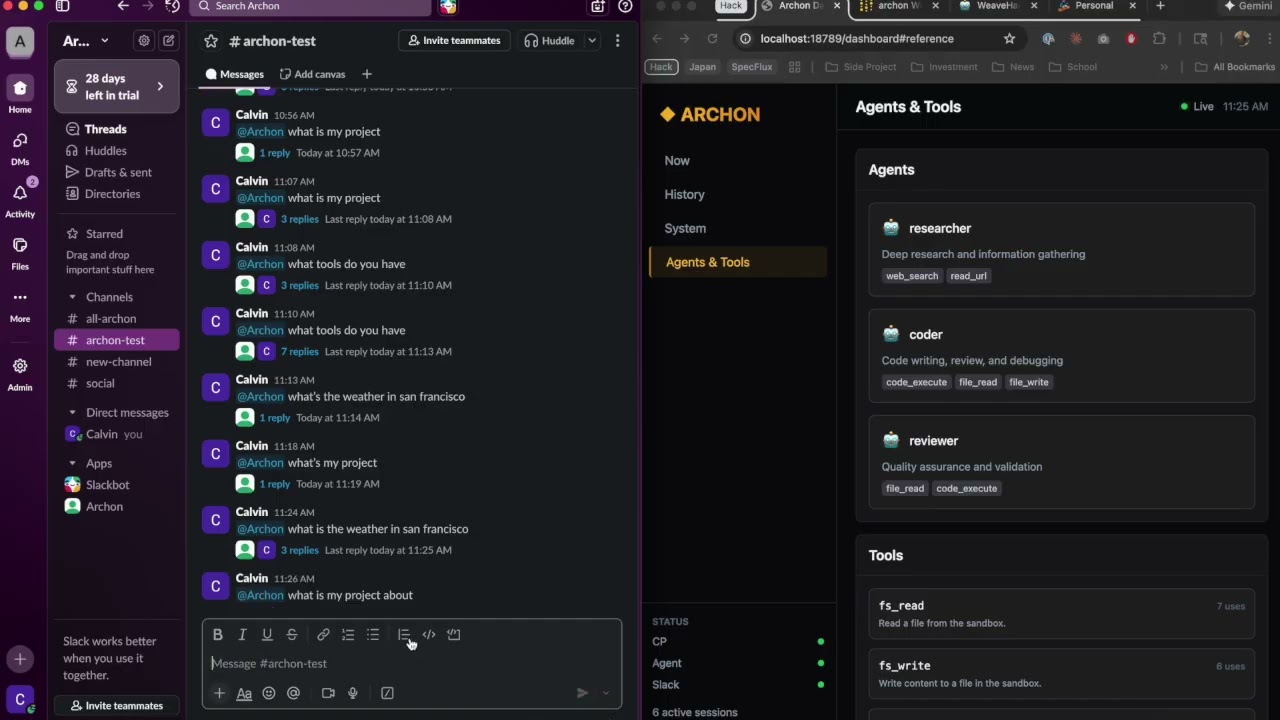
** github and basic model calling was created before hackday. all core functionarities are created during the weekend ** Archon is a self-improving AI…