Skip to Main Content

AlphaWolf is a self-play pipeline that teaches LLMs social deception through the game of Werewolf. A wolf agent plays, reflects on losses, rewinds to the critical decision point, and replays with an improved strategy. This approach resulted in Qwen3-8B-Thinking going from a 0.3 win rate to a 0.7 win rate over the span of only 45 games and 9 total gradient steps. The winning and losing transcripts become Direct Preference Optimization training pairs, while real-time consensus polling (every player votes on "who's suspicious?" after each speech) provides a novel auxiliary signal trained via ZIP-RC (ICLR 2026) to bootstrap a value function to the model. The result: a recursive self-improvement loop where the wolf gets better at deception, forcing villagers to adapt, driving emergent theory-of-mind.

Team
andreslexhacke

Placement

Participant

More from OpenEnv Hackathon SF

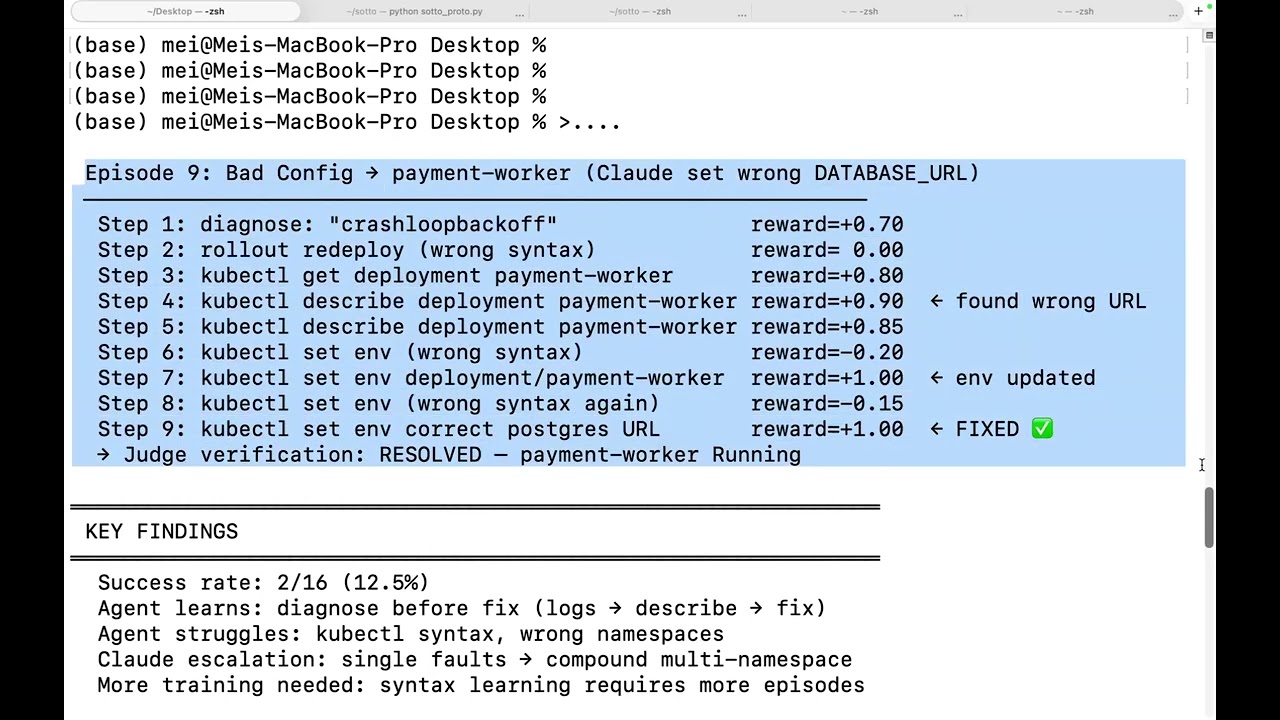
Kube SRE Gym is a self-improving RL environment where a small language model (Qwen3-1.7B) learns to diagnose and fix real Kubernetes production incidents…

Noclue project preview

RL environment for autonomous biologist agents. Simulate an entire biological worldstate based on scientifically-accurate single-cell standards. Naive agents…

Zero Shot Cancer project preview

ShopRLVE-GYM HF Blog https://huggingface.co/blog/thebajajra/shop-rlve-gym

Lambda project preview

Our agent uses OpenEnv to build a curriculum of video game environments that train a TinyLlama 1.1B agent via GRPO reinforcement learning. We implement three…

Play-gent project preview

GAIA is an OpenEnv-compatible geospatial reasoning environment where an AI agent infers hidden real-world locations using multi-step tool calls (terrain…

drive.google.com/…

Voyager-VRAM is a long-horizon workplace simulator where LLM agents must navigate a realistic office environment ( emails, Slack, shared drive, spreadsheets…

Deepmind Ace project preview