Skip to Main Content

OpenEnv-WolfeClick is an OpenEnv-compatible environment for training LLMs in competitive Pokemon Showdown battles. Rock-paper-scissors already shows how cyclic matchups create nontrivial reasoning; Pokemon scales that into a much richer world with hidden information, many possible matchups, legal action constraints, and long-term consequences. The model must choose exactly one valid move or switch each turn from the live battle state. We collect real rollout trajectories from battles and train a LoRA adapter with GRPO using actual environment reward, shaped by signals like damage, knockouts, setup, healing, status, and illegal-action penalties. The project fits Multi-Agent Interactions and Long-Horizon Planning, and demonstrates an end-to-end OpenEnv training loop for strategic decision-making under uncertainty.

Team

ouchllamaadityabangde

Placement

Participant

More from OpenEnv Hackathon SF

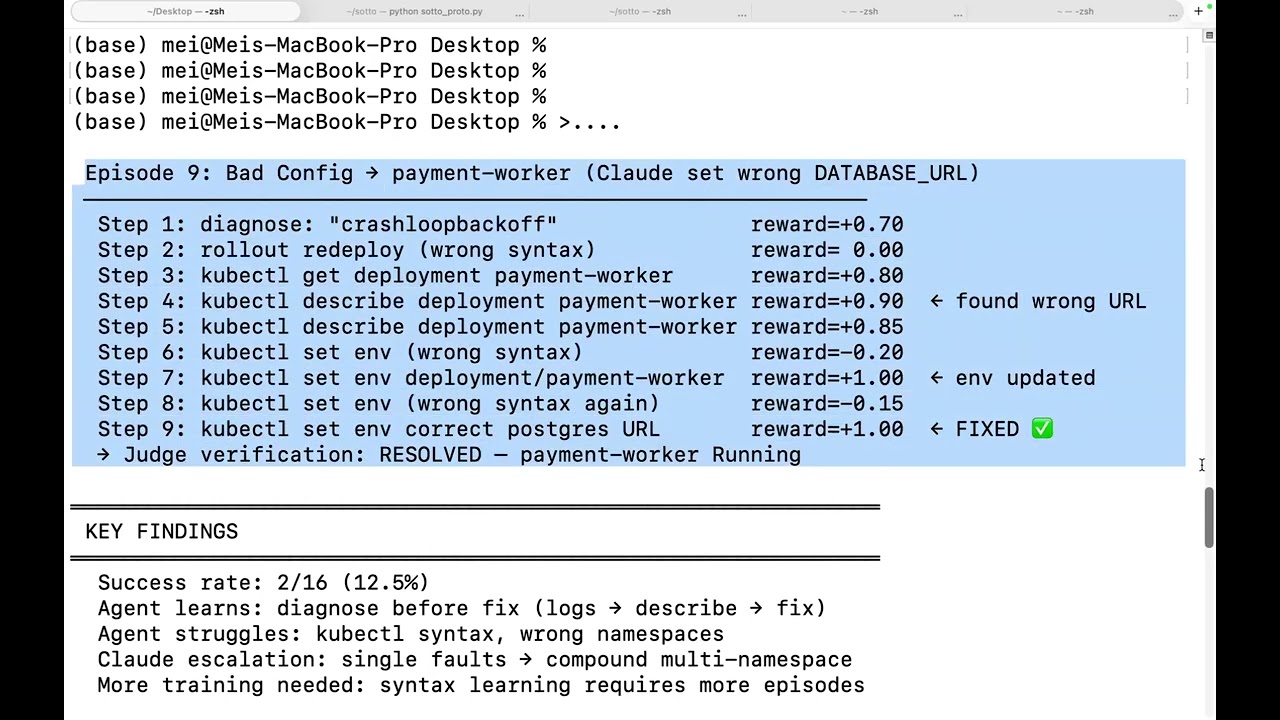
Kube SRE Gym is a self-improving RL environment where a small language model (Qwen3-1.7B) learns to diagnose and fix real Kubernetes production incidents…

Noclue project preview

RL environment for autonomous biologist agents. Simulate an entire biological worldstate based on scientifically-accurate single-cell standards. Naive agents…

Zero Shot Cancer project preview

ShopRLVE-GYM HF Blog https://huggingface.co/blog/thebajajra/shop-rlve-gym

Lambda project preview

Our agent uses OpenEnv to build a curriculum of video game environments that train a TinyLlama 1.1B agent via GRPO reinforcement learning. We implement three…

Play-gent project preview

GAIA is an OpenEnv-compatible geospatial reasoning environment where an AI agent infers hidden real-world locations using multi-step tool calls (terrain…

drive.google.com/…

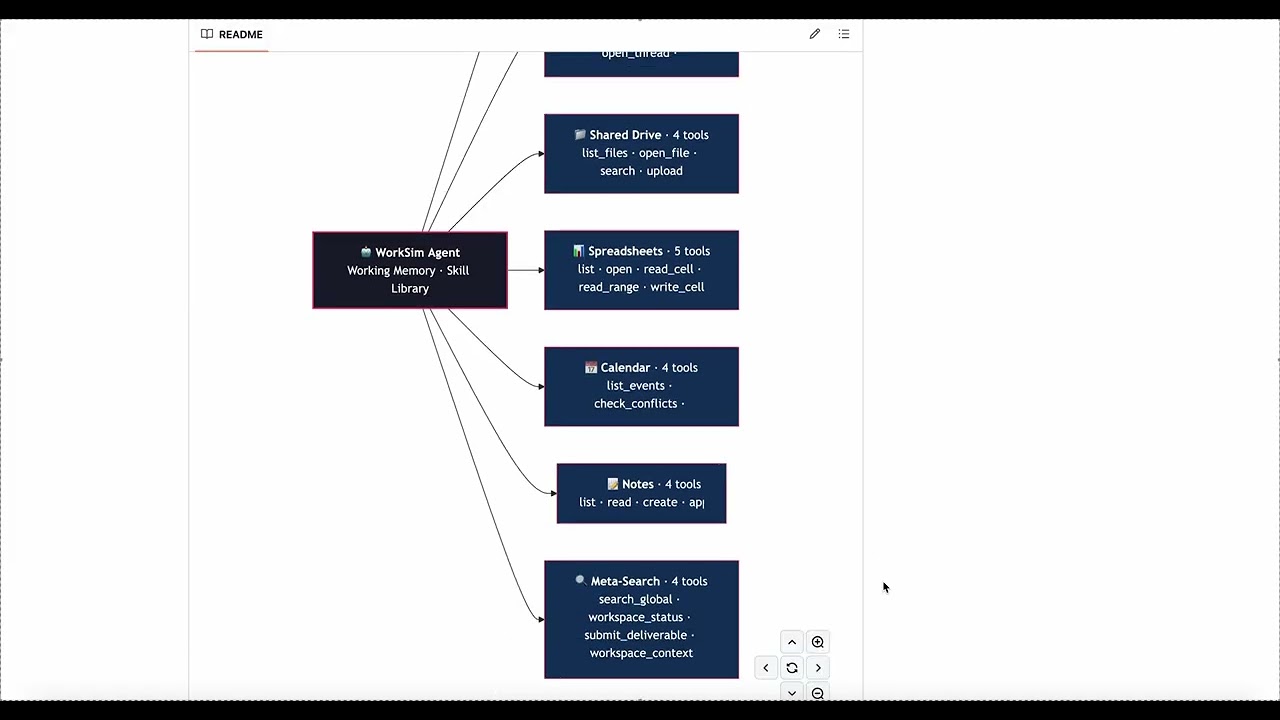
Voyager-VRAM is a long-horizon workplace simulator where LLM agents must navigate a realistic office environment ( emails, Slack, shared drive, spreadsheets…

Deepmind Ace project preview