Skip to Main Content

The bottleneck for RL-trained LLMs isn't algorithms — it's environments. We have GRPO and compute, but no scalable way to create diverse, realistic training environments. EnterpriseSimulator explores one approach: growing RL environments from simulated worlds instead of hand-crafting them. 1. Simulate a rich world — A Smallville-style multi-agent sim where LLM-powered customers, staff, and managers interact, producing organic scenarios. 2. Mine tasks — A task miner extracts RL-ready scenarios automatically from simulation data. 3. Train via OpenEnv — Each task becomes a gym-like env with reset/step/reward. The agent interacts with simulated customers. Reward = resolution + satisfaction + efficiency. The key insight: world simulation is environment generation. You don't write scenarios — you grow them. This pattern (simulate → mine → train) could generalize to any domain.
Team

Placement

Participant

More from OpenEnv Hackathon SF

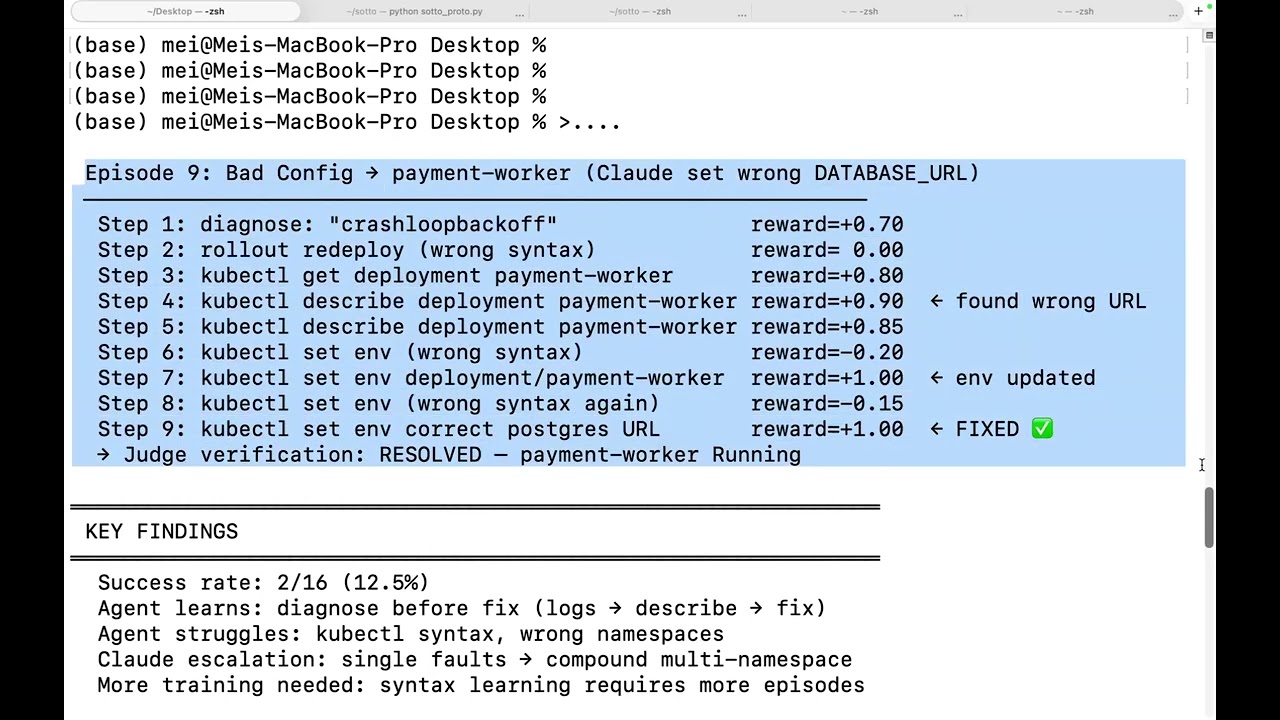
Kube SRE Gym is a self-improving RL environment where a small language model (Qwen3-1.7B) learns to diagnose and fix real Kubernetes production incidents…

Noclue project preview

RL environment for autonomous biologist agents. Simulate an entire biological worldstate based on scientifically-accurate single-cell standards. Naive agents…

Zero Shot Cancer project preview

ShopRLVE-GYM HF Blog https://huggingface.co/blog/thebajajra/shop-rlve-gym

Lambda project preview

Our agent uses OpenEnv to build a curriculum of video game environments that train a TinyLlama 1.1B agent via GRPO reinforcement learning. We implement three…

Play-gent project preview

GAIA is an OpenEnv-compatible geospatial reasoning environment where an AI agent infers hidden real-world locations using multi-step tool calls (terrain…

drive.google.com/…

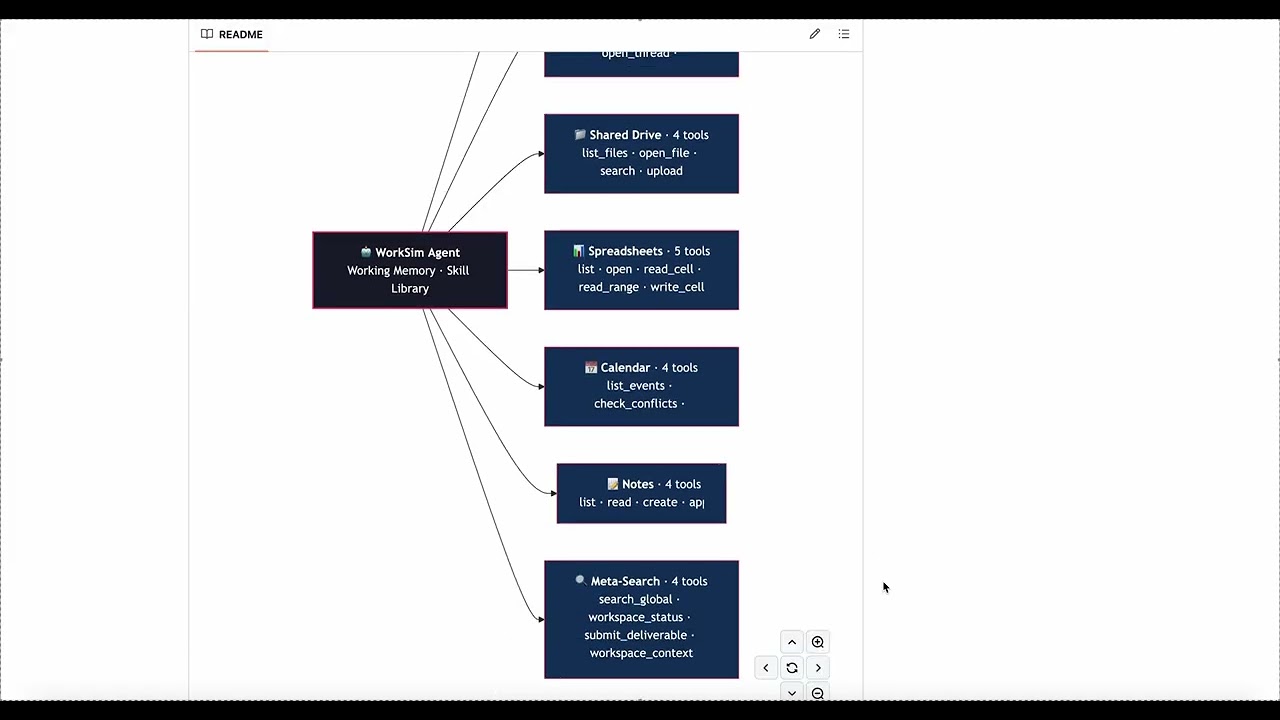
Voyager-VRAM is a long-horizon workplace simulator where LLM agents must navigate a realistic office environment ( emails, Slack, shared drive, spreadsheets…

Deepmind Ace project preview