Killer Sumdoku is a harder version of Sudoku. Computers use brute force (recursive) Depth First Search to solve, but humans treat this as a very long horizon reasoning problem (a single puzzle can take many hours!). If we can create an environment where playing the puzzle like a human is rewarded and brute-forcing/guessing is penalized, we have a very good env for long-horizon reasoning. There is also room for self-play curriculum: if the model does good / bad in a running average of 5 games, we make the next puzzles harder / easier (increase puzzle difficulty number by how populated it is in the beginning as well as how big the grid is).
More from OpenEnv Hackathon SF
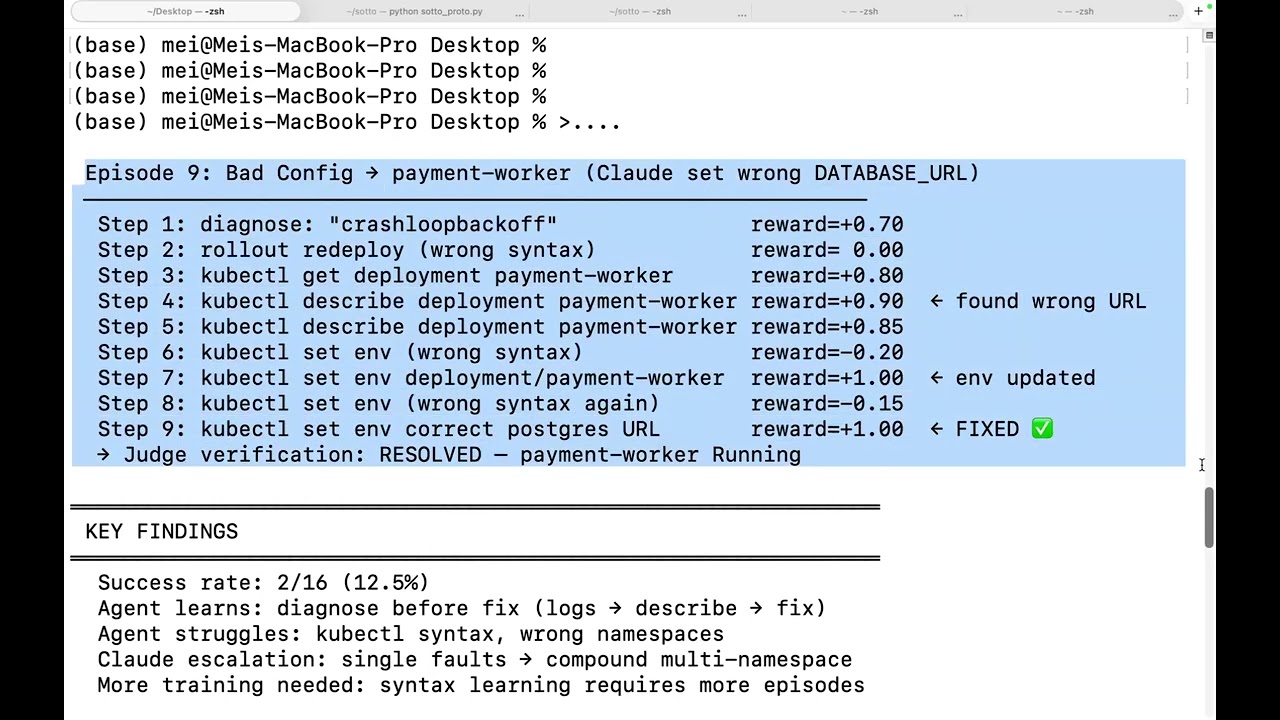
Kube SRE Gym is a self-improving RL environment where a small language model (Qwen3-1.7B) learns to diagnose and fix real Kubernetes production incidents…


RL environment for autonomous biologist agents. Simulate an entire biological worldstate based on scientifically-accurate single-cell standards. Naive agents…


ShopRLVE-GYM HF Blog https://huggingface.co/blog/thebajajra/shop-rlve-gym


Our agent uses OpenEnv to build a curriculum of video game environments that train a TinyLlama 1.1B agent via GRPO reinforcement learning. We implement three…
GAIA is an OpenEnv-compatible geospatial reasoning environment where an AI agent infers hidden real-world locations using multi-step tool calls (terrain…
drive.google.com/…
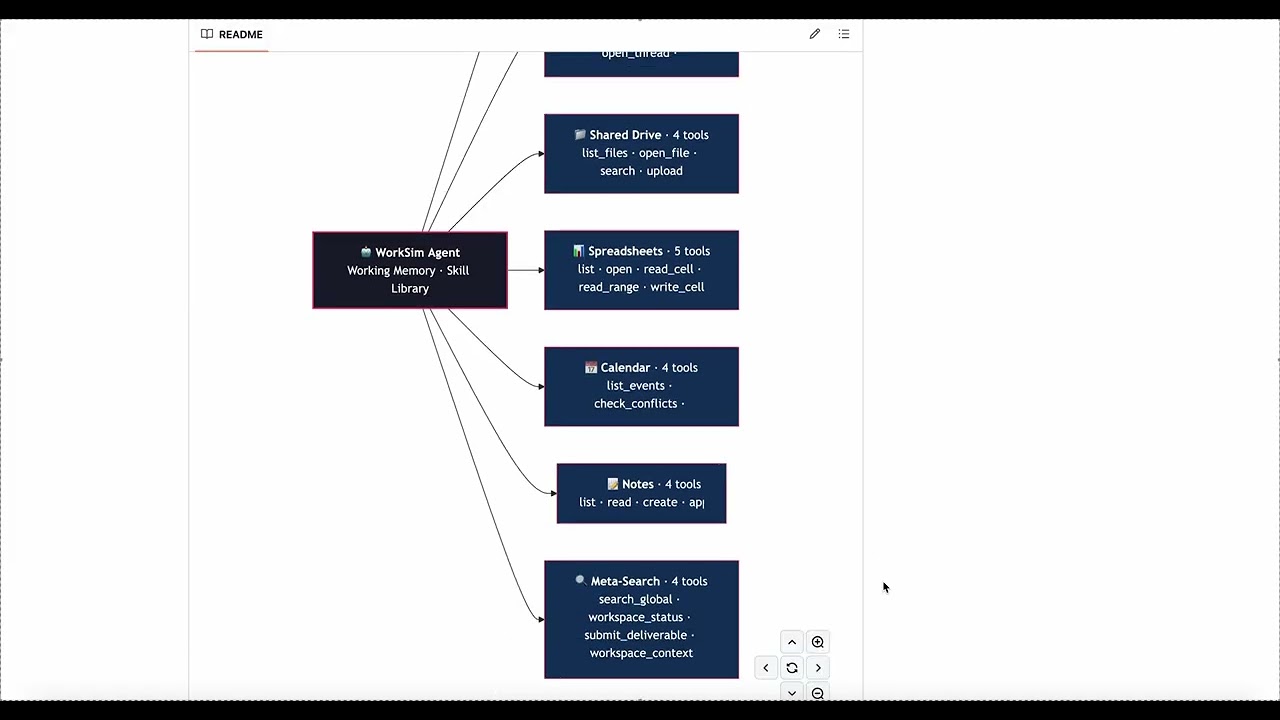
Voyager-VRAM is a long-horizon workplace simulator where LLM agents must navigate a realistic office environment ( emails, Slack, shared drive, spreadsheets…