Skip to Main Content

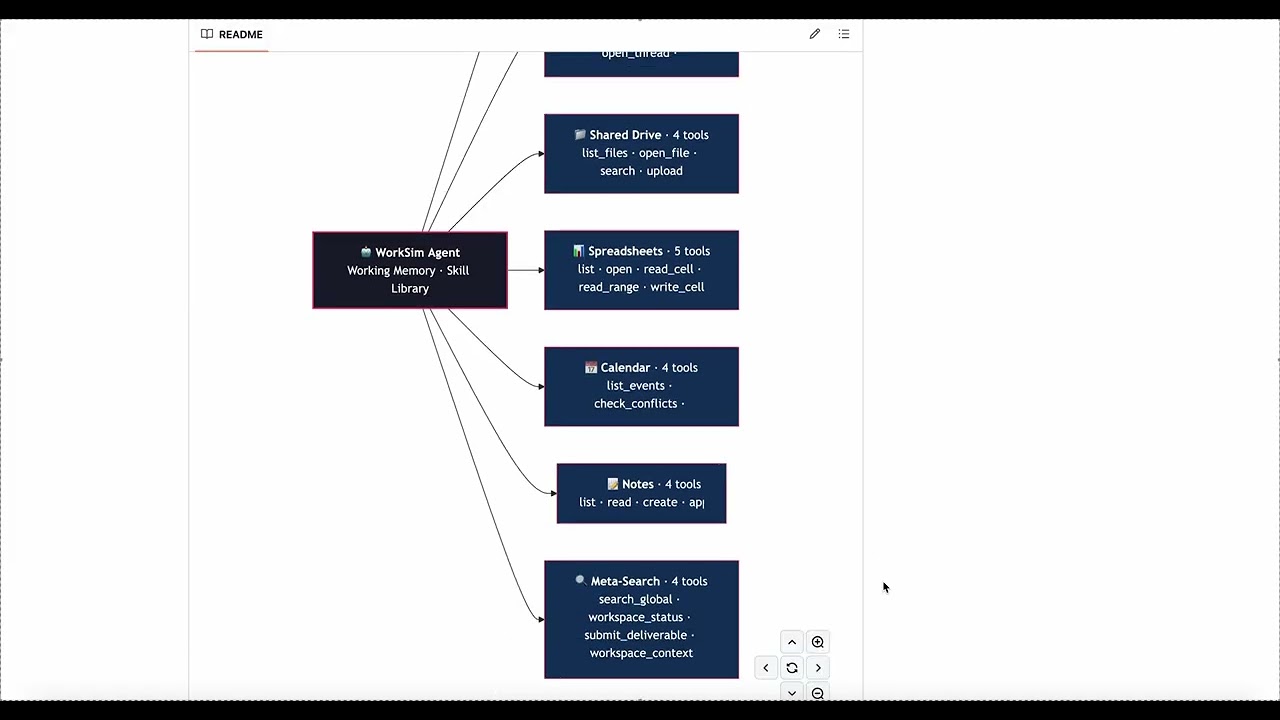
We enable models to hillclimb non-computationally verifiable domains through a co-evolutionary training setup, where a Dungeon Master agent procedurally generates increasingly difficult escape-room worlds and a Hero agent learns to solve them through long-horizon, tool-based reasoning, external scratchpad planning, and recovery from uncertainty, with reward signals that shape exploration, inference, and correct execution. We then validate that the learned behavior is not just map-specific by swapping the world surface from game objects (rooms/items/guards) to application-style entities (apps/docs/messages/apis) while keeping the same planning and interaction loop, showing measurable gains in reward and success under harder environments and richer task variants.

Team

bxptr

Placement

Participant

More from OpenEnv Hackathon SF

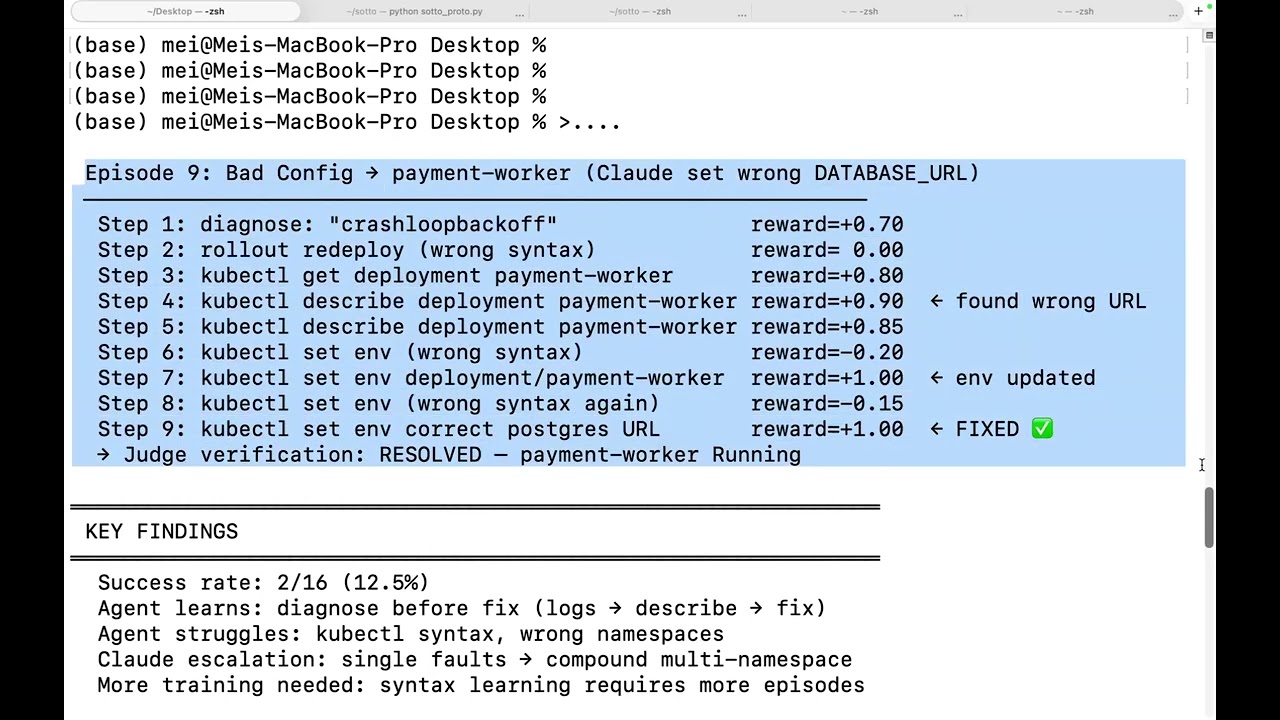
Kube SRE Gym is a self-improving RL environment where a small language model (Qwen3-1.7B) learns to diagnose and fix real Kubernetes production incidents…

Noclue project preview

RL environment for autonomous biologist agents. Simulate an entire biological worldstate based on scientifically-accurate single-cell standards. Naive agents…

Zero Shot Cancer project preview

ShopRLVE-GYM HF Blog https://huggingface.co/blog/thebajajra/shop-rlve-gym

Lambda project preview

Our agent uses OpenEnv to build a curriculum of video game environments that train a TinyLlama 1.1B agent via GRPO reinforcement learning. We implement three…

Play-gent project preview

GAIA is an OpenEnv-compatible geospatial reasoning environment where an AI agent infers hidden real-world locations using multi-step tool calls (terrain…

drive.google.com/…

Voyager-VRAM is a long-horizon workplace simulator where LLM agents must navigate a realistic office environment ( emails, Slack, shared drive, spreadsheets…

Deepmind Ace project preview