Skip to Main Content

Every time you use an AI coding assistant, you correct it. You rephrase, redirect, steer it back. Those corrections encode what you mean when you say things, your taste, your design directions. Right now that signal disappears. The next session starts from scratch. We built the loop that captures and refines models with it. This is the first partial implementation of OpenEnv RFC 005: an RL gym that trains a coding agent on your own dev sessions, scored by your own test suite, so the model gets incrementally better at understanding you specifically.

Team

natnaelkahssay

Placement

Participant

More from OpenEnv Hackathon SF

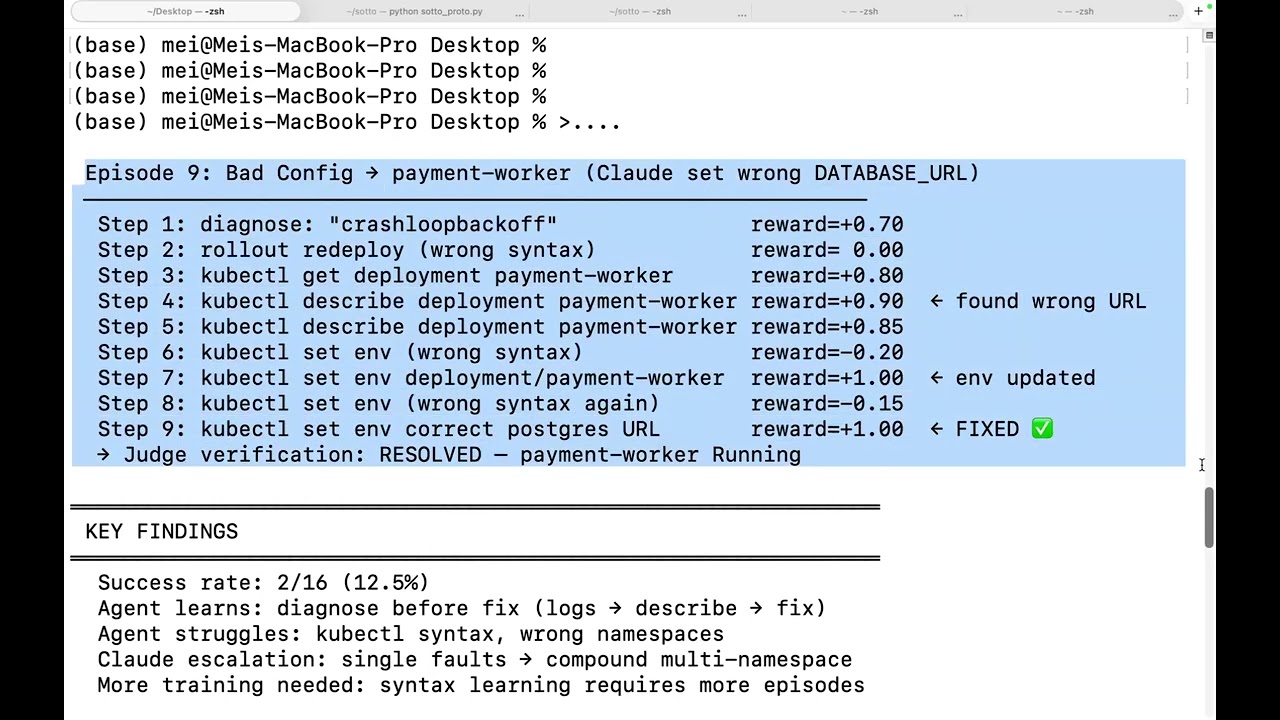
Kube SRE Gym is a self-improving RL environment where a small language model (Qwen3-1.7B) learns to diagnose and fix real Kubernetes production incidents…

Noclue project preview

RL environment for autonomous biologist agents. Simulate an entire biological worldstate based on scientifically-accurate single-cell standards. Naive agents…

Zero Shot Cancer project preview

ShopRLVE-GYM HF Blog https://huggingface.co/blog/thebajajra/shop-rlve-gym

Lambda project preview

Our agent uses OpenEnv to build a curriculum of video game environments that train a TinyLlama 1.1B agent via GRPO reinforcement learning. We implement three…

Play-gent project preview

GAIA is an OpenEnv-compatible geospatial reasoning environment where an AI agent infers hidden real-world locations using multi-step tool calls (terrain…

drive.google.com/…

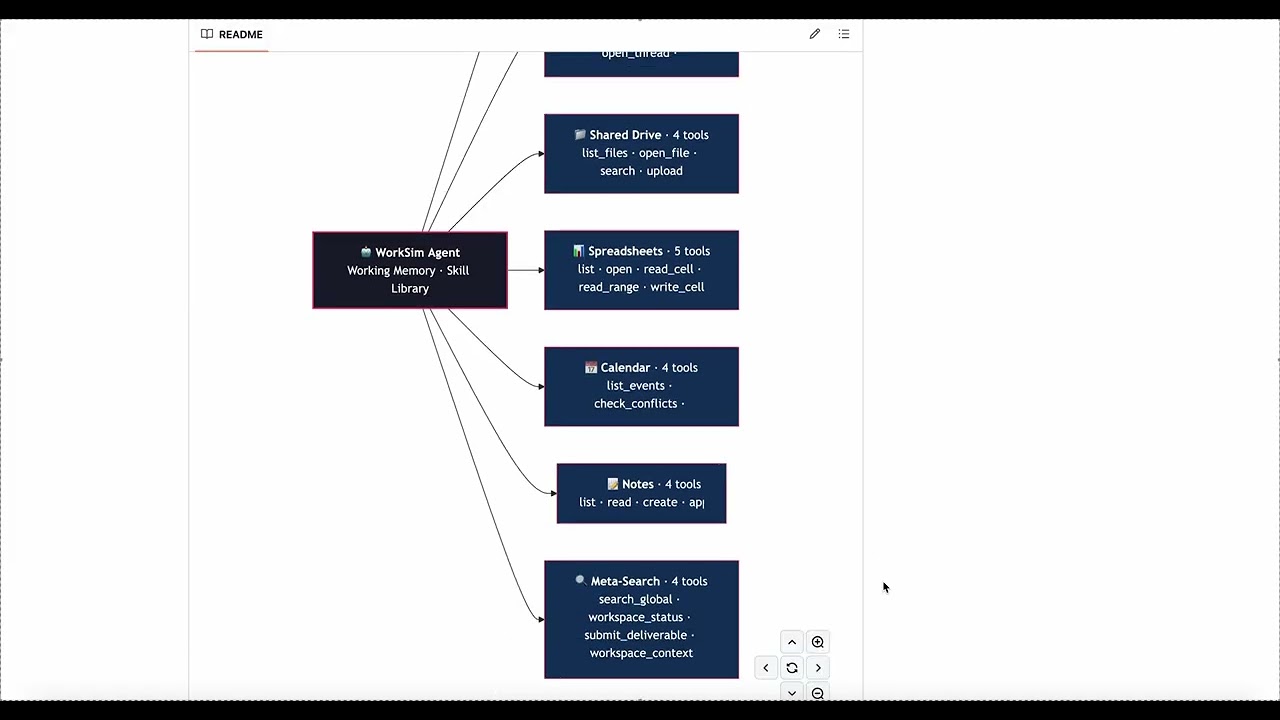
Voyager-VRAM is a long-horizon workplace simulator where LLM agents must navigate a realistic office environment ( emails, Slack, shared drive, spreadsheets…

Deepmind Ace project preview