Skip to Main Content

DriftPA trains LLM agents to be reliable personal executive assistants in a world that breaks without warning. Real AI assistants fail in production because APIs change schema mid-session, tasks expire while the agent deliberates, and wrong bookings or emails can't be undone. DriftPA is an RL environment that simulates exactly these four failure modes simultaneously: schema drift (field names change mid-episode), time pressure (urgent tasks expire), irreversible actions (book/reply/cancel can't be undone), and policy drift (cancellation windows tighten). An untrained agent scores -9.55 mean reward — it uses stale API fields, misses the boss's urgent email, double-books dinner, and triggers cascade failures. A GRPO-trained agent learns to call list_tools() after drift, prioritize by urgency, and commit to irreversible actions only when safe. Optimal score: +22. Untrained mean: -9.55. That 31-point gap is the problem we solve.

Team
raj

More from OpenEnv Hackathon SF

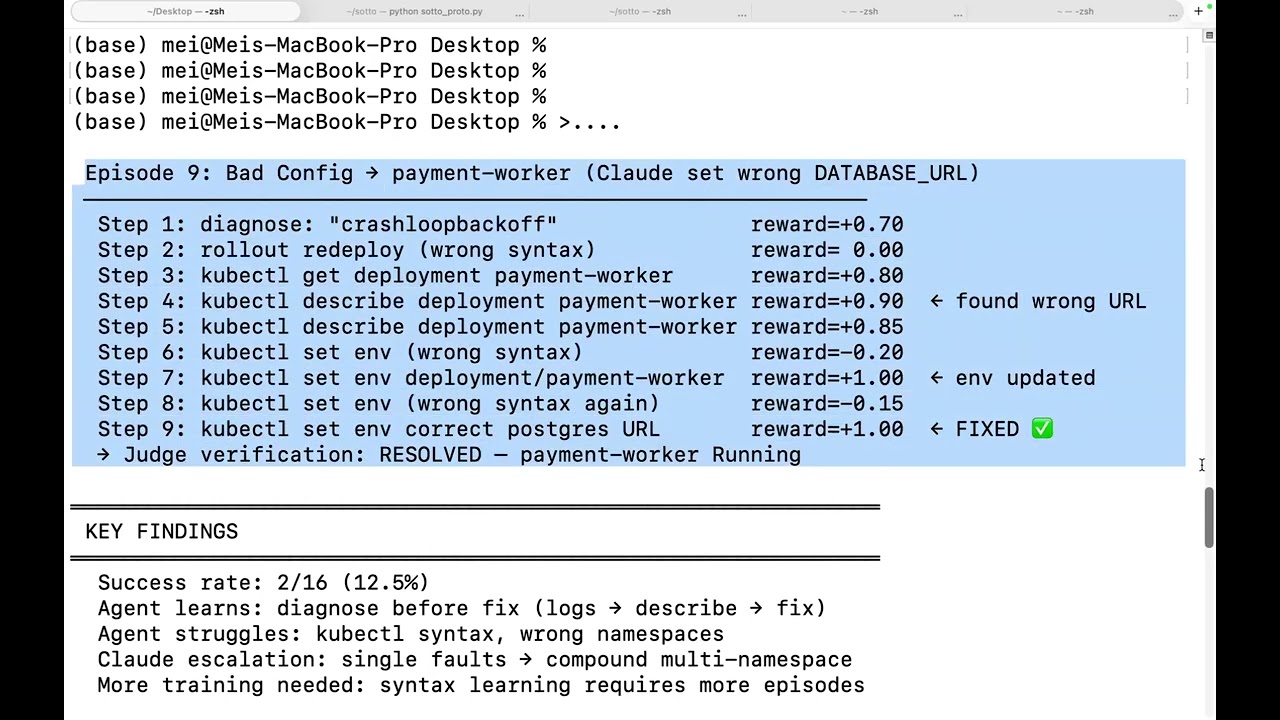
Kube SRE Gym is a self-improving RL environment where a small language model (Qwen3-1.7B) learns to diagnose and fix real Kubernetes production incidents…

Noclue project preview

RL environment for autonomous biologist agents. Simulate an entire biological worldstate based on scientifically-accurate single-cell standards. Naive agents…

Zero Shot Cancer project preview

ShopRLVE-GYM HF Blog https://huggingface.co/blog/thebajajra/shop-rlve-gym

Lambda project preview

Our agent uses OpenEnv to build a curriculum of video game environments that train a TinyLlama 1.1B agent via GRPO reinforcement learning. We implement three…

Play-gent project preview

GAIA is an OpenEnv-compatible geospatial reasoning environment where an AI agent infers hidden real-world locations using multi-step tool calls (terrain…

Voyager-VRAM is a long-horizon workplace simulator where LLM agents must navigate a realistic office environment ( emails, Slack, shared drive, spreadsheets…

Deepmind Ace project preview