Pehovski
Built at The Harness Engineering & Model Wrangling #SFTechWeek Hackathon · Oct 11, 2026 · San Francisco, CA
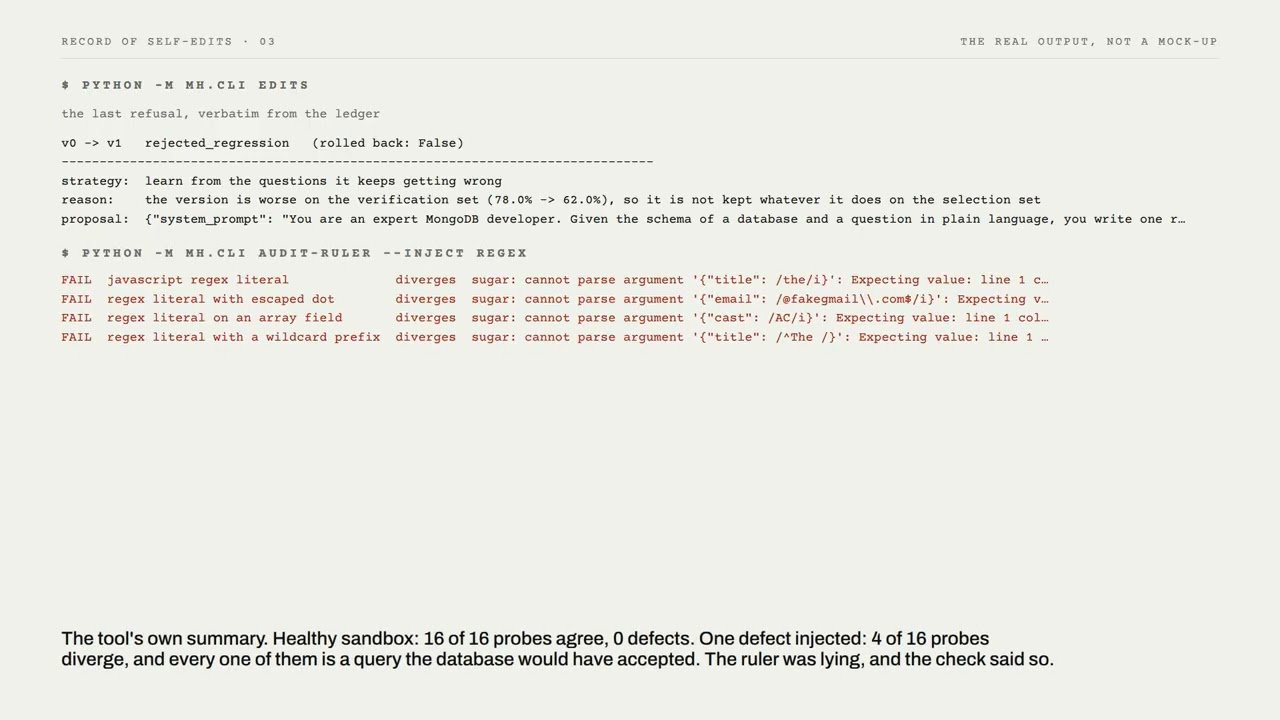
The problem: agents now edit their own prompts, rules and tool access, and almost nothing measures whether an edit made them better. Most self-improving agents declare victory because nobody checks. We built the check. A harness version is a document in MongoDB — prompt, rules, allowed tools, what it remembers — and the agent may only propose a new one. A gate then measures the incumbent and the candidate on the same questions against sample_mflix, scores them on the rows their queries return (never on query text), and promotes a change only if it clears out-of-sample and a paired significance test. In our recorded run it refused all five proposals, each with its arithmetic written to MongoDB: one gained +3.1 points on the selection split and +6.0 on the verification split and was refused as indistinguishable from noise (p=0.375); another lost 16 points out of sample (78% to 62%, p=0.039). The gate is code, not a prompt, so the agent cannot widen its own access: it loses aggregate, collapses, asks for the privilege back, is refused by the envelope, and a human restores it. The harness also audits the instrument it is measured with — the sandbox that used to reject queries MongoDB accepts — and fails loudly when a defect is injected into it. Current version: 75.0% on the selection set, 80.0% on the verification set, 5 refusals, 1 version, nothing promoted. It also writes its own exam for a database it has never seen, keeping only questions whose reference query returns the same answer twice.