Reflexes
Built at The Harness Engineering & Model Wrangling Hackathon · Sep 26, 2026 · New York, NY
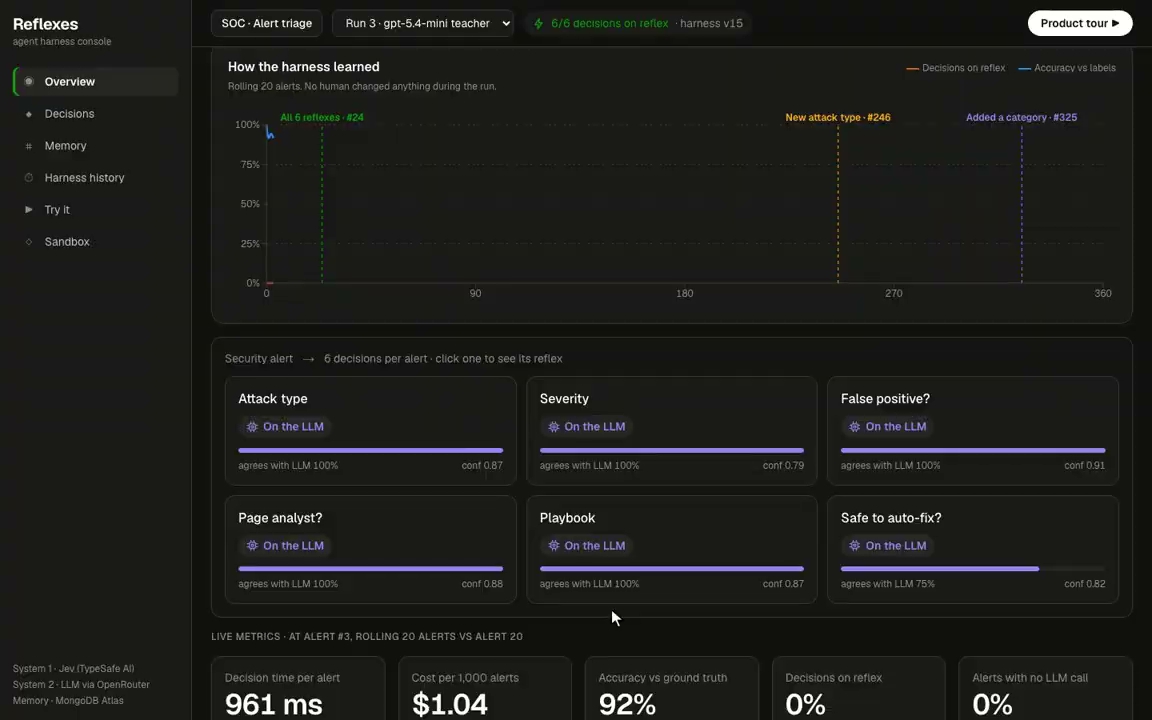
Reflexes: agents that grow reflexes. The problem: AI agents send every small decision (classify, prioritize, route, check policy) to a slow, expensive LLM, forever. Cost grows with every request and latency never improves. What it does: • Shadow: each decision starts on an LLM while Jev, TypeSafe AI's System One model, answers in parallel. Every outcome is stored in MongoDB. • Graduate: once Jev proves reliable on a decision, the harness promotes it to a ~250 ms reflex, with a confidence floor it sets itself. • Recall before acting: Atlas Vector Search checks the alert resembles cases where that reflex has proven itself. Novel, low-confidence or unproven cases go back to the LLM. • Demote and rewrite: audits and confidence collapse demote reflexes. An evolver rewrites the reflex's own question (new categories, context policy), and it relearns. Every change is a versioned harness document in MongoDB. Results (SOC alert triage, 6 decisions per alert, 360 alerts): • 81% of decisions moved off the LLM within ~24 alerts • 2.6× lower cost per alert • 38% of alerts handled with no LLM call, at 257 ms • Accuracy 96% → 92% on held-out labels the engine never sees (a trade we show openly) • When a new campaign of attacks on AI agents appeared, the harness flagged it as unfamiliar, handed it to the LLM, and added a new category to its own taxonomy, with no human in the loop. Live app: https://reflexes-omega.vercel.app (replay the run, paste an alert into Try it, or follow one alert through the full engine in the Sandbox) Tracks: Recursive Harnessing (primary), Long Horizon Engineering.