HIX LAB
Built at Meta Global AI Developer Hackathon · Oct 26, 2026 · Remote
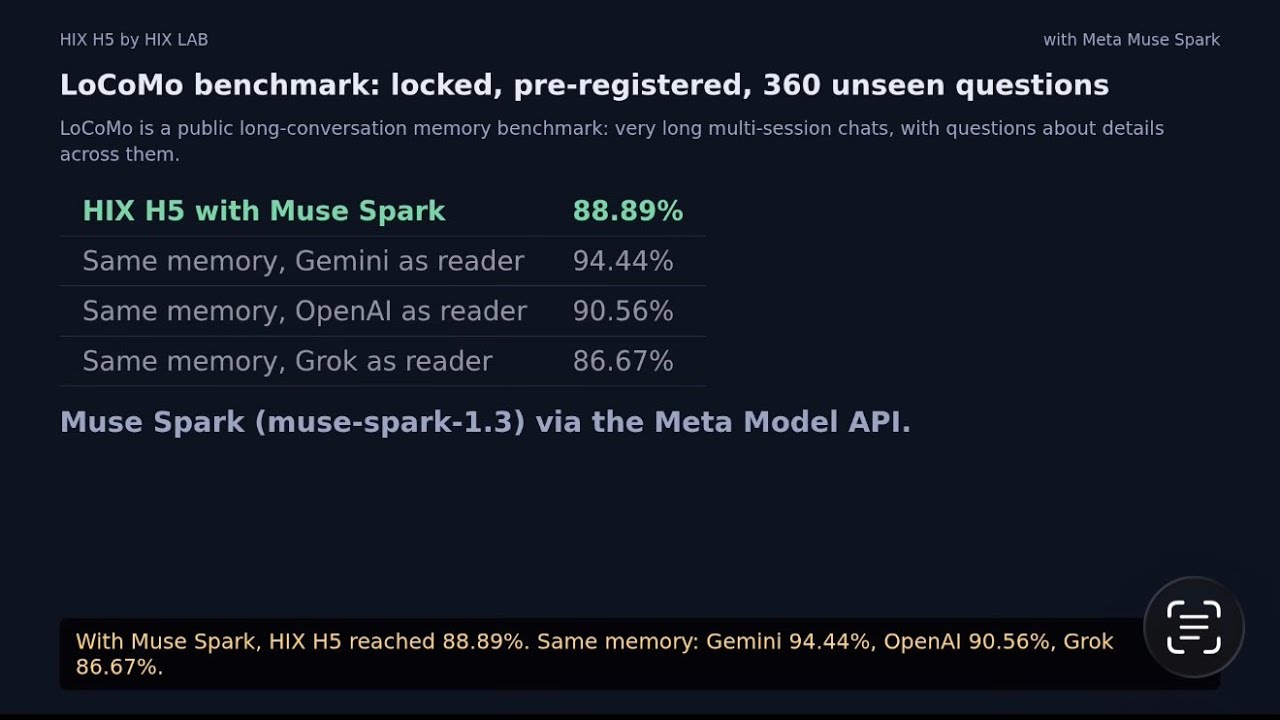
HIX H5 by HIX LAB: Give your AI a memory that remembers your whole conversation. Problem: Meta Muse Spark can already remember: give it the full chat history and it does well on short chats (10 of 10 in our short-chat test). But real histories keep growing. Past the 1M-token context window, full history has to drop older chats, and it still makes up answers to trick questions about things that never happened. Impact: On a 1.48M-token timeline, Muse Spark with full history got 1 of 6 questions right; with HIX H5 it got 3 of 6, at about $0.025 per question instead of about $0.31 (cached) or $1.06 (cold first call). On 64 trick questions asked twice, HIX H5 resisted 45% and 42% of traps, full history 30% and 31%. Solution: HIX H5 by HIX LAB is a long-term memory add-on for any AI reader, here Meta Muse Spark (muse-spark-1.3). It keeps answers right when a history outgrows the context window, and it pushes back on questions that pin something on the wrong person. It is available only through HIX LAB (hixlab.si), where H5 is listed at $200/month. Lighter versions, H2 and H3, reach everyday users as the ME•ME chat plug-in (H2 at $10/month, H3 at $20/month), Powered by Hix Lab. Evidence: Item 1 (LongMemEval, Oct 2026): On LongMemEval (Oct 2026, official GPT-4o judge, independently verified), HIX + adapter lifted QA accuracy from 49.6% to 53.8% and session recall@10 from 76.0% to 83.6%. System measured: HIX + benchmark adapter (not raw HIX). QA cases: exposed regression cases. Item 2 (LoCoMo locked, pre-registered run, Oct 28, 2026, inside the hackathon window): n=360 unseen questions, mem0-style judge on gpt-5.4-mini. System measured: H5 v2. With Meta Muse Spark (muse-spark-1.3) as the reader: no memory 0/360, base memory 317/360 (88.06%), H5 v2 320/360 (88.89%), 3 gains and 0 losses. Other readers with H5 v2: Gemini 340/360 (94.44%), OpenAI 326/360 (90.56%), Grok 312/360 (tie with base). Per-question answers, the public pre-registration and hash files are in the repo under results/ (answers/, PREREG-locomo.md, LOCK.sha256); scores recompute with scoring/rescore.py. Evidence repo: https://github.com/jjsingh88/hix-h5-hackathon Item 3 (Nov 1, 2026, exploratory, not pre-registered, reader Muse Spark muse-spark-1.3, same gpt-5.4-mini judge): (a) short chat (conv-48, about 22k tokens, 10 questions): full chat history 10/10, HIX H5 8/10, full history plus H5 9/10, no memory 0/10. (b) long timeline (about 1.48M tokens; full history kept 1,106 of 1,966 sessions to fit): full history 1/6, HIX H5 3/6, no memory 0/6; cost per question about $0.31 average cached full history ($1.06 cold first call) vs about $0.025 H5; H5 input about 12.6k tokens per question vs about 833k for full history; latency about 43 s average (13 to 93 s) full history vs about 11 s H5. (c) 64 adversarial LoCoMo questions, each asked twice: traps resisted, full history 19/64 and 20/64, HIX H5 29/64 and 27/64. Run files: results/nov1/ in the same repo. Demo: The video (2:40) is an honest comparison: Muse Spark answering a short chat correctly from full history, then the same kind of question on a 1.48M-token history where full history drops the oldest 860 chats and answers wrong while HIX H5 answers right, a trick question full history invents an answer to, and the locked LoCoMo results card. Chat answers are real Muse Spark answers fetched from our live endpoint before recording, disclosed on screen. Disclosure of prior work: HIX is an ongoing HIX LAB research line that predates this hackathon (including the LongMemEval measurement in Item 1). Built during the hackathon window (Oct 27 – Nov 4, 2026): the H5 v2 locked LoCoMo runs and reader addendum (Oct 28), the no-memory baselines, the Nov 1 exploratory runs, the hosted demo API and thin demo client, the demo video, and this evidence repository. Detail: docs/BUILD-WINDOW.md in the repo. Roadmap: HIX H6 is in development now and is expected to be completed Friday, November 6, 2026 — after this hackathon's submission deadline — and in our internal testing it scores higher than the H5 version submitted here. H6 is not part of this entry; it is the next step after H5. Testing the demo: Hosted H5 demo API (reader Meta Muse Spark): POST https://k34tt7bjdcvzthd3evip6x6h3q0irxgu.lambda-url.us-east-1.on.aws/v1/ask — send the judge code in the X-Judge-Code header, or run client/demo.py from the repo with H5_JUDGE_CODE set. The judge code is shared for the judging panel: any judge may use it, on their own schedule, from Wednesday, November 4, 2026 through Monday, November 9, 2026, 11:59 PM ET, when it expires automatically. Judge code: H5J-CjbbtmV7m-FSH7O2iByvTeKp