Tokenmaxxing
Built at Meta Global AI Developer Hackathon · Oct 26, 2026 · Remote
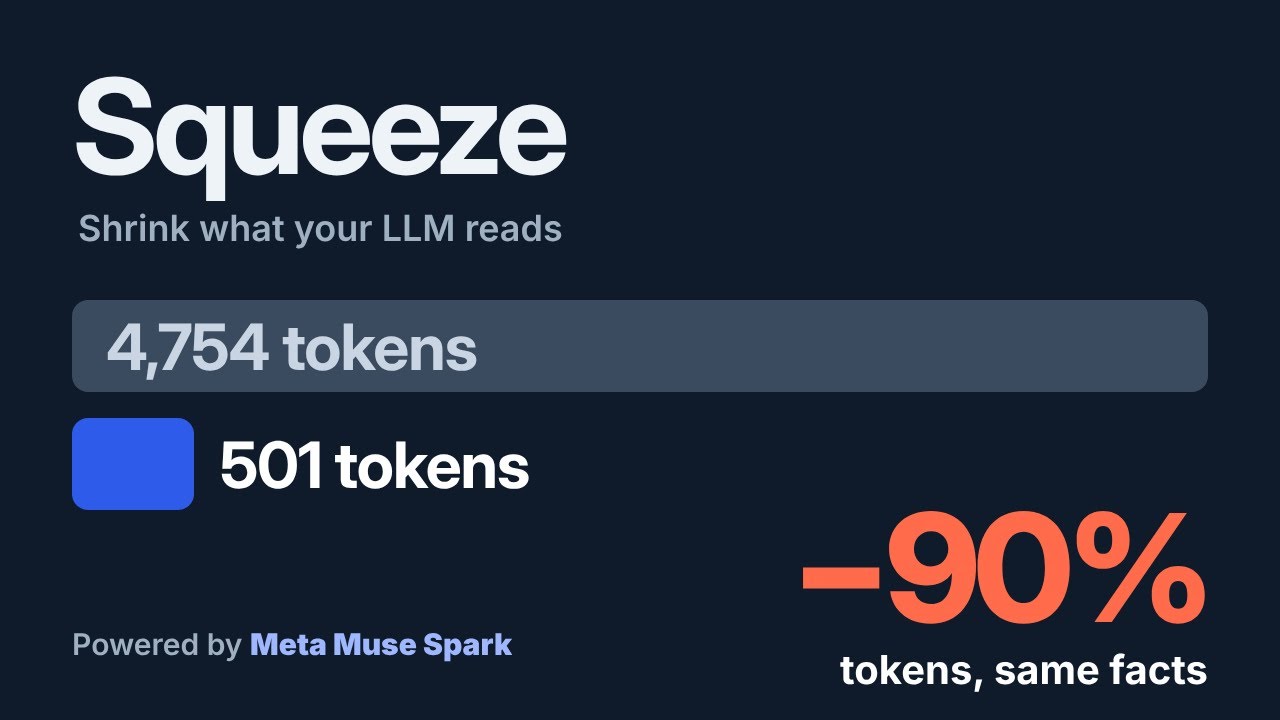
Squeeze: shrink what your LLM reads, keep what it needs Every deck, PDF, web page or API response you send to an LLM carries thousands of tokens of waste: slide images, logos, the same footer on every page, HTML markup, null fields, tracking links. You pay for all of it on every call, and agents pay again on every turn. Squeeze turns those files into compact Markdown and counts exactly what it saved. Plain code does the free work first: it extracts text, tables, notes and native charts, removes repeated footers, cleans HTML and prunes JSON. Then Meta's Muse Spark judges every image that's big enough to matter. It turns charts into data tables, transcribes scanned pages and drops decorative pictures. An optional fact check, also run by Muse Spark, asks questions of the original and answers them from the compressed text. On live runs with Muse Spark, Squeeze cut a slide deck by 89.5%, a PDF report by 95.4% and a web page by 94.0%, and every fact check scored 8 out of 8. Squeeze also reports what Muse Spark itself spent. On the PDF, the image step paid for itself on the first use; on the deck, by the second. It runs as a web app, a CLI (squeeze demo/* --out out) and a Python library. It works with the Meta Model API or with Muse Spark Open on Baseten or Modal. Built during the hackathon. Open source under MIT.