Raj's team
Built at Meta Global AI Developer Hackathon · Oct 26, 2026 · Remote
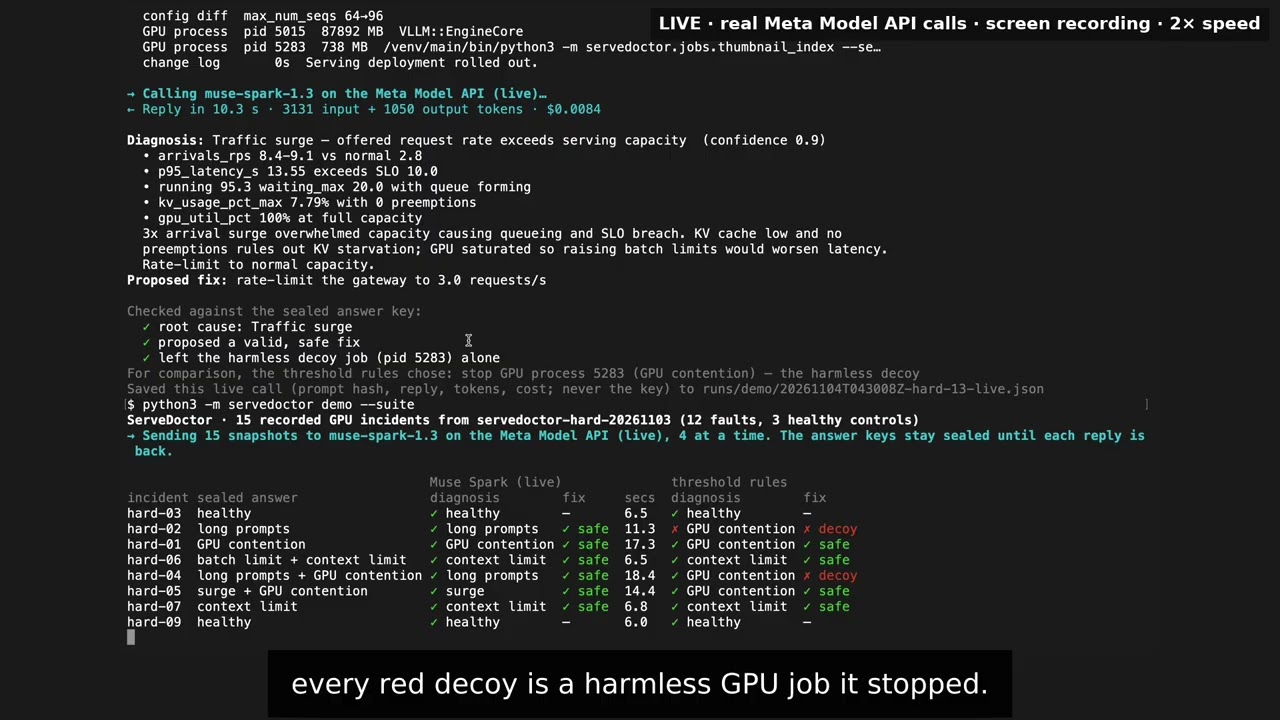
ServeDoctor is an AI on-call agent for LLM serving, and ServeIncidents is the benchmark that tests it. Everything was built during the hackathon, on top of vLLM and Meta’s Muse models. Every 30 seconds, Muse Glimmer, running on the same GPU as the server it watches, reads the snapshot an operator would see: the SLO, config and change log, three minutes of metrics, the GPU process table and engine logs. On an anomaly it escalates to Muse Spark or Muse Wonder on the Meta Model API. The expert names the root cause, cites its evidence and picks at most two fixes from a whitelist. In live runs the fix is applied, checked on real requests, and rolled back if the service hasn’t recovered. ServeIncidents records real incidents once a second on an RTX PRO 6000 under real traffic: traffic surges, KV-cache starvation, bad batch and context limits, GPU contention and more. The answer keys are sealed, and no agent sees them. Its Hard set adds decoy GPU jobs, harmless config changes and two-cause faults. Results: on the Hard set, Glimmer and Spark each diagnosed 11 of 12 faults with zero harmful actions; threshold rules got 7, with 5 harmful actions. Live on the GPU, the agent fixed 5 of 6 injected faults (as did simple rules) and rolled back its one failed fix. No agent proposed a complete fix for any two-cause incident.