dptel05
Built at Meta Global AI Developer Hackathon · Oct 26, 2026 · Remote
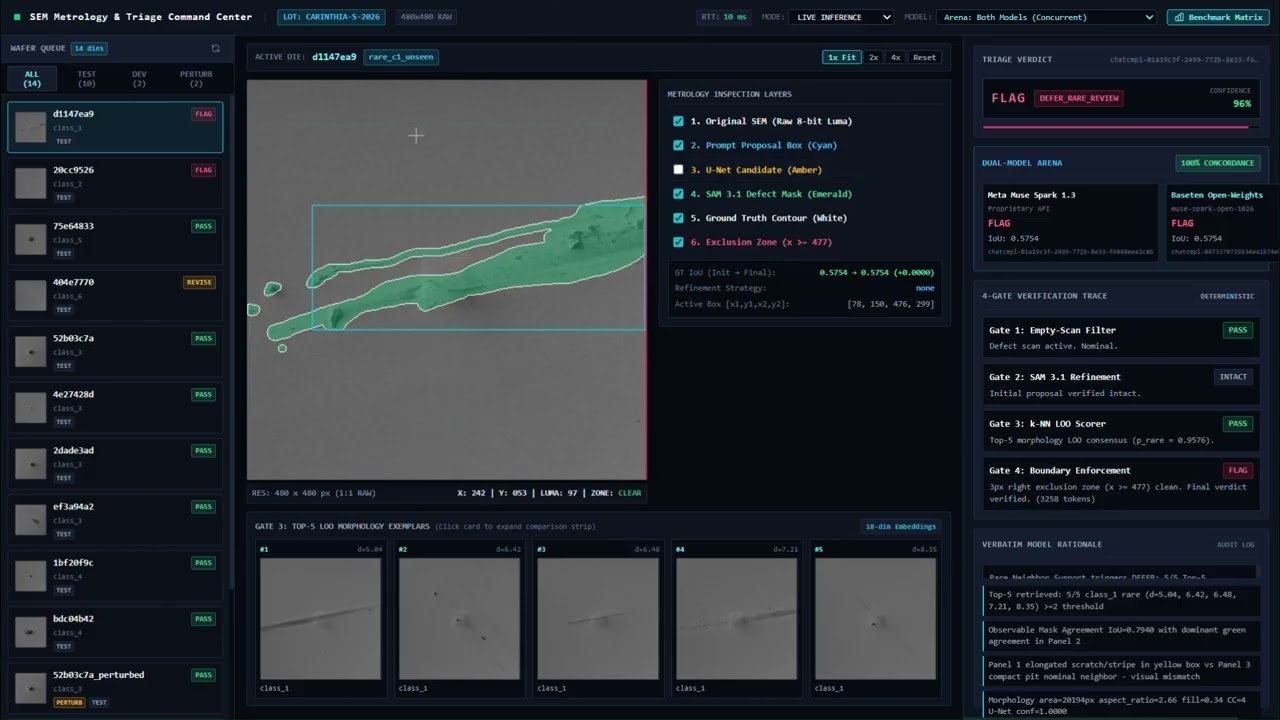
WaferGuard is a closed-loop, verifiable multimodal triage agent for semiconductor scanning electron microscope (SEM) wafer inspection built on the public Carinthia-S dataset (4,591 SEM image-mask pairs across 6 classes, DOI: 10.5281/zenodo.16895427). Standard fab defect detectors fail in three ways: they waste compute on empty scans caused by SEM electron-beam misalignment (Class 6), fail on text-prompted foundation segmentation due to the grayscale microscopy domain gap, and saturate at >99% confidence on rare out-of-distribution defect morphologies (1.5% base rate), silently passing yield-killing excursions. WaferGuard solves this with a 4-gate verifiable agent architecture: Gate 1 (Deterministic Empty-Scan Filter): Strips the 3px right-hand SEM border artifact (x >= 477) and filters components <16px, routing empty misaligned scans (Class 6) to NO_DEFECT_REIMAGE with 100% specificity (24/24 across val and test) at $0 API cost. Gate 2 (SAM 3.1 Wire-Format Segmentation & Closed-Loop Self-Correction): Pairs a local ResNet-18 U-Net proposer (0.887 nominal median IoU) with Meta's sam-3.1 via box and point prompts (0.870 median IoU under ±15% symmetric box jitter). A deterministic verifier monitors U-Net/SAM IoU agreement and box fill ratio: high-agreement masks (>=0.68 IoU) are locked via a hard monotonicity guard, while corrupted or leaky masks trigger autonomous re-prompting (recovering +0.801 ground-truth IoU on perturbed proposals). Gate 3 (18-Dimensional Leave-One-Out Retrieval Bank): Extracts 18 morphological, histogram, component-count, and discordance features to retrieve the Top-5 nearest neighbors across 3,454 training wafers and assembles a 480x1440 3-panel visual comparison strip (Raw SEM + Box | U-Net vs SAM 3.1 Agreement Overlay | #1 Nominal Exemplar). Gate 4 (Dual-Model Multimodal Triage Arena): Evaluates muse-spark-1.3 (Meta Model API) head-to-head against open-weights meta-models/muse-spark-open-1026 (on Baseten), achieving 82.4% rare recall at 0.0% nominal false alarms on our 34-sample calibration benchmark (F1 = 0.903, outperforming U-Net confidence, mask discordance, and non-LLM k-NN baselines), passing all pre-registered C1/C2/C3 checks on our frozen 10-image test suite, and demonstrating 100% decision parity between closed and open weights.