Builders Nepal
Built at Meta Global AI Developer Hackathon · Oct 26, 2026 · Remote
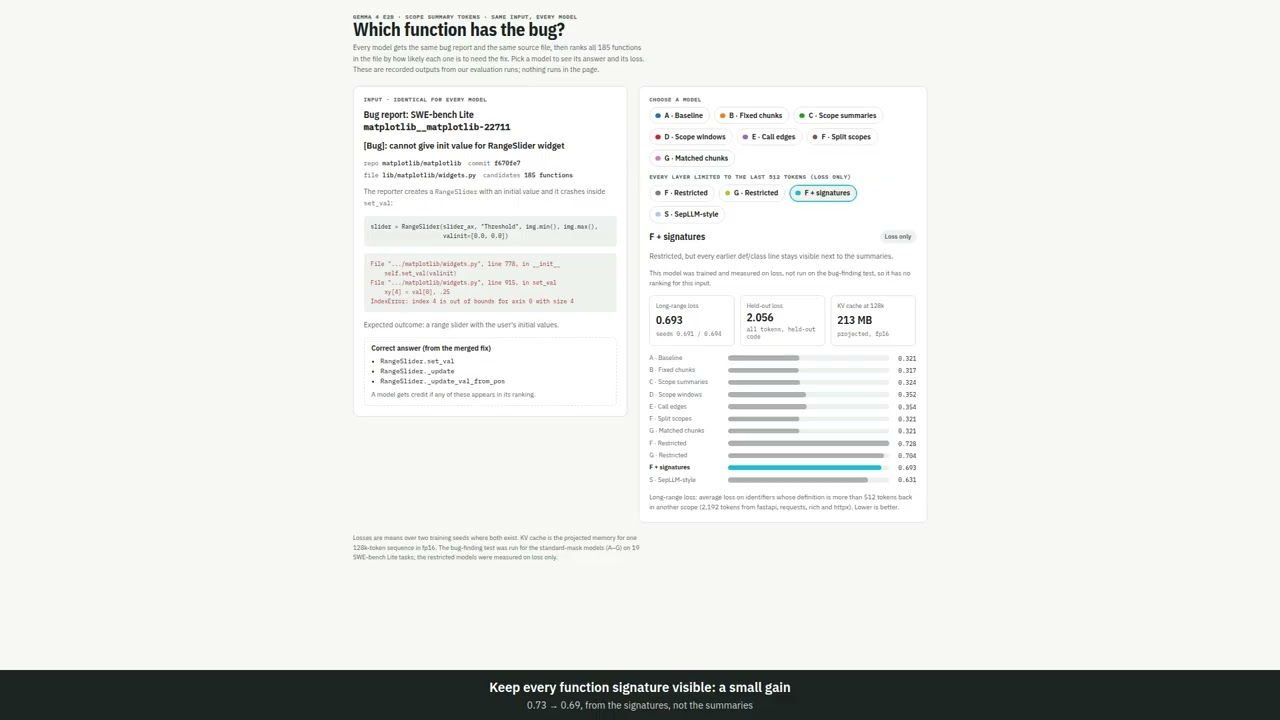
Small code models forget distant code, and keeping every token in memory is expensive. scopesum asks a simple question: can a learned summary token at the end of every function and class let Gemma 4 reach far-away code cheaply? We retrofitted summary tokens into Gemma 4 E2B without changing its vocabulary, using custom attention masks and LoRA fine-tuning, backed by 123 tests. We then ran a controlled study: ten model variants, matched for token count and memory, two training seeds each, 20 training runs in total, all on free Kaggle GPUs. The results were clear. The model ignores the summaries, because Gemma's global layers already read distant code directly. When we removed that shortcut, long-range accuracy dropped sharply and the summaries still did not bring it back. Keeping real tokens worked better: function signatures helped a little, and keeping separator tokens, as SepLLM does, worked best, at a higher memory cost. Our wins: a working retrofit, a precise explanation of why summaries fail in hybrid models, a memory design that cuts the cache 34 times at 128k tokens, and summaries that describe functions far better than fixed chunks. The demo shows every model's answer to the same real bug report.