DevDiva
Built at Meta Global AI Developer Hackathon · Oct 26, 2026 · Remote
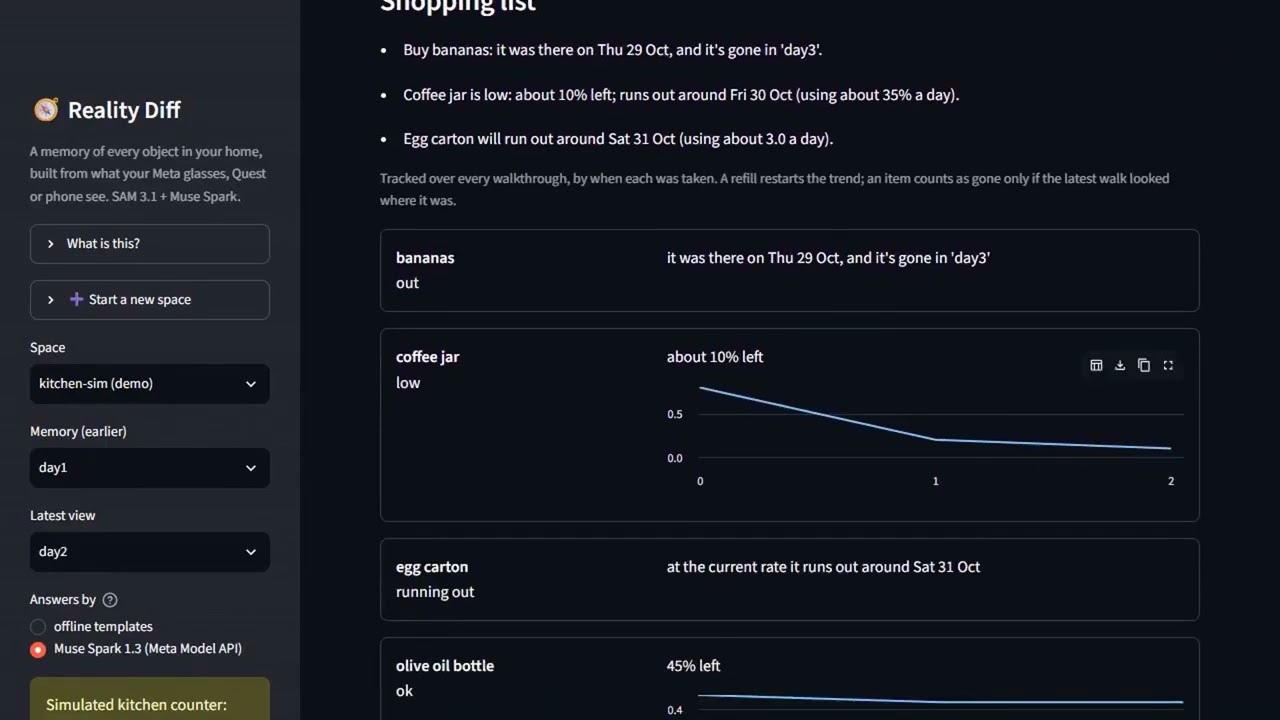
Vision AI forgets the moment the image is gone. Assistants in glasses, headsets and robots need a memory of the places they work in. Reality Diff builds one: a persistent 3D map of every object in a home. Each object keeps its own anchor (a UUID, a 3D point, a history) through moves, hiding and coming back. Muse Spark lists what is there, SAM 3.1 segments and tracks every object, and Spark names each one from its crop. Device camera poses, printed markers or the first photo of a spot place each look in a fixed frame. Triangulation or Meta’s DINOv2 depth model lifts every object to 3D, and every space joins one searchable house map. Each new look reports what moved, was removed or added, and says “uncertain” when it could not see a spot. New things are put to the user to name, once. Over days it keeps a shopping list with run-out dates. Questions, typed or spoken through Muse Voice Transcribe, are answered by Spark calling tools over the memory, and every cited object is checked. On a fresh simulated bench (real model calls) it found 6 of 9 staged changes with 2 false alarms, F1 0.71 vs 0.67 for Spark on two photos. With more moves, F1 was 0.69 vs 0.44.