DriveIQ
Built at Meta Global AI Developer Hackathon · Oct 26, 2026 · Remote
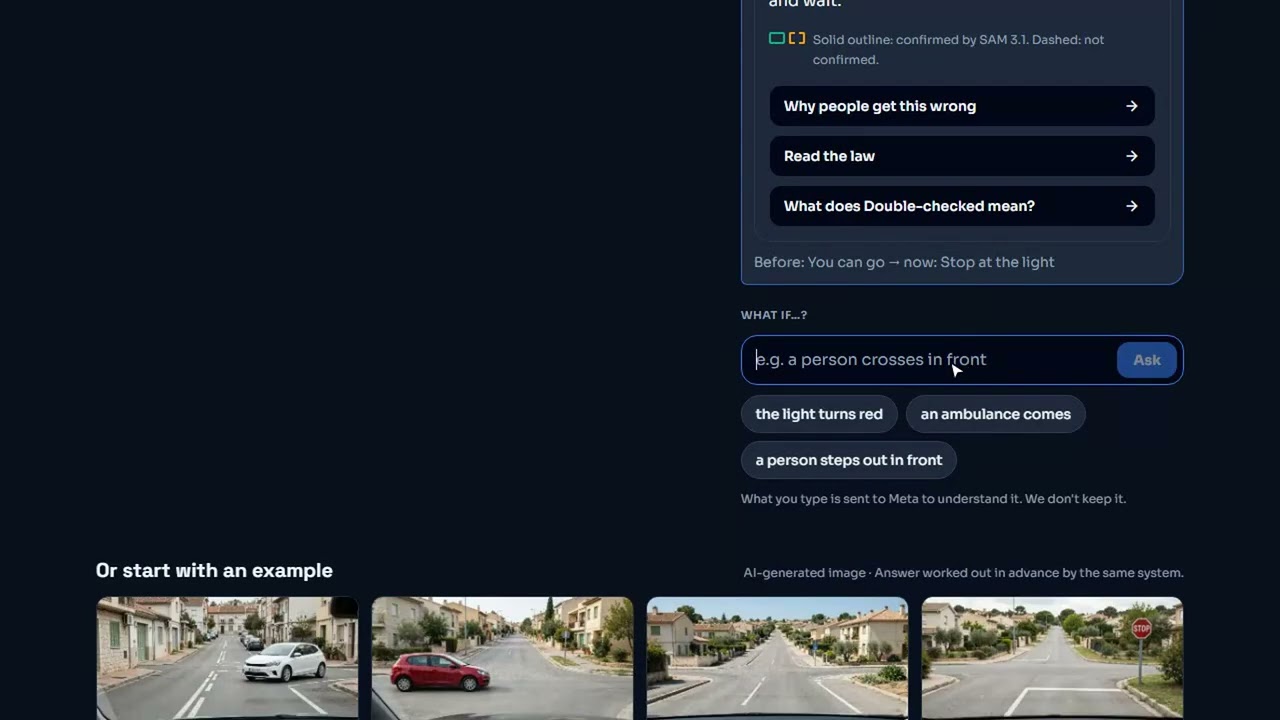
RoadSense tells a learner driver who goes first at a Spanish junction, from one photo, and checks the answer against the law. Right of way is where driving-theory answers turn into guesses. Real junctions mix signs, traffic lights, road markings, pedestrians and emergency vehicles, and the rule depends on all of them. With RoadSense, a learner photographs a junction from the driver's seat, or picks an example, and gets: - what they must do: go, give way, stop, let a pedestrian or an ambulance through, or slow down; - the exact article of Spain's traffic rules, quoted word for word from the official BOE; - outlines on the photo around the signs, lights and road users the answer depends on. RoadSense checks itself. Muse Spark 1.3 reads the photo into structured facts, and a deterministic rule engine decides from those facts alone. Muse Spark then decides again, independently, and explains, citing only the BOE excerpts it was given. SAM 3.1 takes a second look and confirms each object the answer depends on. The answer is marked "Double-checked" only when all three agree. Otherwise RoadSense says it is not sure, shows that its two checks disagree, or says the photo is outside its scope. It would rather say "not sure" than guess. Learners can then ask "what if…?" in their own words, in Spanish, English, French or Arabic: "what if a person steps out in front?", "¿y si el semáforo se pone en rojo?". Muse Spark maps the question onto a change RoadSense can test. Muse Image 1.0 edits the photo, and RoadSense reads the edited photo again and checks that the change really happened. Only then does it show how the answer changes, and which article says so. If it can't test something, it says so and suggests what it can test. RoadSense is live at driveiq.es/roadsense, inside DriveIQ, a theory-exam app for the Spanish driving test (permiso B) in four languages. In the four weeks before the hackathon, DriveIQ had about 2,000 visits from Google and 114 new accounts. Evaluation, on 33 scenes generated with Muse Image: - 17 of 24 answerable scenes were answered right and Double-checked; - no wrong answer was marked Double-checked; - all 5 scenes where the honest answer is "not sure" came back not sure; - all 4 out-of-scope photos were caught; - all 59 typed what-ifs, in four languages, were read correctly. These numbers are in-sample: the prompts were tuned on these scenes. The full report, every recorded model response and a replay that needs no API key are in the repo.