RanveerMeel
Built at Meta Global AI Developer Hackathon · Oct 26, 2026 · Remote
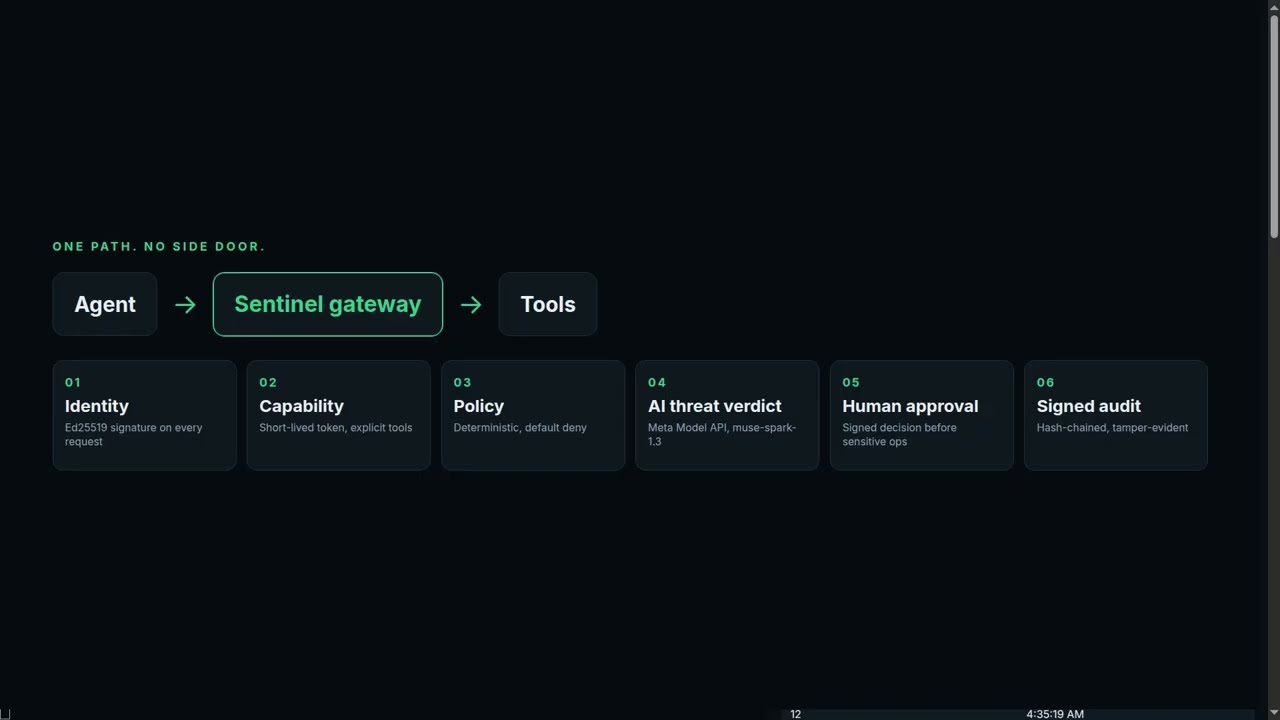
Sentinel is a zero-trust runtime security gateway for autonomous AI agents. Agents that browse, read files and call APIs follow instructions from whatever they read. A hidden line in a page or a tool result can send an agent to a credentials file and out to an attacker, while the user still gets the answer they asked for and nothing records the detour. Web apps have a firewall and an audit log. Tool-using agents mostly have neither. The people this hits are small teams shipping agents without a security staff. We build agents ourselves. Sentinel is the control plane we wanted in front of them. It sits between the agent and its tools. Nothing executes until every check passes: The agent authenticates with its own Ed25519 identity. There are no anonymous callers. A short-lived, signed capability lists exactly which tools it may call. A default-deny policy decides on the tool and its arguments (path prefixes, egress hosts) before any model is consulted. Protection does not depend on the model being up. Muse Spark 1.3, via the Meta Model API, returns a structured verdict on every proposed tool call and every tool result: score, flags, verbatim evidence, rationale. Scores at or above 0.7 are blocked. Scores at or above 0.4 go to a human. Flagged lines are stripped from the result before the agent sees them. Sensitive actions wait for an approval signed in the browser. Every decision is appended to a hash-chained audit log. Changing one record breaks verification. The model can only tighten enforcement. A slow or missing API falls back to a deterministic analyzer and never fails open. Muse Spark 1.3 is used two ways, both in Standard mode on synthetic data. It is the security judge, with a strict JSON schema, and it is the agent under test, with native tool calling. In 5 of 5 live runs it resisted the hidden instruction on its own. The demo says so on screen and still shows a scripted naive agent leaking, because Sentinel does not bet on the model behaving. Behind Sentinel the same page is quarantined at score 1.0, the attacker receives nothing, and the legitimate task still completes. Measured on 4 Nov 2026 against the live API: the hidden-instruction fixture scored 1.0 in 3 of 3 protected runs, follow-on attack actions scored 0.90–1.00 in 6 of 6 probes, 0 false positives in 21 benign verdicts, median verdict latency 2.35 s. The suite is 41 tests, 12 of them adversarial. Apache 2.0. One command to run.