Flatline
Built at Meta Global AI Developer Hackathon · Oct 26, 2026 · Remote
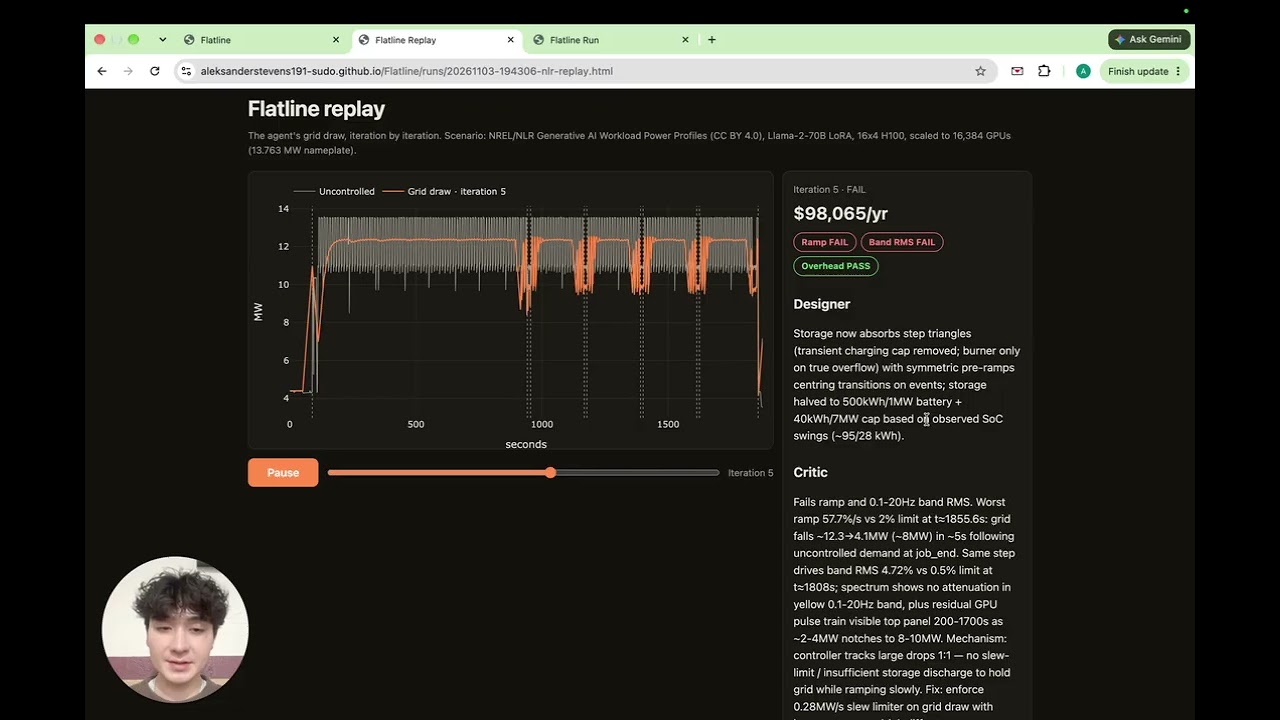
When thousands of GPUs train an AI model together, they all speed up and slow down at the same moment. On a measured Llama-2-70B training run from NREL, scaled to a 16,000-GPU site, that is a 2.7 MW square wave every ten seconds and 8 MW jumps when a job starts or stops, right in the frequency range that can shake power plants. Utilities now require new AI campuses to prove they can control this, and today that takes weeks of specialist engineering per site. Flatline is an agent that does that engineering. You give it the utility's requirements in plain English and a measured power trace. Muse Spark turns the requirements into exact limits, Muse Wonder writes a controller in Python and sizes the battery and supercapacitor it needs, a deterministic simulator tests it on the real data, and Muse Spark looks at the resulting plots and explains what failed. Wonder rewrites until the design passes and stops getting cheaper. On the live run, the agent's eighth design passed every limit at $86k a year. The standard fix, a fixed GPU power floor, wastes 14% of all energy ($869k a year), and the best of 500 tuned classical designs needs a battery eight times larger ($291k a year). On a stricter spec and on a second real workload it redesigned from scratch and passed again. The whole run costs under a dollar of API credit.