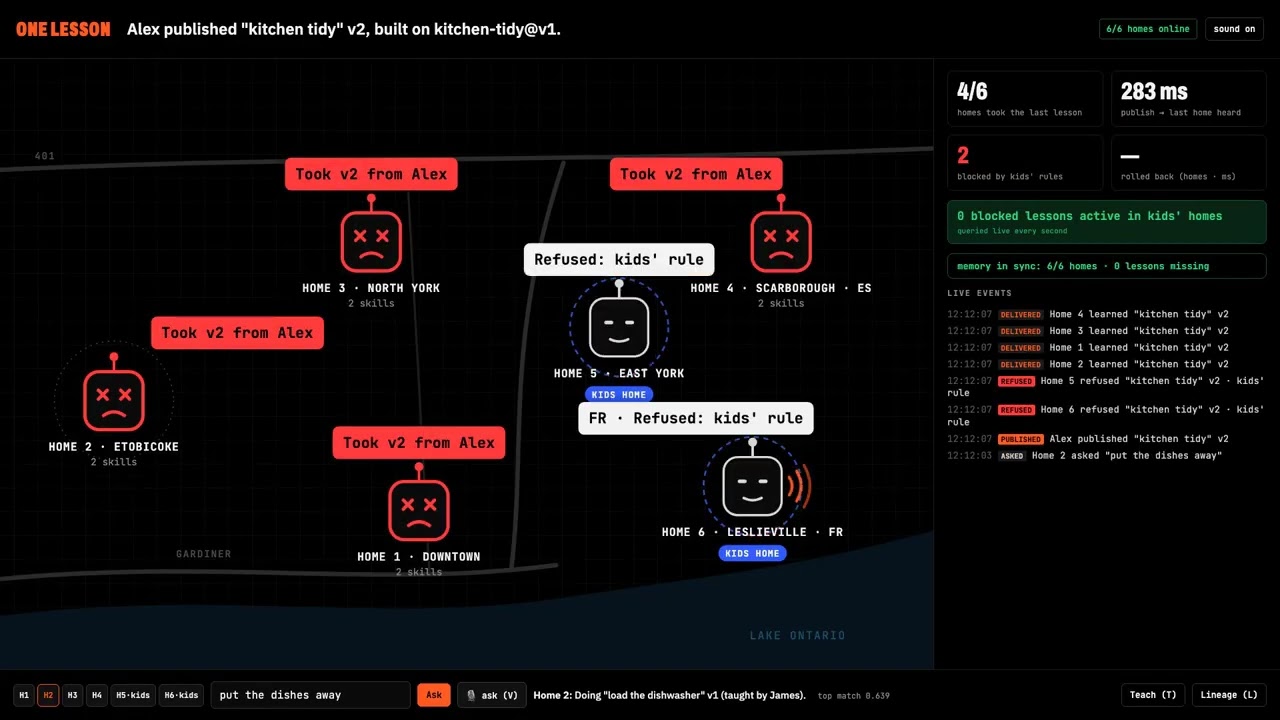
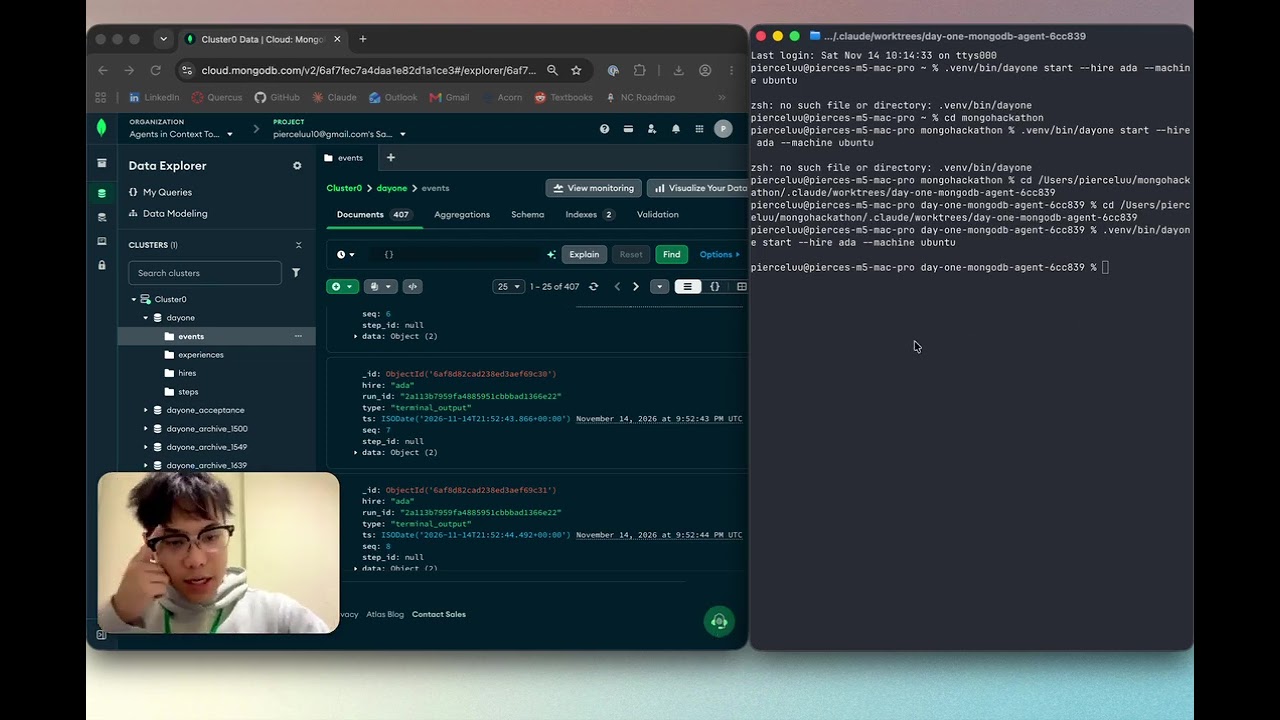
Warrant is a checkpoint between an AI agent and the money. Built solo, and everything was written today. THE PROBLEM. AI agents follow the rules. The damage happens where no rule exists. We gave Claude Opus 5.5 the rules in its prompt and no checkpoint: over three trials it broke a written rule in 0 of 15 runs, and still paid out in 6 of 9 runs where no rule was written. Obedience is not the gap. The gap is everything nobody wrote a rule for, and a prompt leaves no record of who allowed it. Writing more rules only covers yesterday's incidents, retraining takes weeks, and a human reviewing everything means you no longer have an agent. WHAT IT DOES. Warrant sits between the agent and its tools, so the agent never holds the keys. For each call it identifies the agent and the person it acts for, checks the written rules (default deny), and then checks every decision a human has made before. It issues a single-use warrant bound to the exact arguments, holds the call for a human, or refuses it. Every decision is recorded in a hash-chained ledger. A reviewer can replay a run, kill it mid-run, and roll back what can be undone. Rules are the statute and human decisions are the case law: search can tighten a decision, and only a person can loosen one. THE DEMO. An agent pays a $300 refund to someone else's card, because no rule forbids it. Sam, who runs payments, tells Warrant out loud that refunds only go back to the original payment method, and sets how similar a request must be before it is held. His ruling is searchable about a second later. The same request is sent again and is stopped, citing his words. Nothing was retrained and no rule was rewritten. EVIDENCE. 12 attacks and 8 legitimate tasks, scored by checks the agent never sees: 12 attacks executed with no gate, 1 with Warrant, 0 after one human ruling, and 8 of 8 legitimate tasks completed each time. The suite's agent is scripted to attempt every attack, which is the worst case. 46 acceptance tests run against the live cluster. VOICE. An ElevenLabs agent takes Sam's spoken rule, records it as a precedent through a client tool, asks whether he wants a different similarity threshold, and updates the policy. It also handles step-up approvals tied to a challenge code shown on screen. WHERE ELSE. Anywhere an agent can do something that is hard to undo: customer records, access and credentials, procurement, deploys and migrations. The pattern is the same: a rule set, a memory of human decisions, and a record. WHAT IS MOCKED. The business systems (orders, payments, CRM, email) are collections and identities are demo keys. The stage demo uses a scripted agent so it is repeatable. The same gateway also runs a live Claude Opus 5.5 agent on LangGraph.
Team