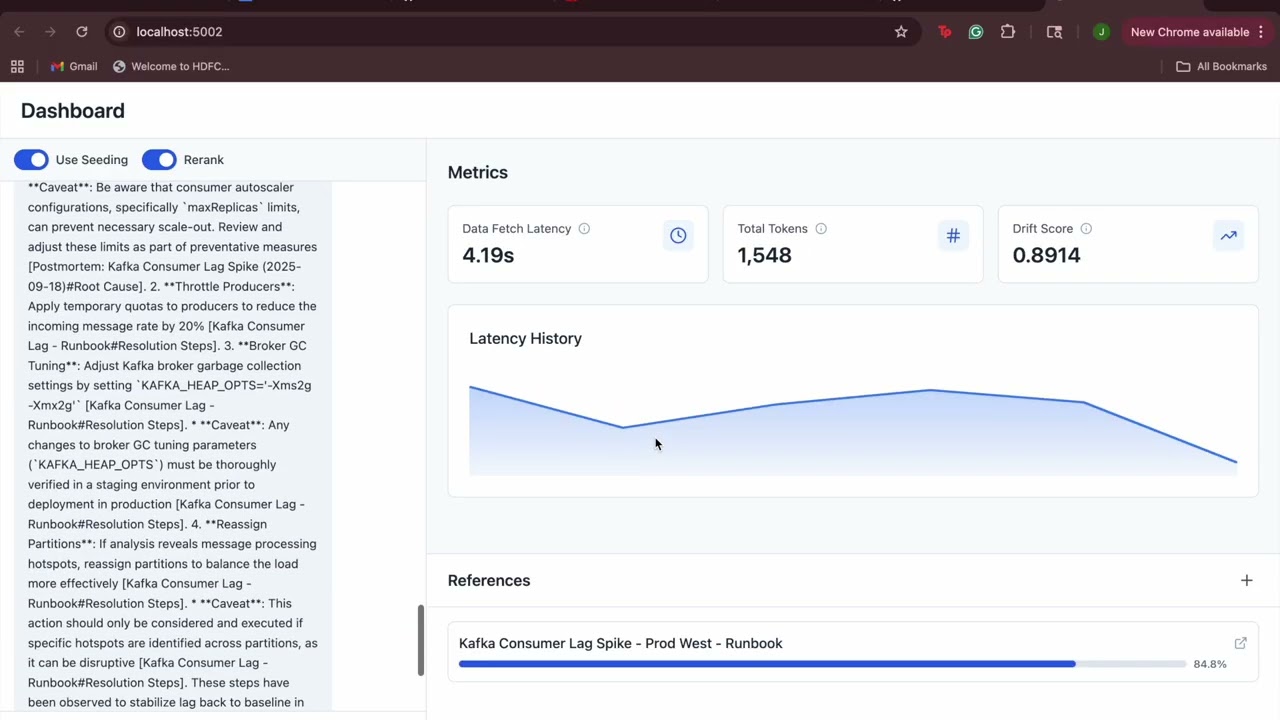
We've built a seeded RAG system that uses a lightweight knowledge cache to minimize redundant retriever calls. The LLM first tries to answer a query using cached context from previous questions; if it determines that the information is insufficient, it triggers the retriever to fetch new data and updates the cache. This approach allows semantically related or follow-up questions to be answered instantly from the existing cache, reducing latency, cost, and retrieval frequency while keeping responses contextually consistent across a conversation.
More from Agentic Memory & Context Engineering Hackathon
Our tool helps patients with dementia by surfacing real-time context on the person they are talking to.
- ContextScope Eval is an open-source evaluation and observability framework for agent-to-agent context sharing. It measures how effectively autonomous agents…
Ever struggled to find that perfect article you read last week? That tutorial video you can't quite remember the name of? WebBrain transforms your browser…

The Airbnb Travel Booking Assistant is a personalized AI concierge that curates stays based on each traveler’s unique style and past experiences. Instead of…

KitchenPal is an AI-powered cooking assistant that leverages multiple independent Retrieval-Augmented Generation (RAG) workflows to provide personalized…
Incident Copilot is a seeded-RAG assistant for on-call engineers. It uses MongoDB Atlas Vector Search, Voyage embeddings with reranking, and Google Gemini to…