Shadow
Built at Meta Global AI Developer Hackathon · Oct 26, 2026 · Remote
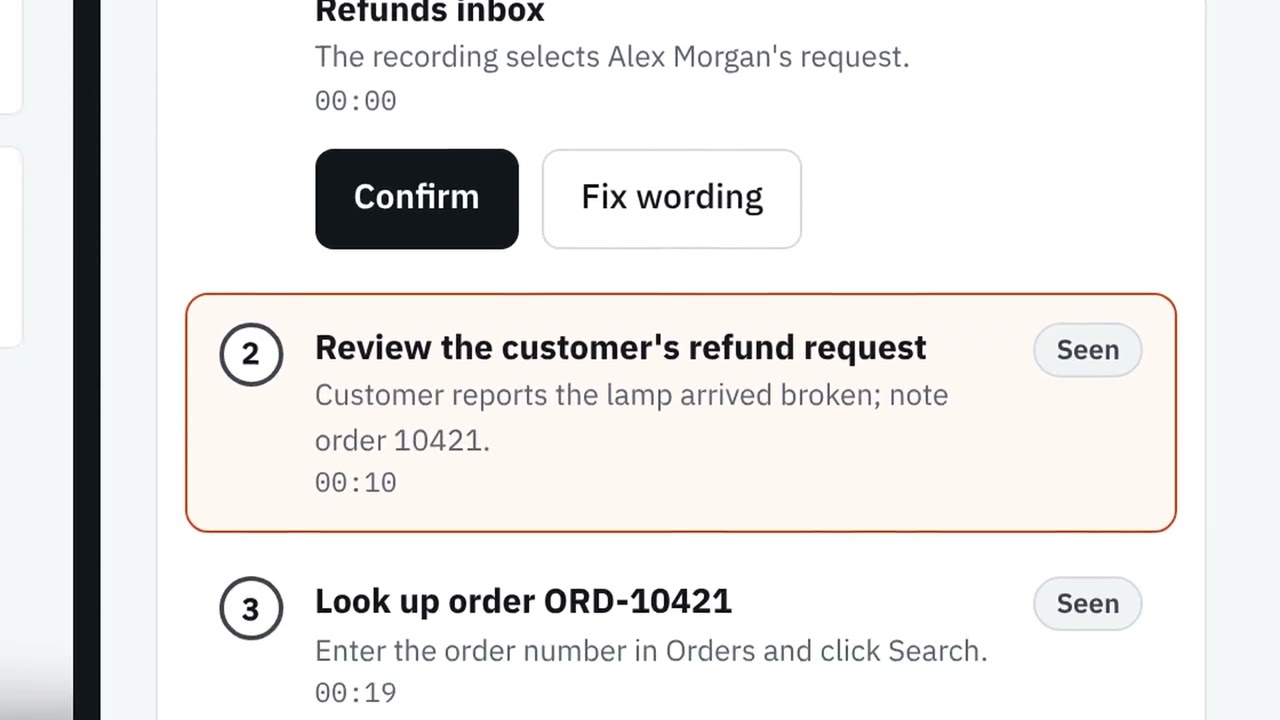
Show it once. Shadow turns an expert's screen recording and narration into a playbook where every step is tied to its source and every assumption is called out. Then an agent does the job back, and stops to ask wherever the recording never showed it. Record, Verify, Replay. Live: https://mukeshkbj--shadow-web.us-east.modal.run (the featured playbook is a real run on the Meta Model API; a second playbook is the same recording run on open weights, Muse Spark Open) The problem: every team has someone who knows how a job is really done, and that knowledge lives in their head. Written procedures skip the exceptions. AI can now write a procedure from a video, but a confident document nobody can check is worse than none. Shadow is built around evidence and uncertainty. An expert records one task and talks as they go. Every step in the playbook carries its timestamp and its source: - Seen: the action is visible on screen - Said: the rule was stated in the narration, quoted word for word and checked against the transcript - Inferred: Shadow's own reading, flagged until the expert confirms it Branches the recording never showed become open questions, never guesses. A deterministic evidence check (plain code, not AI) removes any step it can't find in the recording and downgrades unsupported claims. When screen and voice disagree, Shadow asks instead of picking: in the demo the expert says "I always take the oldest one first" while the inbox is sorted newest first. The expert reviews on one timeline (screen, voice, steps), clicks any step to jump to that moment, confirms or fixes what was inferred and answers the questions. Then Replay: an agent drives the real app from the confirmed playbook, one action at a time, using only the rules the expert said aloud, and stops at every unconfirmed step and unshown branch. Measured, not claimed: against a scripted recording with known timings, screen actions land within 0.5 s on average, and spoken lines within 0.18 s once snapped to Voice Transcribe turns (3.8 s before). On the featured run Replay completed all 8 steps and asked the expert once. Known limits are in the README: e.g. Muse Spark once read £612.40 as £812.40, which is why every step links to its moment in the video for the expert to confirm. All code was written during the hackathon. The demo uses a fictional shop with synthetic data.