WeSolve - Agent Swarm
Built at Meta Global AI Developer Hackathon · Oct 26, 2026 · Remote
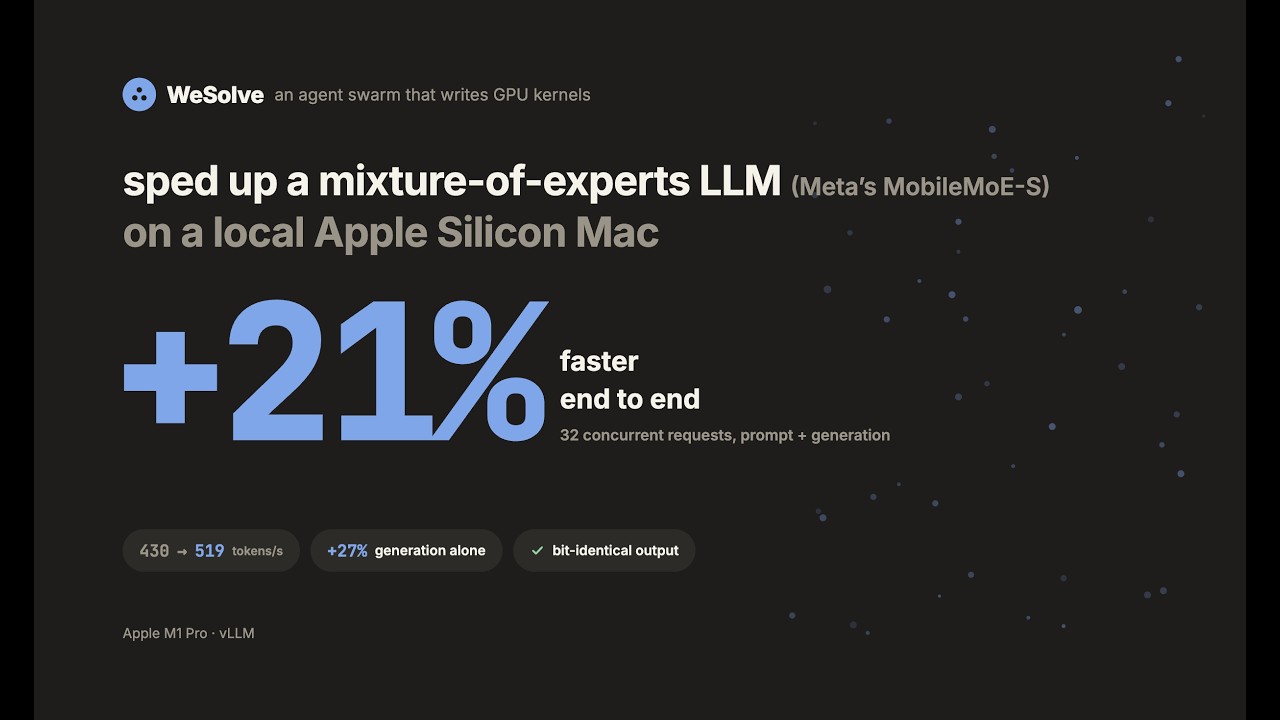
WeSolve is a swarm of AI agents, built on Meta's Muse models, that writes faster GPU code for running large language models on a laptop. The problem: running an LLM locally on an Apple Silicon Mac is slow, and making it faster takes expert, hand-written GPU code (called kernels) that few people can write. We measured Meta's on-device model MobileMoE-S served by vLLM on an M1 Pro and found it used less than a fifth of the GPU's memory bandwidth. Most of the hardware's speed was going unused. The solution: WeSolve gives this job to a team of AI agents. A lead plans the work, explorers study different parts of the code in parallel, a verifier checks their findings, and builders write new GPU kernels. They share what they learn through shared notes. Every change goes to an independent grader that accepts it only if the model's output stays exactly the same, token for token, and the change is actually faster. Each round builds on the last one. The result, after four rounds, on the same Mac, against vLLM as shipped, measured end to end (reading the prompt and generating the answer together): with 32 concurrent requests, the model serves 519 tokens per second instead of 430 with 1,024-token prompts (+21%), and 1,097 instead of 911 with 128-token prompts (+20%). With 8 requests it is 9% faster, and with a single request 6% faster. The output is identical, word for word.