Usta
Built at Meta Global AI Developer Hackathon · Oct 26, 2026 · Remote
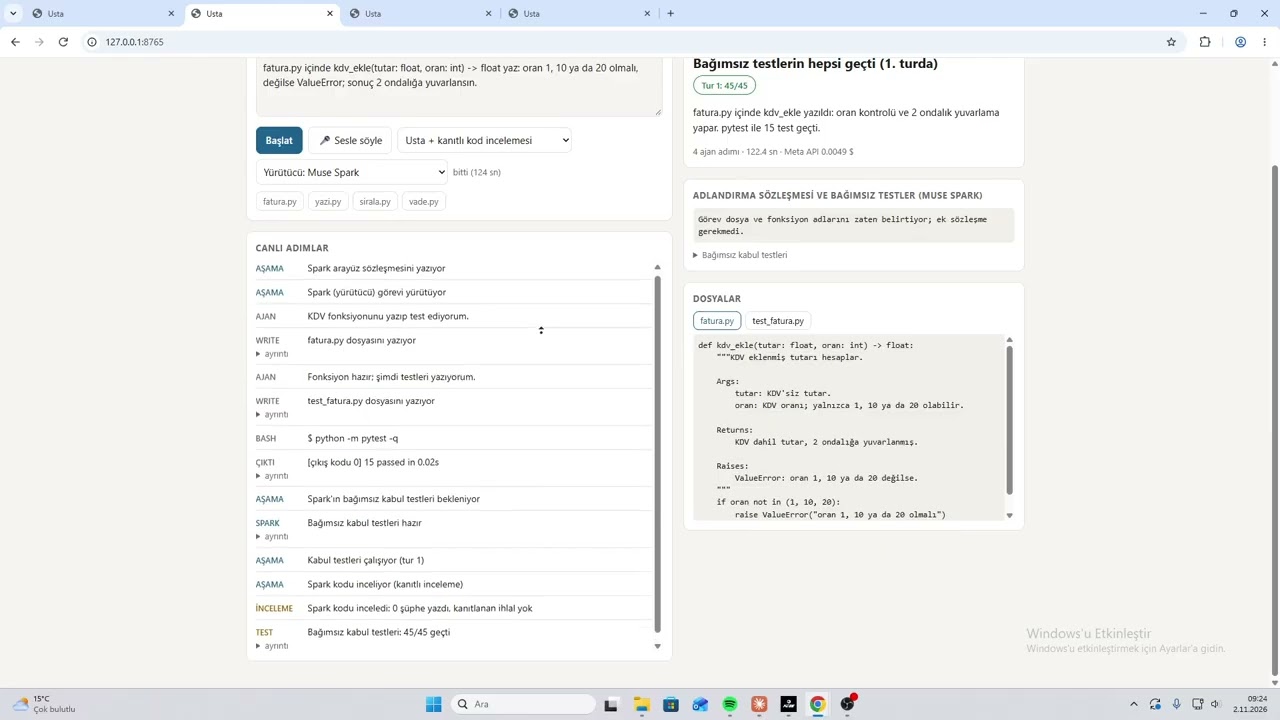
Usta: a Turkish coding agent that shows its evidence. THE PROBLEM (Build for Your World). More than eighty million people speak Turkish, and everyday software for Turkish small businesses is full of local rules: national ID check digits, IBAN mod-97, VAT at 1/10/20 %, prices written as 1.234,50, due dates that slide past weekends and public holidays, the dotted/dotless I. Coding agents can write this code, but they say "done" without evidence, and a non-expert cannot tell whether it works. WHAT USTA DOES. You type or say a task in Turkish; Muse Voice Transcribe turns speech into text. Muse Spark writes a naming contract only when the task leaves file or function names open. An executor (Muse Glimmer 30B on open weights, served by us with vLLM on Modal, or Muse Spark) writes and runs the code with native tool calls (Write / Read / Edit / Bash / Done) in an isolated, network-less workspace. In parallel and in separate calls, Spark writes acceptance tests from the task text alone, plus a reference solution; tests the reference fails are dropped. Failing tests go to a Spark arbiter, which enforces only what the task explicitly requires, and then back to the executor for up to three repair rounds; a round that breaks a passing test is rolled back. The result screen shows which tests passed in which round, which were not enforced and why, the code and the cost. WHAT WE MEASURED, AND THE HONEST RESULT. We built three Turkish task sets generated by Spark, each task with 12-20 hidden tests that neither the executor nor Usta's test writer ever saw, and compared (a) executor alone, (b) executor told to write and pass its own tests, (c) Usta. - Main run, 114 very hard tasks x 3 runs (1,026 runs, Spark executor, isolated WSL runner, strongest verifier: three independent test writers, majority reference filter, mutation testing): a 60.2 %, b 56.7 %, c 57.6 %; c - a = -2.6 points (95 % CI -9.1 ... +3.2). - Usta's "verified" verdict was correct 60 % of the time; the executor's own "done" 63 %. - Earlier runs (157 tasks; 34 tasks with Glimmer and with Spark) point the same way: no mode beat the executor alone significantly. Why: the executor's errors are mostly misreadings of the task, and a verifier from the same model family shares those readings. Our acceptance tests killed 94 % of code mutants of the reference solution: strong against small code bugs, weak against interpretation errors. Coverage, not repair, is the bottleneck. We think this is a useful result for anyone building "LLM checks LLM" pipelines, and every task, hidden test, log and script is in the repo. WHAT USTA DELIVERS TODAY. A Turkish-first agent that works end to end (voice -> code -> tests -> evidence) and a reproducible record of what was checked. It does not make the executor more correct, and we say so. WHO IT IS FOR. Turkish-speaking developers, students and small-business owners who need small pieces of software in their own language; and builders of verification loops who want measured evidence instead of anecdotes.