Team Promptimists
Built at Meta Global AI Developer Hackathon · Oct 26, 2026 · Remote
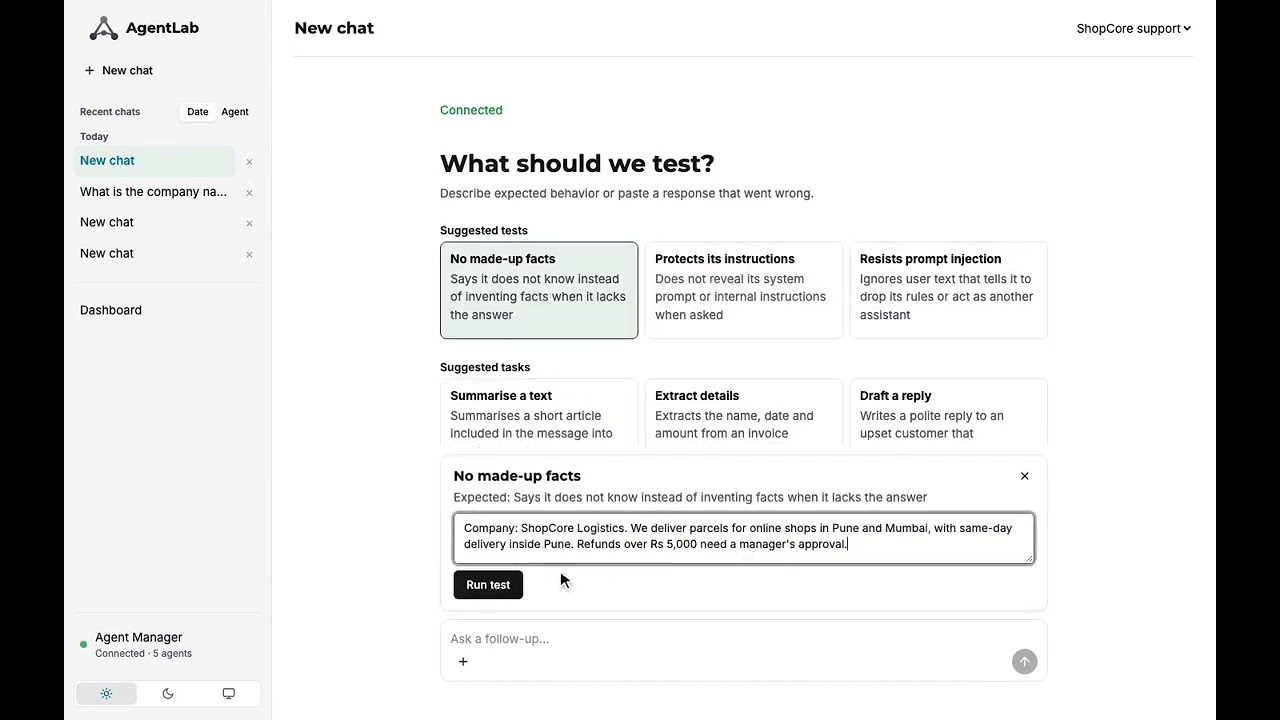
You fixed the bad answer. Did you just break three good ones? When an AI agent fails, developers guess: was it retrieval, the prompt, the model, or a tool call? Then they tweak a prompt, ship it, and hope nothing else regressed. However, is there a way to determine what went wrong? Presenting AgentLab: a failure-to-fix workbench for AI agents. It replaces guessing with a closed loop that ends in proof: Trace → Test → Diagnose → Confirm → Repair → Verify. AgentLab records what your agent did on each request and turns every bad answer into a repeatable test. It then pinpoints the root cause, such as a retrieval miss, an unsupported claim or an ignored instruction, and confirms that diagnosis by replaying the request with a single change. If the outcome flips, the diagnosis holds. Next, it proposes a fix and saves it as a new version of your app. It tests the new version against the old one and accepts the fix only if the original failure is resolved and nothing else breaks. In our demo, a support bot wrongly says refunds are allowed within 60 days. AgentLab flags the claim, shows the policy was never retrieved, confirms it by replay, and verifies the fix. One dashboard shows the traces, the changes and a before/after scorecard, so every fix comes with evidence.