tabs_over_spaces
Built at Meta Global AI Developer Hackathon · Oct 26, 2026 · Remote
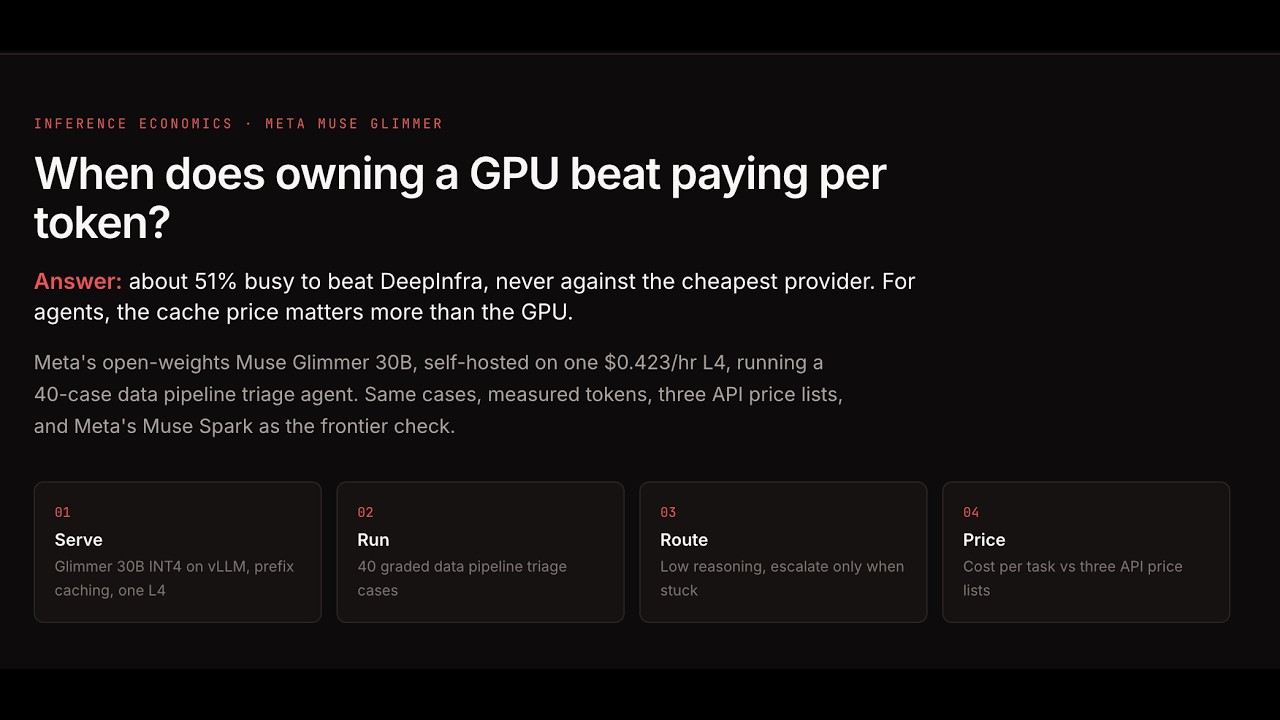
ThinkABR answers a question every team running AI agents faces: when does self-hosting an open model on a cheap cloud GPU beat paying per token? I served Meta’s open-weights Muse Glimmer 30B (4-bit, vLLM) on a single NVIDIA L4 and ran a real agent on it. The agent triages data pipeline failures over 40 graded test cases with tools for logs, code, schemas and SQL. Then I turned the measured tokens, cache hits and throughput into cost per completed task. The answer: a tuned spot L4 beats DeepInfra once it’s about 51% busy, and it never beats the cheapest provider. For agents, the cache price matters more than the GPU. Low reasoning matched high on accuracy (39/40) with about 30% fewer tokens, and an escalate-when-stuck router acts as a safety net. Muse Spark 1.3 on the same harness solved 40/40 at about 5x the cost, so Spark is the quality ceiling and Glimmer is the cost floor. Live dashboard: thinkabr.vercel.app. Built on Meta open weights, self-hosted on my own GPU, so please consider it for Best Build on Meta Open Weight Models.