OneNeuron
Built at Meta Global AI Developer Hackathon · Oct 26, 2026 · Remote
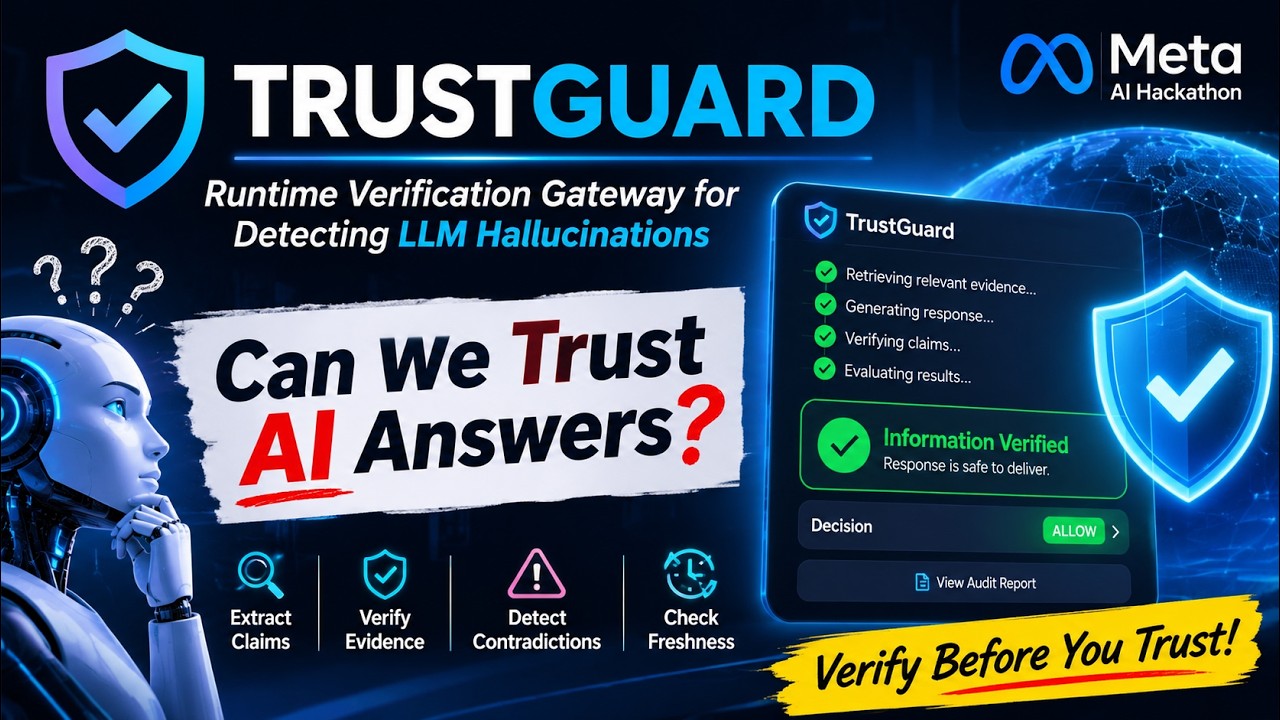
TrustGuard: A Multi-Layered Runtime Verification Gateway for LLM Applications Large Language Models (LLMs) are transforming industries worldwide, but their reliability remains a significant global challenge. Even advanced models can generate hallucinated, outdated, or unsupported information while presenting it with confidence. Existing approaches, including Retrieval-Augmented Generation (RAG), improve access to relevant information but do not guarantee that every generated claim is factually supported by the retrieved evidence. TrustGuard addresses this reliability gap through a multi-layered runtime verification gateway that evaluates AI-generated responses before they are trusted. The system retrieves relevant information from user-provided documents, generates responses using a language model, and extracts individual claims for evidence-based verification. Each claim is classified as SUPPORTED, CONTRADICTED, or UNVERIFIED based on the available evidence. TrustGuard also evaluates document freshness to identify potentially outdated information. Based on verification results, the system makes runtime decisions such as ALLOW, FLAG, BLOCK, or REVISE. When an answer contains incorrect or unsupported information, TrustGuard can attempt to revise the response using available evidence and perform verification again before presenting the revised result. By combining document retrieval, claim-level verification, evidence assessment, freshness evaluation, and runtime decision-making, TrustGuard aims to reduce the risk of hallucinated responses and improve the transparency and reliability of LLM-powered applications. Core Innovation: Rather than relying solely on the language model's generated response, TrustGuard introduces an additional evidence-driven verification layer between AI generation and the final user response.