ApexSentinal
Built at Meta Global AI Developer Hackathon · Oct 26, 2026 · Remote
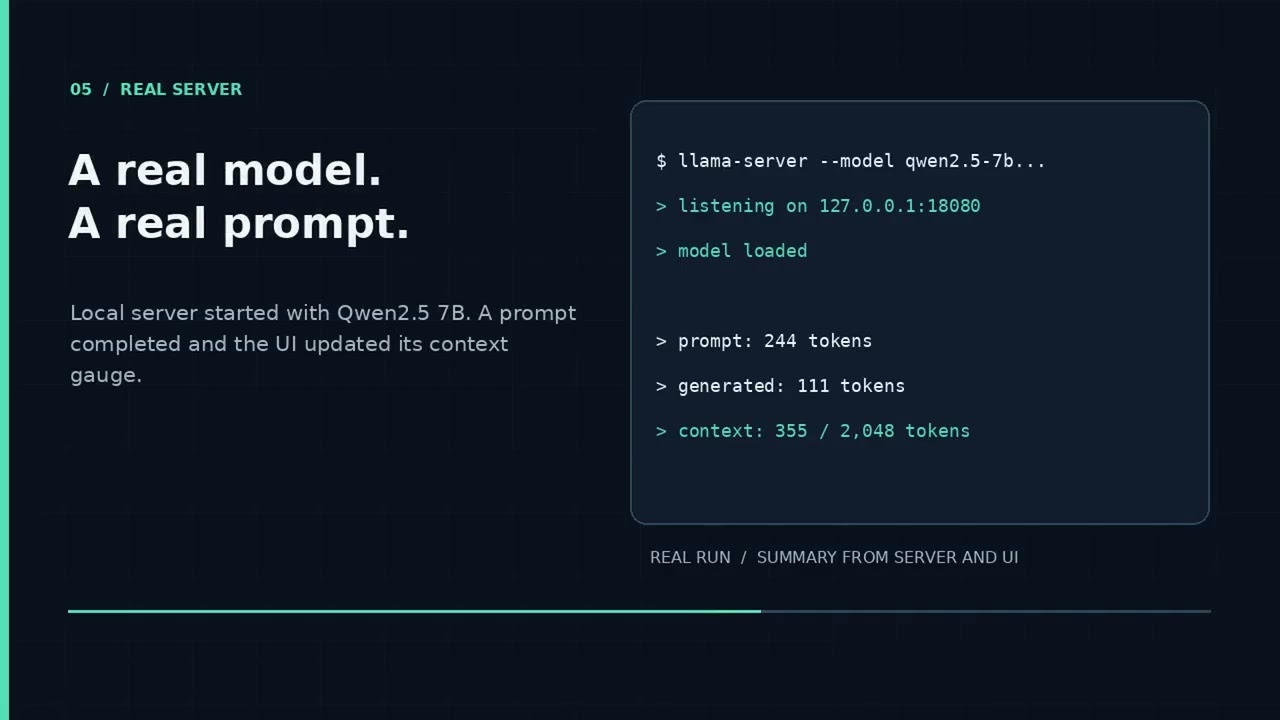
This project, SSD and RAM as an Extended Context Memory System for Large Language Models (LLMs), aims to overcome the memory limitations that prevent AI models from efficiently handling long conversations, large documents, and memory-intensive workloads on consumer-grade hardware. Traditional LLMs rely heavily on GPU VRAM and system RAM to store the Key-Value (KV) cache, which holds information needed to process and maintain conversational context. As the amount of information increases, memory consumption grows, often causing out-of-memory errors, performance degradation, or limitations on the number of simultaneous requests. To address this problem, the project modifies the open-source llama.cpp inference engine by introducing a tiered memory management architecture that utilizes GPU memory, system RAM, and NVMe SSD storage. Instead of keeping all cached information in expensive, limited high-speed memory, the system intelligently manages KV-cache data by retaining frequently needed information in RAM while transferring less frequently accessed data to SSD storage and retrieving it when required. This approach aims to reduce memory pressure, improve hardware utilization, and support larger cumulative workloads without requiring expensive GPU upgrades or relying entirely on cloud infrastructure. The project also introduces configurable memory allocation, automated cache management, and integration with the inference server and its user interface. By making better use of existing hardware resources, the system works toward making local AI inference more affordable, scalable, and accessible, particularly for developers, researchers, and individuals working with limited computational resources. Its extended storage capacity does not automatically increase a model's maximum supported context length, but it provides a foundation for more efficient memory management and future long-context AI capabilities.