Watch Once
Built at Meta Global AI Developer Hackathon · Oct 26, 2026 · Remote
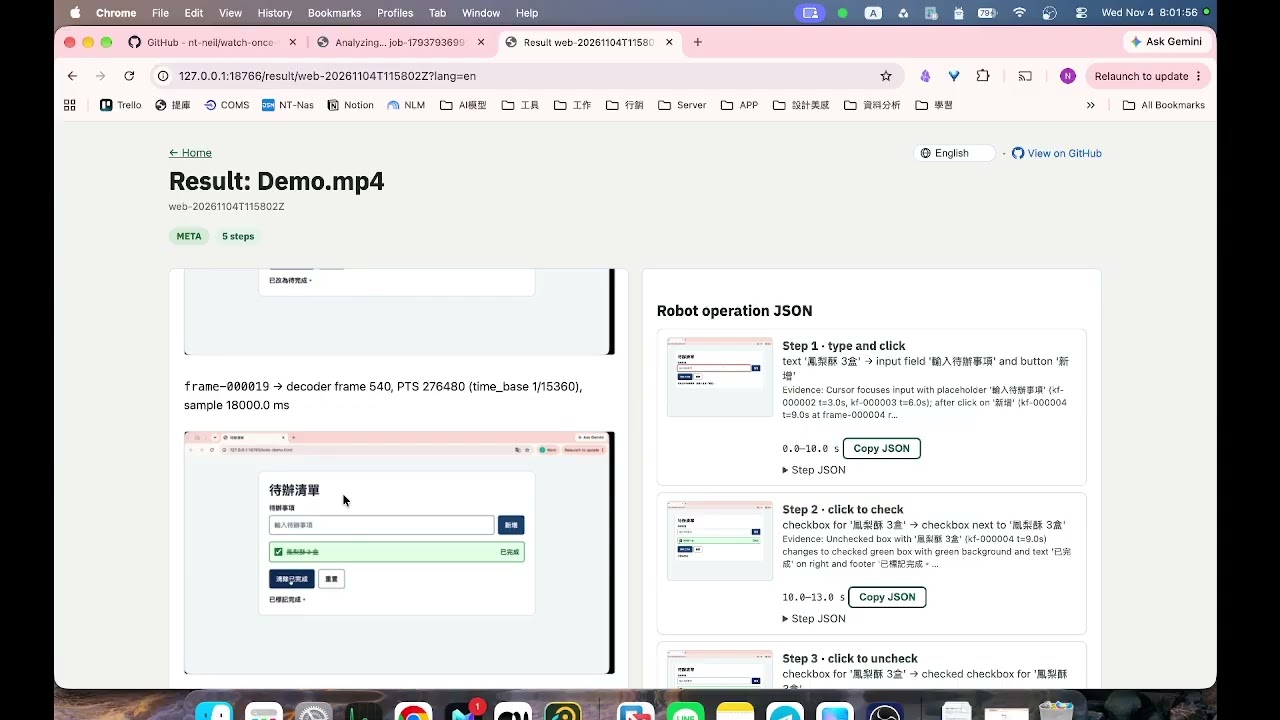
Watch Once, Teach Human and Robot turns one teaching video into two outputs: a step-by-step manual for people (every step cites its source frames) and a validated operation JSON for machines (object / action / target / pre / done per step, plus per-step evidence). Problem: how-to videos teach humans, but every robotics or automation team re-watches and re-annotates them by hand, and nobody publishes where video models stop being reliable. We built an honest, reviewable bridge from "the video shows how" to "machine-readable steps", with the failure cases written down. What it does: upload a video (up to 3 minutes / 100 MB). A frozen pipeline probes it, extracts frames at original resolution, asks Meta Muse Spark for timed steps, validates the JSON strictly, and renders a manual with frame thumbnails. Default setting is prompt v6 + original-resolution keyframes, with an optional 3-run majority vote. Outputs also export to LeRobot-style task/subtask annotation, a VLA instruction sequence, and planner steps (annotation layer only — never run on a real robot). The same pipeline is available as a local web UI (real Meta inference only, no mock, 5 UI languages), a CLI, and an MCP server for agents. Measured, not claimed: on frozen held-out sets evaluated once, the default passes 4/7 (set 1) and 6/10 (set 2); videos with no procedure correctly return 0 steps. Known limits: similar adjacent steps get merged and voting cannot fix that; sub-second UI events are missed; visually similar assembly steps are confused. Iteration took 248 paid calls (~US$8.52), about US$9 and over 250 real runs in total.