Dissonance Router
Built at Meta Global AI Developer Hackathon · Oct 26, 2026 · Remote
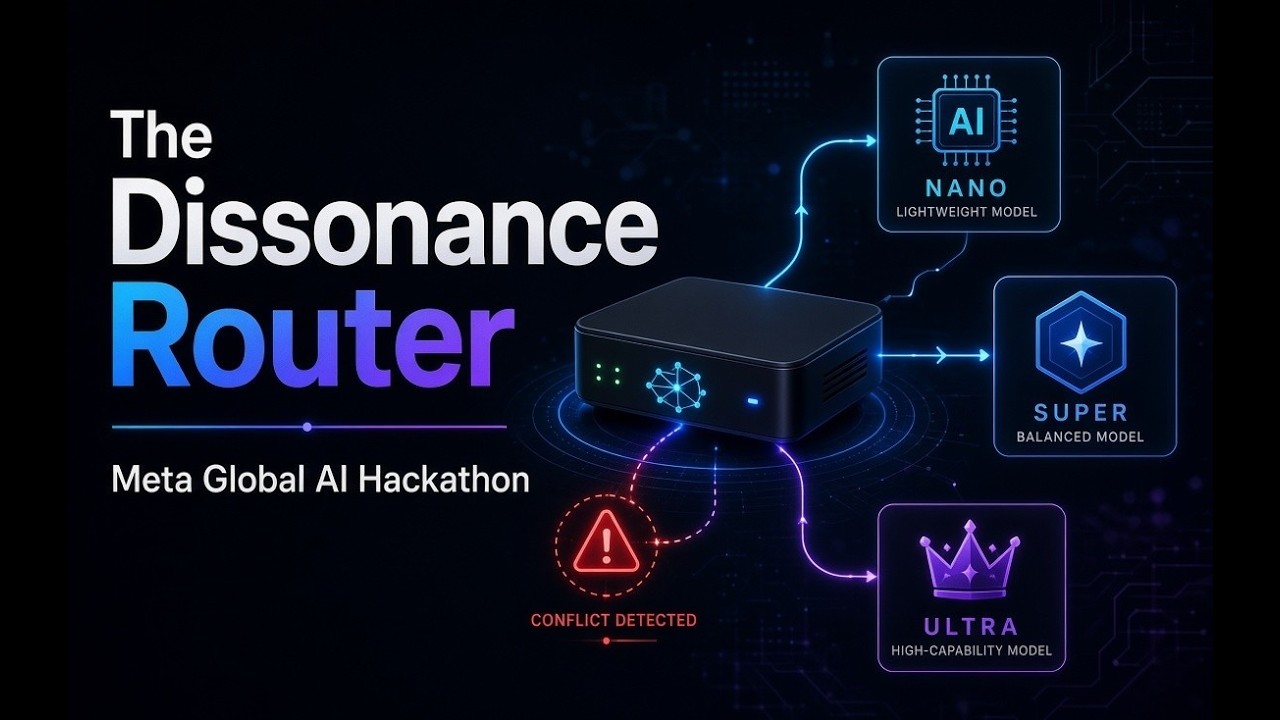
Most AI assistants send every message to the same model, so a simple question costs as much as a difficult one. They also never notice when what a user says they want differs from what they actually do. The Dissonance Router addresses both problems. For each message, it chooses the model tier and the amount of reasoning effort from the question itself and from the user's recent behaviour, and it shows the reason in plain words beneath the answer. Its memory is conflict-aware. Calm conversations are compressed to their outcome. Contradictory turns are kept verbatim, marked as unresolved, and retained three times longer. When the user accepts a preference, those turns are folded into a single note and removed from the model's context. Deleting a memory always takes priority. In 200 live runs (260 graded turns), the router was 78.4% cheaper than always using the top tier, chose the correct tier 89.6% of the time, and reduced waiting time by 66.8%. In a blind comparison, the smallest tier was judged as good as the largest in 60% of cases (36 of 60), at a median of one-sixth of the cost. A live usage ledger records the tokens, cached tokens, cost and latency of every call.