Montivo
Built at Meta Global AI Developer Hackathon · Oct 26, 2026 · Remote
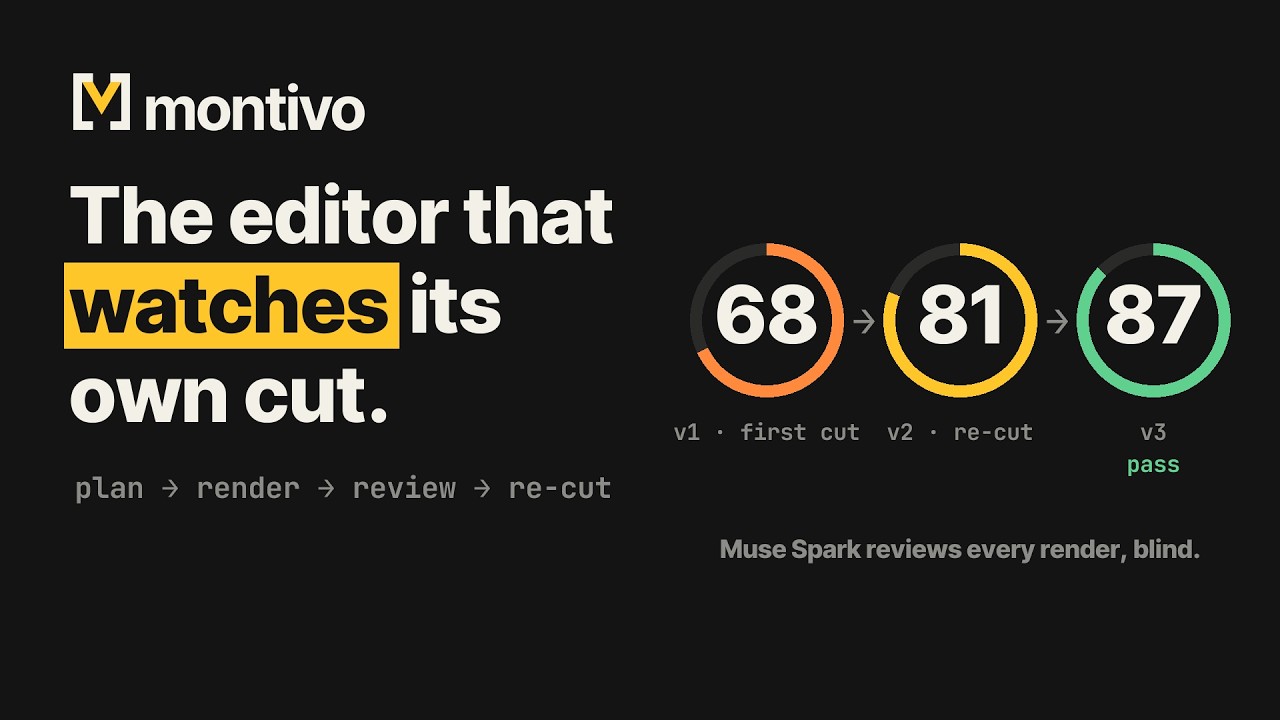
Montivo is an agent-first video editor that reviews its own work. Give it raw talking-head footage and a one-line brief: Meta's models transcribe every word, track the speaker, watch the footage and plan a paper edit; Montivo cuts on word boundaries, keeps the speaker in a 9:16 frame and renders a captioned vertical cut. Then Muse Spark 1.3 watches that render blind, like a viewer, scores it against an editor's rubric and returns fix operations with timestamps. Montivo patches its edit list, renders and reviews again until the cut passes or a guard (budget, passes, a regression, a repeated fix) stops it. The reviewer cannot pass a cut on its own say-so: Muse Voice re-transcribes every render, and a word lost at a cut edge, the head out of frame, a caption over the face or an open major issue holds the pass and becomes a fix. On my own 69-second pitch the first cut scored 68: a title card over silence and a misheard caption. The agent fixed both (81), I retyped four more misheard captions in the editor, and version 5 scores 87 with every measured check clear, for $0.30 in model calls. On the code of 30 October the same clip passed its first review at 88 for $0.22, with no loop and no human edit. How much to trust the reviewer: on 28 blind development reviews (22 cuts with a planted fault, 6 clean) it flagged 91 % of the faults as blocker or major; 2 of 22 faulty cuts still passed. The checks were tuned on those cuts, so this is not a held-out error rate. It does not pass everything: a four-astronaut NASA clip (66), a multi-camera TEDx talk (70) and a walk-and-talk (82) ended without a pass. Who it is for: I edit short vertical video for small businesses every week, mostly the same mechanical choices. Montivo does that pass and shows its reasoning; the human stays in charge in a full editor that opens in Live: split, trim, move or delete clips, delete words in the transcript, retype a caption, pick a caption style, add a music bed that ducks under the speech, all playing at once in the browser, and nothing becomes a version until Make Version renders it once ($0). Or ask in plain words ("add some music and make the captions bolder") and Ask Montivo turns it into edits, with a preview and its cost for a structural change. Export to 9:16, 4:5 or 1:1 with caption files, a cover and post text. Try it: https://bgaravelos--montivo-web.us-east.modal.run (press "Enter as guest", no password), or the keyless samples in the README. Everything in the repository was written from scratch during the hackathon, from the kickoff on 26 October. The concept and the name come from an earlier personal project of mine; none of its code is used. Four API test calls made shortly before the kickoff are disclosed in the README. The demo video is narrated by an AI voice cloned from my own recording; Montivo itself calls Meta models only. My own entry as an individual: Vasileios (Billy) Gkaravelos, Athens.