Suman Kumar Sah
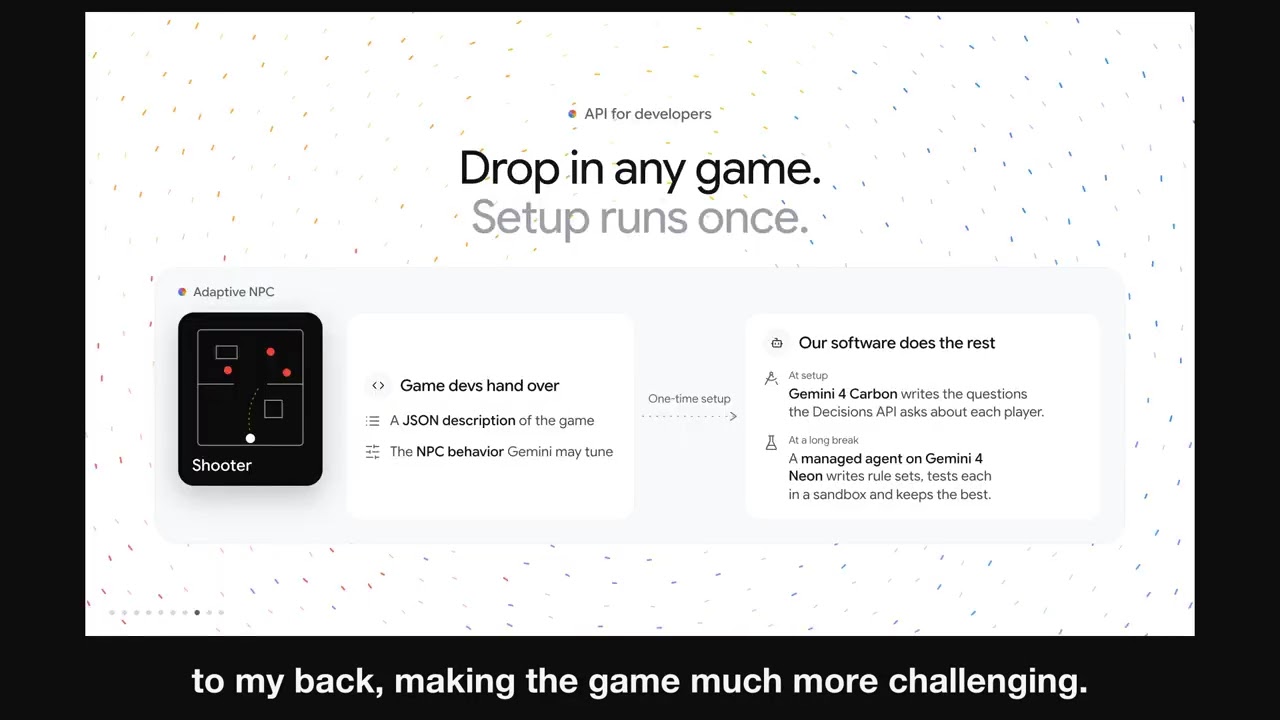
Gemini 4 NYC HackathonSecondLook is a self-verifying extraction agent for prior-authorization (PA) forms, which still arrive as faxes and phone photos. It turns a messy handwritten form image into 15 structured fields and marks each one verified, corrected or needs_human, with a full trace of what every model said so a person can audit it. When an AI misreads a member ID, nobody finds out until the claim fails. The expensive mistake is the silent error: a field that's wrong and never flagged. SecondLook is built around that metric. Gemini 4 Hydrogen reads all 15 fields and gives a confidence for each. Python validators check formats (NPI, CPT, ICD-10, dates). Gemini 4 Neon then reads the same form blind, without seeing Hydrogen's answer, and Python compares the two reads. If they disagree, confidence is low or a format check fails, Gemini 4 Carbon re-reads just that field from a deskewed, 2x-upscaled crop. A field only counts as verified when two independent reads agree. The evaluation is where most of our time went. We generated 50 synthetic forms (Faker data, handwriting fonts, light/medium/heavy fax-style degradation) and committed them before writing any prompt (commit efcad6a), then never opened them while tuning. The baseline is one strong Gemini 4 Carbon call with the same schema, flagged by its own confidence. On 750 fields: silent errors were 0.5% vs 0.7% for the baseline (4 vs 5 fields, basically a tie). Accuracy 95.2% vs 94.7%, review rate 13.7% vs 10.8%, and cost $0.034 vs $0.012 per form. We don't claim it beats a single strong model. We report every version (v1 1.7% silent, v2 2.0%, v3 0.5%) and what each fix taught us. The big one: two similar models misread O/0 and I/1 the same way, so their agreement is weak evidence. Both systems drop below 80% accuracy at degradation step 4. Last experiment (v4): Gemini's confidence is poorly calibrated (92% of fields score 0.9+, and 16 of 36 errors hide there), so we added the Gemini Decisions API for a calibrated per-field probability, threshold picked on 20 separate dev forms. It ranked fields better than confidence, but flagged 13 more fields, none wrong, so silent errors stayed at 4. We kept v3 and report v4 as a negative result. Limitations: synthetic handwriting is cleaner than real, the crops depend on a known form layout, and we set some thresholds after seeing results. Stack is Python, google-genai, FastAPI and one static HTML page
Team