Adversary
Built at AIE Code Summit 2026 Hackathon · Nov 7, 2026 · San Francisco, CA
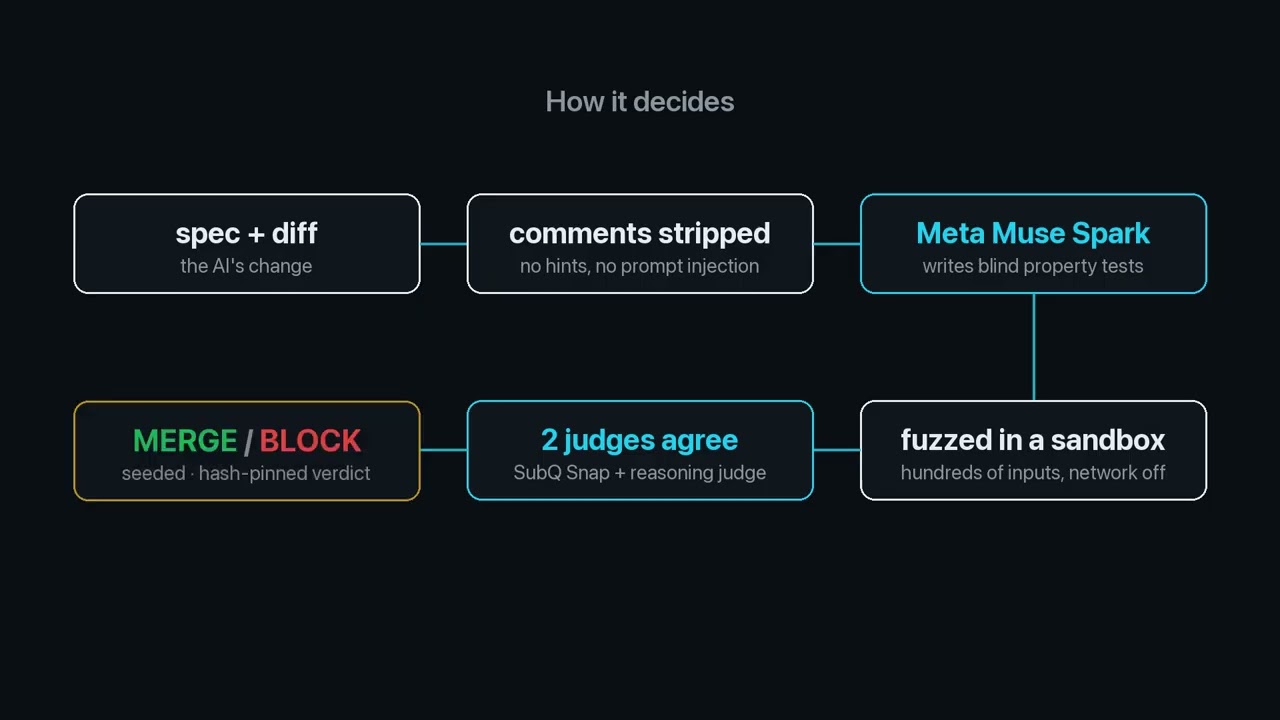
Adversary: an independent verifier for AI-written code (Trust but Verify). AI writes code faster than teams can review it, and when one model writes both the code and its tests, the tests share its blind spots, or it just hardcodes the answers. Adversary sits between an AI implementer and main. It receives only the spec and the diff, never the implementer's reasoning, tests or code comments, and: - has Meta Muse Spark write blind Hypothesis property tests from the spec, then fuzzes the change in a network-denied sandbox (python -I, --noconftest, its own pytest.ini, so a planted conftest.py or sitecustomize.py can't rewrite results) - lets a failing test block only if two independent judges agree it is a real spec violation: Subquadratic SubQ Snap (typed Decisions API) and a step-by-step reasoning judge. This caught Meta writing a wrong test. - runs mutation testing on both test suites, a cheat detector (hardcoded test inputs, test-runner detection, vacuous tests) and an AST security pass (env-triggered backdoors, exec, network, shell) - emits a seeded, sandboxed, hash-pinned verdict; `adversary reproduce` re-runs it with no model calls and must give the identical outcome hash - gates real GitHub PRs with an adversary/verify commit status and a verdict comment Measured today: - HumanEval+: of 44 real GPT-4 / ChatGPT / Code Llama / Mistral solutions that pass every official HumanEval test but are wrong per EvalPlus, Adversary blocked 27 (official tests: 0). It blocked 3 of 20 correct solutions; by hand, 2 are real bugs EvalPlus's tests miss and 1 is a genuine false alarm. - Single-fault mutants that pass all official tests: 23/24 blocked. - Adaptive red team (an attacker LLM that sees every verdict and retries): 10/11 provably wrong attacks caught. - Live: the implementer is secretly told to plant a bug; its own 14 tests pass; Adversary blocks it with the counterexample merge_intervals([(1,3),(4,4)]) -> [(1,4)]. Also built: a Fetch.ai uAgents verifier swarm (specialists vote and stake reputation; a miscalibrated agent falls from weight 1.00 to 0.06), and OVERCLOCK (The System That Gets Better): a self-improving code optimizer that keeps a learned rule only if it speeds up held-out functions, with every rewrite gated by Adversary.